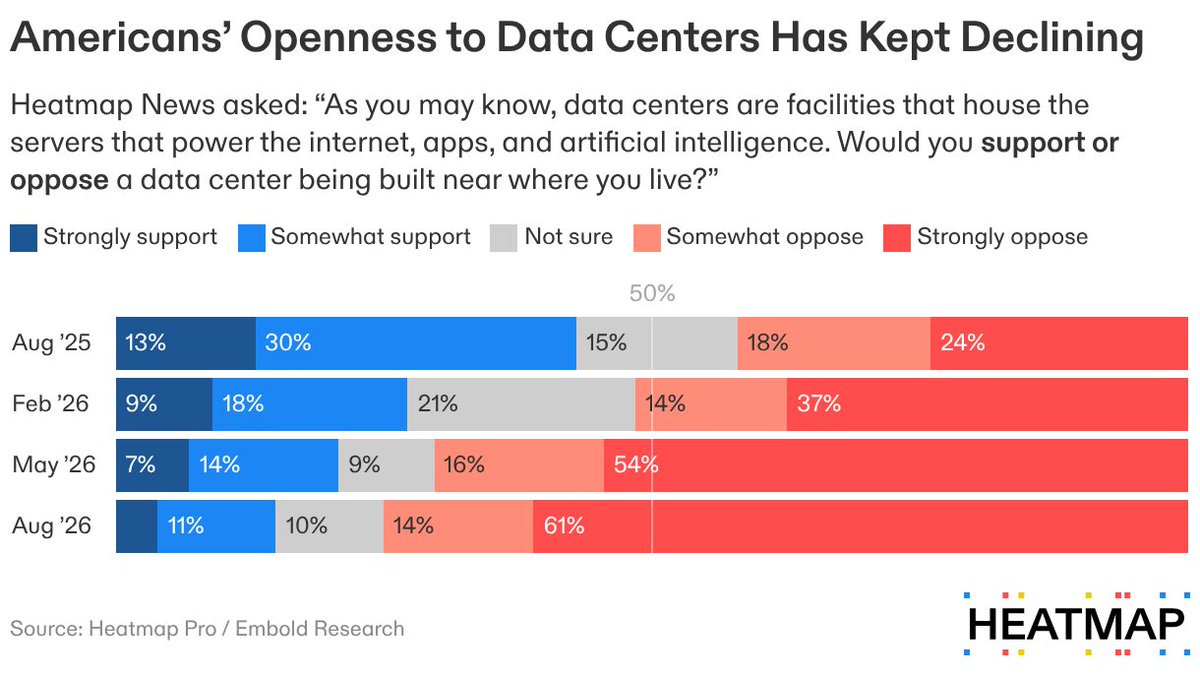
News / #hardware Tag Hardware 500 articles archived under #hardware · RSS Sign in to follow r/LocalLLaMA community 1mo ago Today I hit 181 toks/s (aggregate) on Qwen3.8-Flash-Next on 2x DGX Sparks Hey all, and hello fellow DGX Spark-ers! Today I managed some pretty crazy numbers: 181 tok/s aggregate on 2× DGX Spark on Qwen3.8-Flash-Next at 512Kcontext (2.8M kvc) I hit 181 tok/s aggregate today across a multi-agent fleet on a 2-node DGX Spark cluster. Single-stream decode… 22 Stratechery (Ben Thompson) community 1mo ago 2026.35: Internet Hype and Real World Change The best Stratechery content from the week of August 24, 2026 including the breaker's advantage, the new battle for HDMI1, and how data center discourse ends. 7 arXiv — Machine Learning research 1mo ago ClusterAttention: A training-free speedup of bidirectional attention arXiv:2608.26965v1 Announce Type: new Abstract: This paper introduces ClusterAttention, a general training-free speedup of bidirectional attention layers. Existing sparse attention methods either rely on structure in the input, such as order in language or spatial proximity in… 13 arXiv — Machine Learning research 1mo ago Inductive Correlation Clustering with Graph Neural Networks arXiv:2608.27153v1 Announce Type: new Abstract: Correlation Clustering (CC) is a natural formulation of clustering in combinatorial optimization, which uses a graph representation of the input and does not require a pre-specified number of clusters. Given $n$ objects and a… 6 OpenAI official-blog 1mo ago Supporting Thailand’s next generation of AI startups OpenAI and Thailand’s MHESI launch an eight-week accelerator helping 10 health, wellness, and education startups turn AI prototypes into trusted products. 26 ThursdAI news-outlet 1mo ago NVIDIA Buys Hugging Face! GLM-5.3-Flash, Qwen4 Preview, Gemini Omni 1.1, and the Datacenter Debate w/ Andy Masley From CoreWeave - join Alex and ThursdAI co-host, covering the last week of the summer in AI, with 4 Flash models, Datacenter debate & more AI news 11 Ars Technica — AI news-outlet 1mo ago AI industry says Trump plans to tax chips in the “single dumbest way imaginable” Tech industry is perplexed by Trump’s plan to win AI race by taxing data centers. 35 TechCrunch — AI news-outlet 1mo ago AI’s memory crunch is coming for Android apps Google is setting new memory-use limits for Android apps as AI data centers contribute to hardware shortages that could leave lower-cost phones with less memory. 17 Hugging Face Daily Papers research 1mo ago Real-TurnTurk: A Multimodal Turkish Corpus for Turn-Taking Prediction Abstract A multimodal Turkish dialogue dataset and genetic algorithm-optimized interpretable rules are used to predict turn transitions from visual, acoustic, and linguistic cues. Generated by thinkingmachines/Inkling-Small Turn-taking is a basic organizational feature of human… 10 arXiv — Machine Learning research 1mo ago Resolving Multi-Modal Regression by Difference-Quotient-Based Clustering:Fast Coarse Conditional-Label Assignment arXiv:2608.25467v1 Announce Type: new Abstract: Multimodal regression suffers from the mean-collapse pathology: under squared loss, an unconstrained regressor converges to the conditional mean, which for K > 1 lies away from all modes. We attribute this failure to pairwise… 31 arXiv — Machine Learning research 1mo ago Individual Fairness in Hierarchical Clustering arXiv:2608.25586v1 Announce Type: new Abstract: Hierarchical clustering produces ultrametric representations that impose strong global geometric constraints and may distort local similarities in ways that disproportionately affect individual data points. We study hierarchical… 6 arXiv — NLP / Computation & Language research 1mo ago Belief Cascades Drive Persuasion in LLM Agent Networks arXiv:2608.25152v1 Announce Type: new Abstract: Multi-agent LLM systems increasingly debate answers, coordinate research, simulate users, and mediate information flows, making agent-to-agent persuasion a basic but undermeasured capability. We introduce a controlled testbed for… 28 TechCrunch — AI news-outlet 1mo ago Amazon just tripled its order of Nvidia chips over ‘surging demand’ Amazon is adding another 2 million Nvidia GPU chips to its data centers over the next two years. But this extended partnerships stretches beyond buying more chips. 28 arXiv — Machine Learning research 1mo ago Transformer Accelerator (TFA): A Macro-Op INT8 Hardware Chip for Transformer Inference and Machine Translation arXiv:2608.23582v1 Announce Type: cross Abstract: We present the Transformer Accelerator (TFA), a synthesizable, parameterizable INT8 memory-to-memory engine for transformer inference. One time-multiplexed datapath handles prompt processing and autoregressive generation. TFA… 38 TechCrunch — AI news-outlet 1mo ago OpenAI loses a top data center exec, as stream of high-profile departures continues Before Malone left, OpenAI had already reshuffled its infrastructure org, shifting his reporting line away from President Greg Brockman and putting Vice President Sachin Katti in charge of the group. 36 The Information — AI news-outlet 1mo ago Why Revenue Is Hopping at Data Observability Startups A cluster of startups taking on database giants Snowflake, Databricks and Datadog are experiencing a revenue windfall thanks to rising adoption of AI agents. That could lead to a wave of startup dealmaking, from new investments to M&A. Earlier Tuesday, I reported that… 18 r/LocalLLaMA community 1mo ago Peak Portable Personal Datacenter Portable rig for Qwen3.8-27B-BF16 200K+ token prompts. My work Panasonic Toughbook + the T1 + power brick + headphones all fit in my lunchbox. Need the BF16 for huge context highly sensitive document OCR, image analysis, aggregation and summarization. I've done a ton of testing… 35 r/LocalLLaMA community 1mo ago Apple unveils a more powerful Mac mini featuring the all-new M6 and M5 Pro "A 12-core GPU, also with two more cores than before, now includes Neural Accelerators in each core for the first time on Mac mini, resulting in up to 4x faster AI performance and 2x faster graphics than Mac mini with M4. In addition, the all-new Dual 16-core Neural Engine… 31 OpenAI official-blog 1mo ago Jalapeño’s first results show industry-leading speed and efficiency in AI inference Jalapeño is a custom inference chip from OpenAI that delivers faster, more power-efficient AI inference, with higher throughput and lower latency for modern models. 34 arXiv — NLP / Computation & Language research 1mo ago Real-TurnTurk: A Multimodal Turkish Corpus for Turn-Taking Prediction arXiv:2608.22071v1 Announce Type: new Abstract: Turn-taking is a basic organizational feature of human conversation and remains difficult to model in natural, synchronous dialog systems. While existing research has explored multimodal approaches and large language models for… 30 arXiv — NLP / Computation & Language research 1mo ago Context-Aware Cluster Decoding: Semantic Anchor-Driven Coherence in dMLLMs arXiv:2608.22367v1 Announce Type: new Abstract: Diffusion multimodal large language models (dMLLMs) frequently produce long-form outputs marred by semantic drift and repetition, with quality generally degrading as output length increases. We identify two structural deficiencies… 4 r/LocalLLaMA community 1mo ago To all of you who have bought Chinese ASICs, how have they been? as we all know to get anything good and modern for nvidia/amd if you are lucky u can give up your kidneys as a down payment, but the chinese accelerators have a huge value proposition, if ur willing to invest the time and tokens porting frameworks to them. To whoever owns them,… 15 Don't Worry About the Vase community 1mo ago The American People Really Hate Data Centers There are at least five different core questions around data centers and their politics. 17 NVIDIA Developer Blog official-blog 1mo ago Giga-Scale AI and the Ethernet Evolution: How Spectrum-X Ethernet Rewrites the Rules The massive growth of generative AI has fundamentally altered data center design. As distributed model training scales to span hundreds of thousands of GPUs,... 34 NVIDIA Developer Blog official-blog 1mo ago How NVIDIA Groq 3 LPX Unlocks Ultrafast Interactivity at Long Context on NVIDIA Vera Rubin NVIDIA Groq 3 LPX is the interactive AI inference accelerator for the NVIDIA Vera Rubin platform. At the core of the platform is NVIDIA Vera Rubin NVL72, the... 15 The Information — AI news-outlet 1mo ago Nvidia to Raise Flagship AI Chip Prices 17%, Server Makers Say Prices for Nvidia’s Grace Blackwell and Vera Rubin chip systems are set to rise about 17%, The Information reported Saturday . The price jump adds to a growing array of cost surprises for cloud providers and other data center developers, including unexpected power delays ,… 21 The Information — AI news-outlet 1mo ago Nvidia Invests in Data Center Power Firm, Preps Multibillion-Dollar Perplexity Deal Nvidia acquired a minority stake in Cloverleaf Infrastructure, its third equity investment in rapid succession in firms that secure real estate and electricity access for data centers in the U.S. The move is part of Nvidia’s race to lock up data center capacity for its full AI… 17 Smol AI News news-outlet 1mo ago not much happened today **OpenAI** announced benchmark results for its custom inference chip **Jalapeño**, showing **1.5–1.9×** better efficiency and **1.7–3.6×** lower latency compared to NVIDIA **GB200/GB300**. Deployment starts by year-end with **Gen 2** and **Gen 3** in development. The chip runs… 9 arXiv — Machine Learning research 1mo ago Meta-clustering of milk mid-infrared spectra identifies dairy cow groups associated with negative energy balance in early lactation arXiv:2608.20653v1 Announce Type: new Abstract: Clustering methods have been used to identify distinct groups of milk samples, cows, or herds. Fourier-transform infrared (FTIR) spectroscopy, particularly mid-infrared (MIR) spectroscopy, has been applied to individual cow milk… 36 r/LocalLLaMA community 1mo ago I trained a 1.57B-parameter Dreamer 4 World Model from scratch for under $150 My first attempt didn't work. I built on Genie's architecture and the videos looked great, but the controls barely did anything. The effect of a keypress was basically zero. Genie learns its actions unsupervised into 8 codes, and that was too loose a grip for us. So I scrapped… 33 r/LocalLLaMA community 1mo ago “The All Spark” Cluster: Upgrading from 16 - 36 DGX Sparks Earlier this year I posted about building what at the time I believe was the first 16x DGX Spark Cluster. I’m now adding 20 more Sparks to the cluster in my homelab server rack, giving me 4.6TB of unified memory. • 36x Sparks • 1x 200Gbps FS 24 x 200Gb QSFP56 + 8x 400Gb Switch •… 18 r/LocalLLaMA community 1mo ago Current best model for narrative, chat, prompt creation (so basically everything except agentic coding)? - 5090 Im looking to set up a new local llm (probably on unsloth studio as that seemed to be doing pretty well last time I tested it). This one won't need to do agentic coding or app building or anything (not this time) but instead more 'text' based tasks such as - being given… 10 The Information — AI news-outlet 1mo ago America Really, Really Hates Data Centers • The Big Read: AI promises to cure cancer. Scientists feel existential dread • The new robotics ‘ arms race ’: Who can do the craziest hype video? • Plus, Recommendations—our weekly pop culture picks: “ Dan Taberski’s Manifesto ,” “ A Tender Age ” and “ The End of Oak Street ”… 18 TechCrunch — AI news-outlet 1mo ago Nvidia partners with data center developer Cloverleaf Nvidia continues to pour money into data center development — just as AI data centers bring lots of money into Nvidia. 9 The Information — AI news-outlet 1mo ago Nvidia is Using Land and Electricity Deals to Lock In Its Hardware Bundle Nvidia is racing to lock up data center capacity for its AI hardware before its rivals do. On Friday, the company announced it had acquired a minority stake in Cloverleaf Infrastructure, its third equity investment in rapid succession in firms that secure real estate and… 25 r/MachineLearning community 1mo ago On-prem MLOps in a hospital: advice needed for production monitoring of self-built and vendor models? [D] TL;DR: Hospital, fully on-prem OpenShift cluster. Multiple teams building prediction models, so we’re setting up a self-service platform with boundary policies. Evaluating ClearML vs OpenShift AI for the full MLOps lifecycle. Both look fine for development/deployment, but… 35 Marcus on AI community 1mo ago Data center madness Two estimates of how crazy AI Capex has gotten, and four new signs that public opinion has totally soured 37 r/MachineLearning community 1mo ago I have a mid-sized GPU cluster and was thinking about giving free compute [D] I have built an on-prem GPU cluster, 8 nvidia 16GB GPU's and 256GB CPU RAM, 50TB HDD and several TBs of SSDs. I have used it, and currently use it, for ML/AI research. But that research is not constantly running jobs, sometimes I use it heavily and other times it's idle. I was… 12 NVIDIA Developer Blog official-blog 1mo ago GPU-Accelerated Clustering for Financial Instruments at Scale Use AdaptGrow, a GPU-accelerated matrix factorization algorithm, to turn rolling correlation and tail-dependence matrices into hard clusters, soft factor... 23 NVIDIA Developer Blog official-blog 1mo ago Maximizing AI Factory Performance per Watt with NVIDIA DSX MaxLPS AI factories are power-constrained industrial systems. The question is no longer how many GPUs fit in a data center, but how much AI output each available... 9 TechCrunch — AI news-outlet 1mo ago Starcloud raises $250 million for orbital data centers as launch options dry up There's about to be a big fight to secure access to space. 31 arXiv — Machine Learning research 1mo ago Clustering and Token Denoising for Faster and More Robust VLMs arXiv:2608.19285v1 Announce Type: cross Abstract: Recent Visual-Language Models (VLMs) have enhanced the capabilities of pre-trained LLMs by adding vision tokens alongside text, with approaches like LLaVA showing impressive results. However, the computational burden of… 29 TechCrunch — AI news-outlet 1mo ago Ok, can we actually cool data centers with our pee? Jason Kelce joked that people should cool data centers with their pee, rather than potable water -- his suggestion is not completely ludicrous. 26 The Information — AI news-outlet 1mo ago Nvidia to Reportedly Pay $6 Billion in Licensing and Hiring Deal with AI Model Startup Poolside Nvidia has agreed to pay $6 billion to license AI model-development software from startup Poolside, the startup told investors in a letter first reported by Newcomer . Poolside was an early developer of a coding AI agent and pivoted to developing data centers before releasing… 6 Hacker News — AI on Front Page community 1mo ago Show HN: I trained a 125M model to autocomplete piano on-device I trained a 125M-parameter transformer to autocomplete piano performances in real time (~108 notes/sec on an iPhone 15). The idea is basically GitHub Copilot or Tabnine, except instead of prompting it with code, you prompt it by playing a few notes on a MIDI piano. The model… 38 r/LocalLLaMA community 1mo ago TinySearch v0.6.1 - still a lightweight web research tool for local LLMs, now with bring-your-own-browser support Hey everyone, Posted TinySearch here a few versions ago and got a bunch of useful feedback, so figured I'd post an update because the thing has changed quite a bit since then. Repo: [ https://github.com/TinySuiteHQ/TinySearch]() The basic idea is still the same: TinySearch is a… 30 r/MachineLearning community 1mo ago About the impact of grouping classes in multiclass classification [D] A premise: I hope this question is "worth" of this subreddit, I did a decent amount of research before posting, I thought it was potentially interesting enough for it, but possibly not basic enough for r/learnmachinelearning . Is there any agreement/indication about how harmful… 10 arXiv — Machine Learning research 1mo ago ERASE: EaRly bAckpropagation SchEdule for Faster Training of Modern Recommendation Systems arXiv:2608.18469v1 Announce Type: new Abstract: Lightweight proxy models enable rapid experimentation without repeatedly training frontier-scale systems, but their small kernels often leave modern accelerators underutilized. Conventional training compounds this inefficiency by… 20 arXiv — Machine Learning research 1mo ago LLM-Powered Predictive Decision-Making for Sustainable Data Center Operations arXiv:2608.18503v1 Announce Type: new Abstract: The growing demand for AI-driven workloads, particularly from Large Language Models (LLMs), has raised concerns about the significant energy and resource consumption in data centers. This work introduces a novel LLM-based… 11 arXiv — Machine Learning research 1mo ago Many Optimizers But Only One Training Path: Repeated Resampling for Adaptive Optimizer Selection arXiv:2608.18810v1 Announce Type: new Abstract: An optimizer is usually chosen before training a deep neural network and then kept fixed. Treating optimizer choice as a hyperparameter could boost performance, but it requires several complete training runs and discards all but… 33 Page 4 of 10 · 500 articles ← Newer Older →