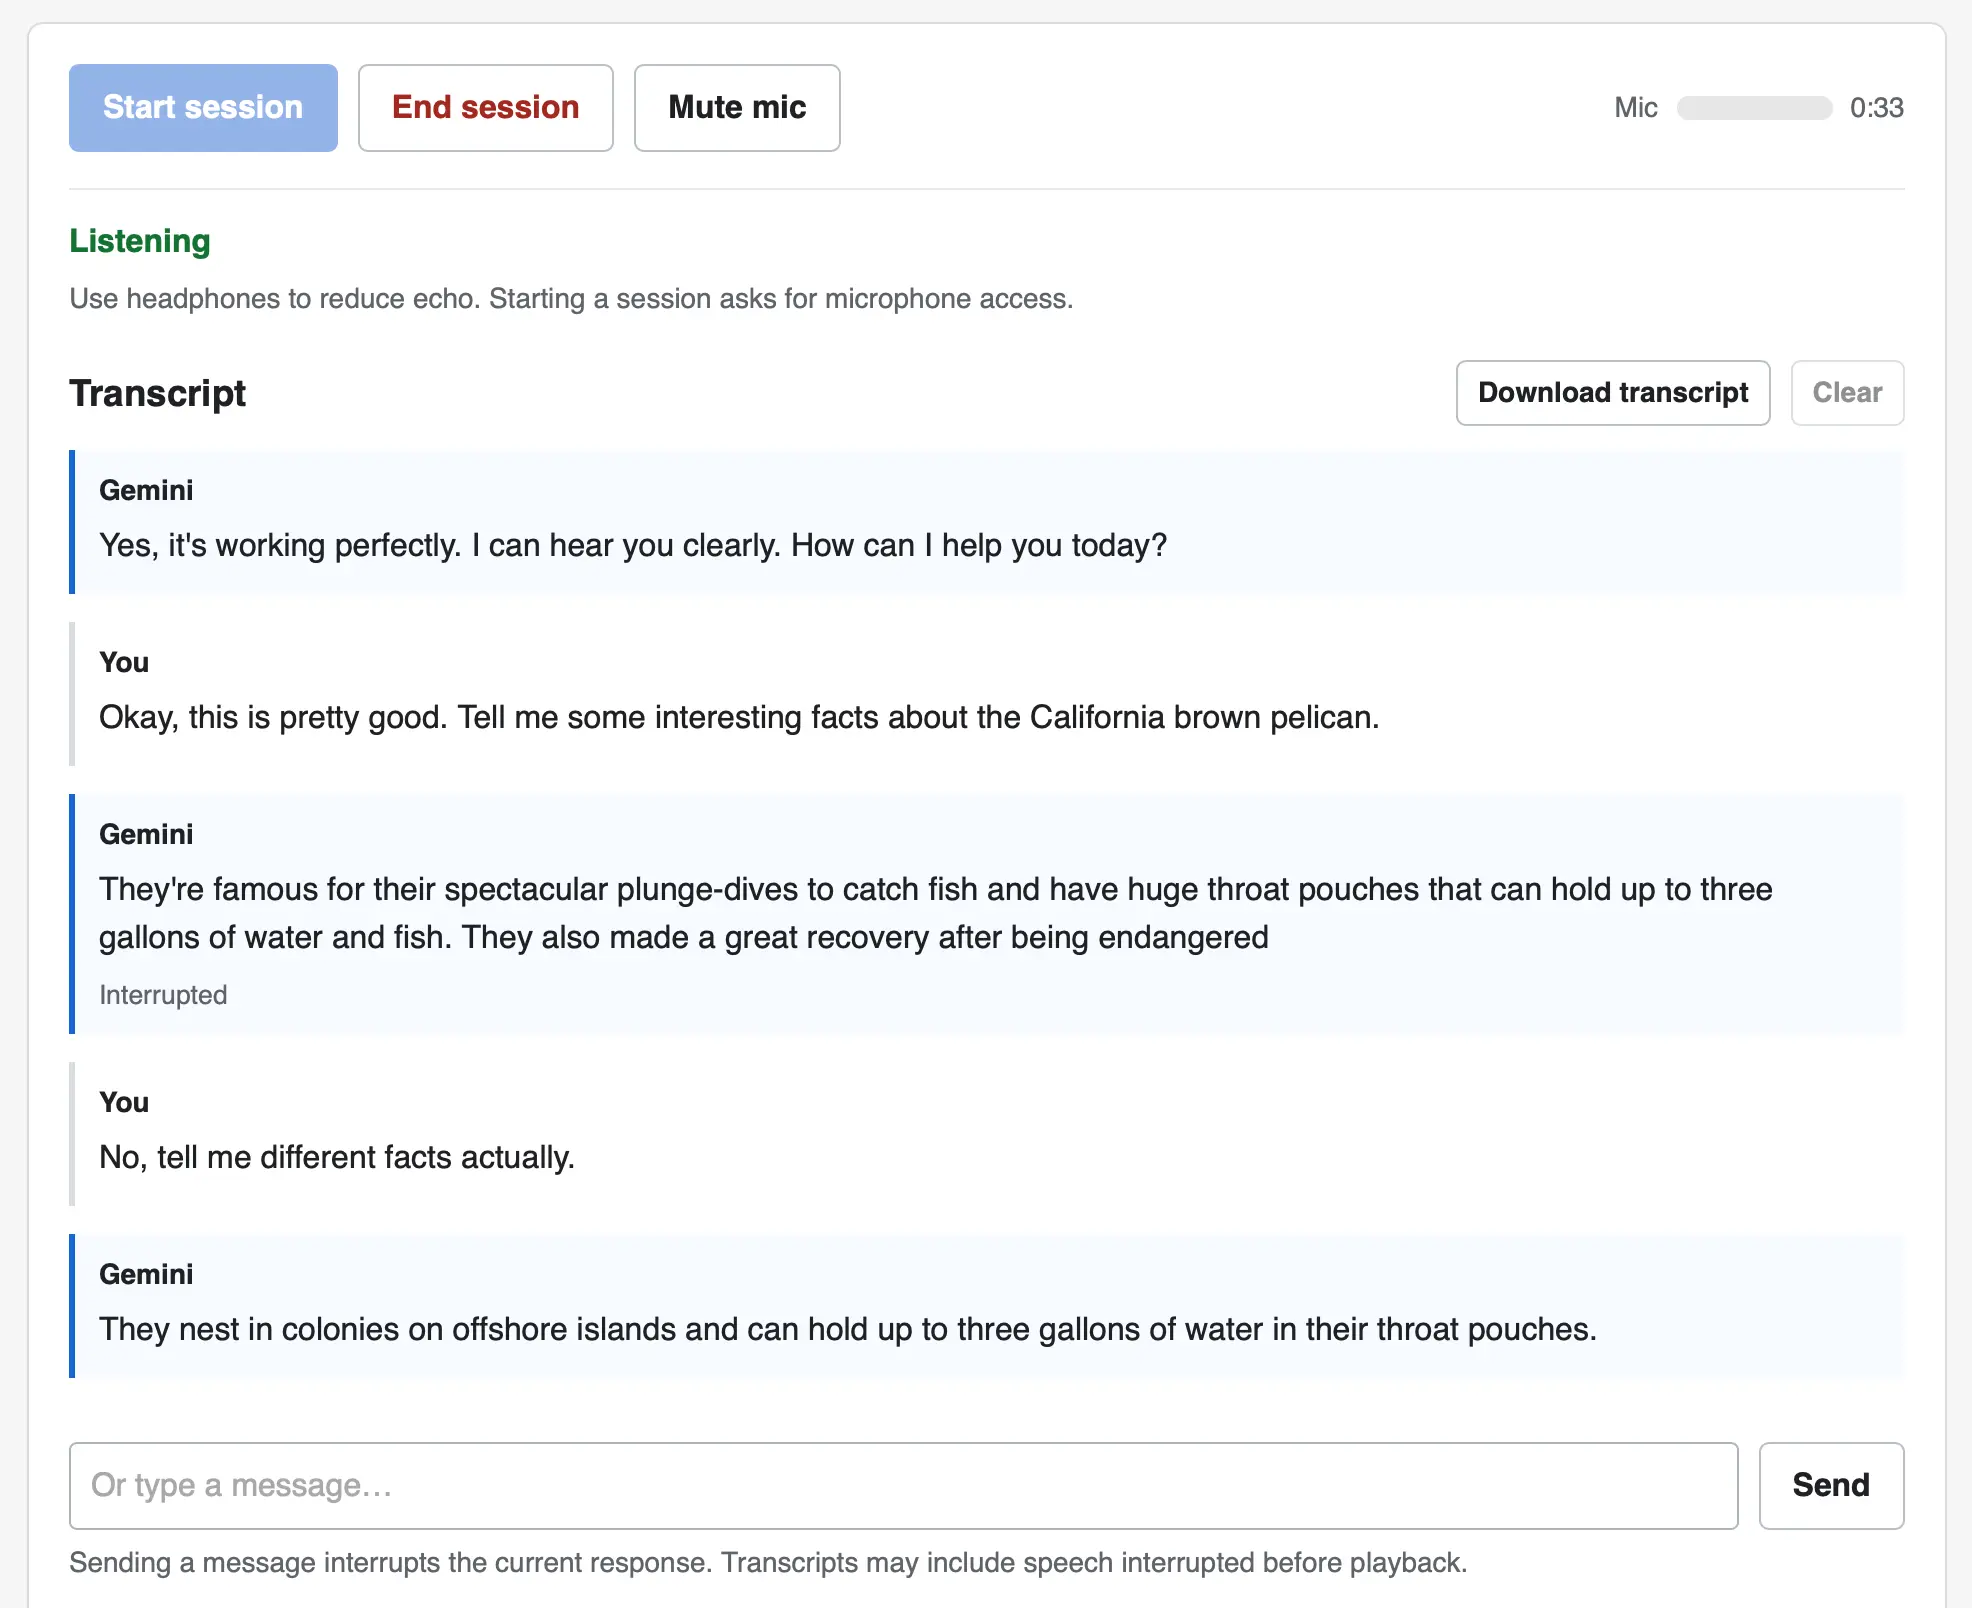
News / #music Tag Music 500 articles archived under #music · RSS Sign in to follow arXiv — NLP / Computation & Language research 12d ago Audio-Visual Turn-taking Prediction in Cocktail Party Scenarios arXiv:2609.17056v1 Announce Type: cross Abstract: Current predictive turn-taking models (PTTMs) achieve strong performance on benchmarks with controlled acoustic conditions and clean audio signals. Their generalisation to conversations with overlapping speech and background… 28 Simon Willison community 12d ago Gemini Live audio Tool: Gemini Live audio Google released Gemini 3.8 Live and 3.8 Live Extended Thinking today - two new speech-to-speech models that are a similar shape to OpenAI's GPT-Live models. I pointed GPT-6 Astra Extra High at the documentation and had it build me this web UI for trying… 35 r/LocalLLaMA community 13d ago jinfer: An open-source AI inference engine for the JVM. Finally, AI in jar. For years, the JVM has watched the AI revolution from the bench. Every model, AI framework, every breakthrough, built with/for Python. jinfer is an inference engine built for the JVM from first principles: chat, vision, audio transcription, embeddings, reranking, and TTS. No… 7 Hugging Face Daily Papers research 13d ago Realtime-Venus: A full-duplex interaction system with asynchronous delegation Abstract Realtime-Venus is a proactive full-duplex system with separate audio-visual and audio models that integrate continuous perception, conversational control, and native speech generation via a shared causal timeline and dual-loop runtime. Generated by… 23 arXiv — Machine Learning research 13d ago Machine Unlearning for Speech Question Answering in Large Audio-Language Models arXiv:2609.13195v1 Announce Type: new Abstract: Large Audio-Language Models (LALMs) have recently shown strong capabilities in speech understanding and question answering (QA), but they also inherit privacy risks from large-scale training data, including the unintended… 26 arXiv — Machine Learning research 13d ago Lie to me: Detecting Managerial Evasiveness in Earnings Calls via Conversational Audio Encoders arXiv:2609.13893v1 Announce Type: new Abstract: Earnings conference calls are a primary channel through which managers disclose information under analyst scrutiny. Prior work has linked vocal and lexical cues to future adverse outcomes, but often pools features over an entire… 17 arXiv — Machine Learning research 13d ago CyFM: Cylindrical Optimal Transport for Few-Step Complex-Valued Flow Matching arXiv:2609.14171v1 Announce Type: new Abstract: Complex-valued signals, such as Magnetic Resonance Imaging (MRI) and audio spectrograms, are almost always modelled as flat two-channel Euclidean data. For nonzero values the amplitude-phase chart $z \mapsto (|z|, z/|z|)$… 38 arXiv — Machine Learning research 13d ago Inherited Heads: Audio language models track speakers with their text backbone's attention, and an attention-mass ranking retrieves a different set arXiv:2609.14174v1 Announce Type: new Abstract: Asked to describe what one of six speakers in a recording talks about, audio language models describe the right one on 6 to 16% of trials, below the 16.7% a guess would give. Adding a fixed bias to the attention logits of a hundred… 36 Vercel — AI dev-tools 13d ago Gemini 3.8 Live models now available on AI Gateway Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking from Google are now available on AI Gateway. Both models support real-time spoken interactions for voice assistants, conversational experiences, and applications that respond through audio. google/gemini-3.8-live supports… 21 Hugging Face Daily Papers research 14d ago StepAudio 3 Gen Technical Report Abstract StepAudio 3 Gen is a discrete autoregressive audio generation model using residual vector quantization tokens to unify text-to-speech, voice design, sound effects, and music within a single framework. Generated by thinkingmachines/Inkling-Small We introduce StepAudio 3… 20 arXiv — Machine Learning research 14d ago TokenMapper: A Step Toward Interoperable Speech Token Translation arXiv:2609.12563v1 Announce Type: new Abstract: Neural audio codecs discretize speech into token sequences, but the resulting token spaces differ in vocabulary and codebook structure, preventing direct communication across models. This limitation affects applications such as… 5 r/LocalLLaMA community 15d ago Should I sell my RTX 5090 for a Mac Studio M5 Ultra 96GB? I can get $5k for the 5090 and the Mac is $5499 before tax. The 5090 has a memory bandwidth of 1.8 TB/s while the M5 Ultra is 1.2 TB/s. Is this a sensible upgrade? Primary use is coding.   submitted by   /u/unchikuso [link]   [comments] 34 r/LocalLLaMA community 17d ago Mac studio is an Anal powerhouse - time 0:04 in official video https://youtu.be/3uAIqqg8ZHo?is=WpAJgMA0Ut8vYLFy   submitted by   /u/rookan [link]   [comments] 30 Hugging Face Daily Papers research 17d ago X-AuT: Progressive Audio-Encoder Compression for Speech LLMs with Cross-Scale Distillation Abstract X-AuT progressively prunes audio-encoder layers in speech large language models and restores accuracy via behavioral probes, representation alignment, cross-scale distillation, and LoRA adaptation. Generated by thinkingmachines/Inkling-Small Reducing audio-encoder depth… 28 arXiv — Machine Learning research 17d ago TART: A Modular Tool for Technique-Aware Audio-to-Tablature Guitar Transcription arXiv:2609.11904v1 Announce Type: new Abstract: Automatic Music Transcription (AMT) for guitar remains limited by three challenges: existing systems often fail to capture expressive techniques such as slides, bends, and percussive hits; they often assign notes to incorrect… 20 arXiv — NLP / Computation & Language research 17d ago Beyond Word Error Rate: A Switch Aware Evaluation of ASR and Audio Language Models on English Yoruba Code-Switched Speech arXiv:2609.11786v1 Announce Type: new Abstract: Automatic speech recognition (ASR) systems and audio language models (audio LMs) now report low error rates on monolingual benchmarks, but their behavior on code switched speech in low resource, diacritic rich languages remains… 33 TechCrunch — AI news-outlet 17d ago India’s Pocket FM doubles revenue run rate to $500M as AI powers 93% of audio content Pocket FM uses AI to produce 99% of its new content, helping make content production about 80 times cheaper. 22 Stratechery (Ben Thompson) community 18d ago The iPhone Duo, The Intelligent Personal Hub, Apple Watch Audio Intelligence Apple once again demonstrated the power of integrating hardware and software, but it's biggest AI blindspot might be its belief in the primacy of apps. 38 Hugging Face Daily Papers research 18d ago Why Is Video Still So Expensive? A Survey of Inference-Efficiency Mechanisms in Video and Audiovisual LLMs Abstract This survey examines inference-efficiency techniques for video large language models, analyzing cost reductions across frame sampling, encoding, token compression, and language model stages while identifying evaluation gaps. Generated by thinkingmachines/Inkling-Small… 25 arXiv — NLP / Computation & Language research 18d ago SEA-SpeechBench: A Large-Scale Multitask Benchmark for Speech Understanding Across Southeast Asia arXiv:2609.09672v1 Announce Type: new Abstract: The rapid advancement of audio and multimodal large language models has unlocked transformative speech understanding capabilities, yet evaluation frameworks remain predominantly English-centric, leaving Southeast Asian (SEA)… 22 arXiv — NLP / Computation & Language research 18d ago VLX-VR: An Agentic-Aware Video Reasoning Model arXiv:2609.09985v1 Announce Type: new Abstract: Real-world video understanding requires integrating visual, audio, textual, and temporal evidence distributed across a video. Yet many pipelines use a fixed video context and single-pass inference, limiting adaptive evidence… 26 arXiv — NLP / Computation & Language research 18d ago Why Is Video Still So Expensive? A Survey of Inference-Efficiency Mechanisms in Video and Audiovisual LLMs arXiv:2609.10355v1 Announce Type: cross Abstract: Video understanding has rapidly evolved toward video large language models (VideoLLMs): systems that couple video representations with pretrained large language models and condition generation on a textual prompt. Their strong… 25 The Information — AI news-outlet 18d ago OpenAI Cuts Off Adobe, Others From Advertising Some Competing AI Products in ChatGPT OpenAI has told some business partners that it will no longer accept advertising in ChatGPT for image- and audio-generating products—which compete with its own features. The change, which hasn’t been previously reported or reflected in its published ads policy , blindsided… 33 The Information — AI news-outlet 18d ago OpenAI Restricts Adobe and Other Competitors From Advertising in ChatGPT OpenAI has told some business partners that it will no longer accept advertising in ChatGPT for image- and audio-generating products—which compete with its own features. The change, which hasn’t been previously reported or reflected in its published ads policy , blindsided… 24 TechCrunch — AI news-outlet 18d ago Apple Watch’s new AI features are normalizing the idea that technology is always listening Apple says its new watches won’t save raw audio, but features that can transcribe recent speech and summarize ambient conversations raise new questions about consent, privacy, and how people behave when they know they could always be recorded. 30 r/LocalLLaMA community 18d ago I trained an audio model that can generate infinite one-shots for music production and turn text prompts into fully playable synths. I'm not only releasing the model but I've also released a video on exactly how I did it (and the inferencing pipeline to let others make text… (hopefully this is okay to here - it seems like audio models and image / video modeals is allowed but yeah this is a bit different) So I've been doing independent audio research for a while now. The ultimate dream of this work was actually getting an AI to respond not only to… 10 r/LocalLLaMA community 18d ago Best Open source TTS right now for narration? I run these models on Kaggle notebook, so not all TTS models, such as the ones that use conda env, are compatible (Or I just haven't found a way for them to work on Kaggle). I currently use a fork from Chatterbox called Chatterbox Audiobook. It is like a workstation really… 22 r/LocalLLaMA community 18d ago Why the hell is LM Studio making LM Studio so difficult to download? Who is the marketing genius at LM Studio that decided that going ALL IN on pushing their new Bionic Agent product meant they are going to make it a giant pain in the ass to find and download actual LM Studio. This is the dumbest marketing decision I’ve ever seen. I used to love… 35 TechCrunch — AI news-outlet 18d ago Suno replaces its AI models with a new one trained on licensed music as copyright suits pile up As it grapples with a bevy of lawsuits, Suno said its new model, Suno v6, is not trained using music it used to train previous versions of the AI model. 34 Hugging Face Daily Papers research 19d ago AuK Technical Report: An Open-Source Foundational Model for Speech Generation and Editing Abstract AuK is an open-source foundational model that unifies speech generation and editing via natural-language instructions and audio context, using a multimodal language model, joint VAE, hybrid rectified-flow Transformer, and efficient distillation for fast inference.… 37 r/LocalLLaMA community 19d ago A hilarious comment about llama.cpp: “It’s a FB business using the pipeline to make profits” from a 10K star open source project maintainer. Context: I tried to explain that audio.cpp is built around the same philosophy as llama.cpp, but for audio models. "If you know llama.cpp, audio.cpp is ..." Update: Mystery solved --- he’s confusing the Llama models with llama.cpp.… 28 r/LocalLLaMA community 21d ago Easy local Copilot with VS Code and Lemonade Not so long ago I wrote a guide on how to get GitHub Copilot running with a local model in Visual Studio Code. Since then Copilot subscriptions have got much more expensive, local models have got much more powerful and getting local Copilot up and running has got much easier. So… 6 Hugging Face Daily Papers research 21d ago The Attention Triangle in Audio-Video Models Abstract Audio-video diffusion models exhibit bidirectional semantic leakage through cross-modal attention pathways, which can be diagnosed via attention-derived signals and mitigated through inference-time alignment interventions. Generated by thinkingmachines/Inkling-Small… 23 Hacker News — AI on Front Page community 21d ago LG smart TVs caught logging audio with screen off and snooping on local devices Article URL: https://www.notebookcheck.net/LG-smart-TVs-caught-logging-audio-with-screen-off-and-snooping-on-local-devices.1391214.0.html Comments URL: https://news.ycombinator.com/item?id=49594878 Points: 290 # Comments: 165 11 arXiv — NLP / Computation & Language research 21d ago TRILOGUE: A Trilingual Spoken Dialogue Fact-Checking Benchmark with Evidence and Paired Audio arXiv:2609.04452v1 Announce Type: new Abstract: Modern misinformation is often heard before it is read, yet fact-checking systems are still evaluated mainly on clean written claims. Spoken dialogue remains different even when systems operate on transcripts: claims may be… 11 arXiv — NLP / Computation & Language research 21d ago Tracing Audio Grounding and Answer Selection in Audio LLMs arXiv:2609.04637v1 Announce Type: new Abstract: Audio Large Language Models (Audio LLMs) have advanced in audio understanding, yet they can still predict the answer by reasoning from textual cues or linguistic priors rather than the provided audio. A common remedy is to train… 33 arXiv — NLP / Computation & Language research 21d ago Knowing When Not to Answer: Pseudo-Ensembles for Abstention in Music Audio-Language Models arXiv:2609.04362v1 Announce Type: cross Abstract: Music audio-language models are evaluated almost entirely by accuracy on multiple-choice questions. This protocol forces the model to commit to an option, so a lucky guess looks the same as real musical understanding. What is… 28 r/LocalLLaMA community 21d ago Trying to create my own server and consuming it for code with my phone remotely (Mac OS) Hi there! I need some help with this. I have a 32gb Macbook Pro with the latest available update of Tahoe. I'm using LMStudio with MLX to serve a local model and I want to expose it so that I can consume it with my phone to code and review stuff when I'm commuting to places.… 28 r/MachineLearning community 21d ago PINNStudio: A free, open-source no-code GUI for setting up, training, and visualizing PINNs [P] When I first started working in scientific machine learning, I understood the physics much better than the coding. Every time I wanted to try a new physics-informed neural network problem, I had to start almost from scratch: changing the PDE, updating boundary conditions,… 6 r/LocalLLaMA community 22d ago Unsloth Studio Aviation Assistant I am using Unsloth Studio to parse aviation transpoder data (ADS-B) to summarize interesting traffic in my area. It gives a summary of largest aircraft, fastest aircraft and so on. It also provides local weather based on my nearest airfield. I am doing this with a prompt, but is… 4 arXiv — NLP / Computation & Language research 24d ago Listen to the Latents: Self-Correcting Speech Recognition in Large Audio Language Models Through Hidden-State Interactions arXiv:2609.02940v1 Announce Type: new Abstract: Recent automatic speech recognition (ASR) systems increasingly integrate large language models (LLMs) to leverage their semantic knowledge, either externally through logit fusion or internally through warm initialization. However,… 11 arXiv — NLP / Computation & Language research 24d ago Alignment-Free Text-Audiobox for Voice Dubbing and Full-Duplex Dialogue Synthesis arXiv:2609.03992v1 Announce Type: new Abstract: We present Alignment-Free Text-Audiobox (Text-AB), a unified framework for high-quality voice dubbing and full-duplex dialogue synthesis. Building on a Diffusion Transformer trained with a flow-matching objective, Text-AB departs… 7 Hugging Face Daily Papers research 24d ago The Missing Temporal Link: Temporal Context Routing for Script-Driven Audio-Video Generation Abstract Temporal Context Routing improves script-aligned timing of shots and dialogue in joint audio-video generation by mapping structured script timing onto shared video-audio temporal axes. Generated by thinkingmachines/Inkling-Small Joint audio-video generation models have… 20 arXiv — NLP / Computation & Language research 25d ago AVERT: Audio-Verified Adjudication for Spoken Dialogue State Tracking arXiv:2609.01828v1 Announce Type: new Abstract: Spoken dialogue state tracking recovers slot-value pairs from speech, where ASR errors concentrate in entity values and persist across turns, making it both a generation and an editing problem. A strong per-turn text editor… 29 arXiv — NLP / Computation & Language research 25d ago SonicCaps: Large-Scale Diverse and Fine-Grained Captioning for Improved Audio-Retrieval arXiv:2609.02343v1 Announce Type: cross Abstract: Recent advances in audio-language modeling have been driven by large-scale audio captioning datasets. However, existing datasets remain limited by low semantic diversity, generic descriptions lacking acoustic details, and… 7 llama.cpp releases dev-tools 25d ago b10773 server : accept data: URLs for input_video and input_audio ( #27735 ) server : accept data: URLs for input_video and input_audio input_video and input_audio passed accept_base64_uri=false to handle_media(), so data: URLs got treated as raw base64 strings and failed later with a… 24 Ollama releases dev-tools 25d ago v0.33.3: gemma4: image and audio input support Safetensors gemma4 imports served by the MLX engine now answer image and audio chats. Images run through both vision architectures: the transformer tower (26B, 31B, e-series) and the 12B's encoder-free unified embedder. Audio arrives through the same intake the ollama API… 22 r/MachineLearning community 25d ago Where can I find legally usable datasets for advanced audio chord recognition? [D] I’m researching how to build or fine-tune an audio-to-chord-recognition engine comparable in ambition to Song Master Pro / Auralis Sound Prism. The goal is not basic major/minor chord detection. I need reliable recognition of dense harmonic material: jazz, soul, funk, neo-soul,… 26 r/MachineLearning community 26d ago MIR with AudioMuse-AI-SAE [P] Hi all, I recently read this paper: Julien Guinot, Alain Riou, Elio Quinton, Gyorgy Fazekas. Steering dense music retrieval with open-vocabulary concept discovery. https://arxiv.org/abs/2608.08757 There is multiple model where you can get embedding from Song and Text so that you… 35 r/LocalLLaMA community 26d ago Android Studios native Gemma 4 runs on llama.cpp https://preview.redd.it/6e9xb57a42nh1.png?width=787&format=png&auto=webp&s=ffae7996bbf8ab00498cc62c733e7597dc550f24 I'm not sure how many people care about Android Studio, but I think it's cool that Google uses llama.cpp. My guess is that it is Vulkan and the QAT versions of… 23 Page 2 of 10 · 500 articles ← Newer Older →