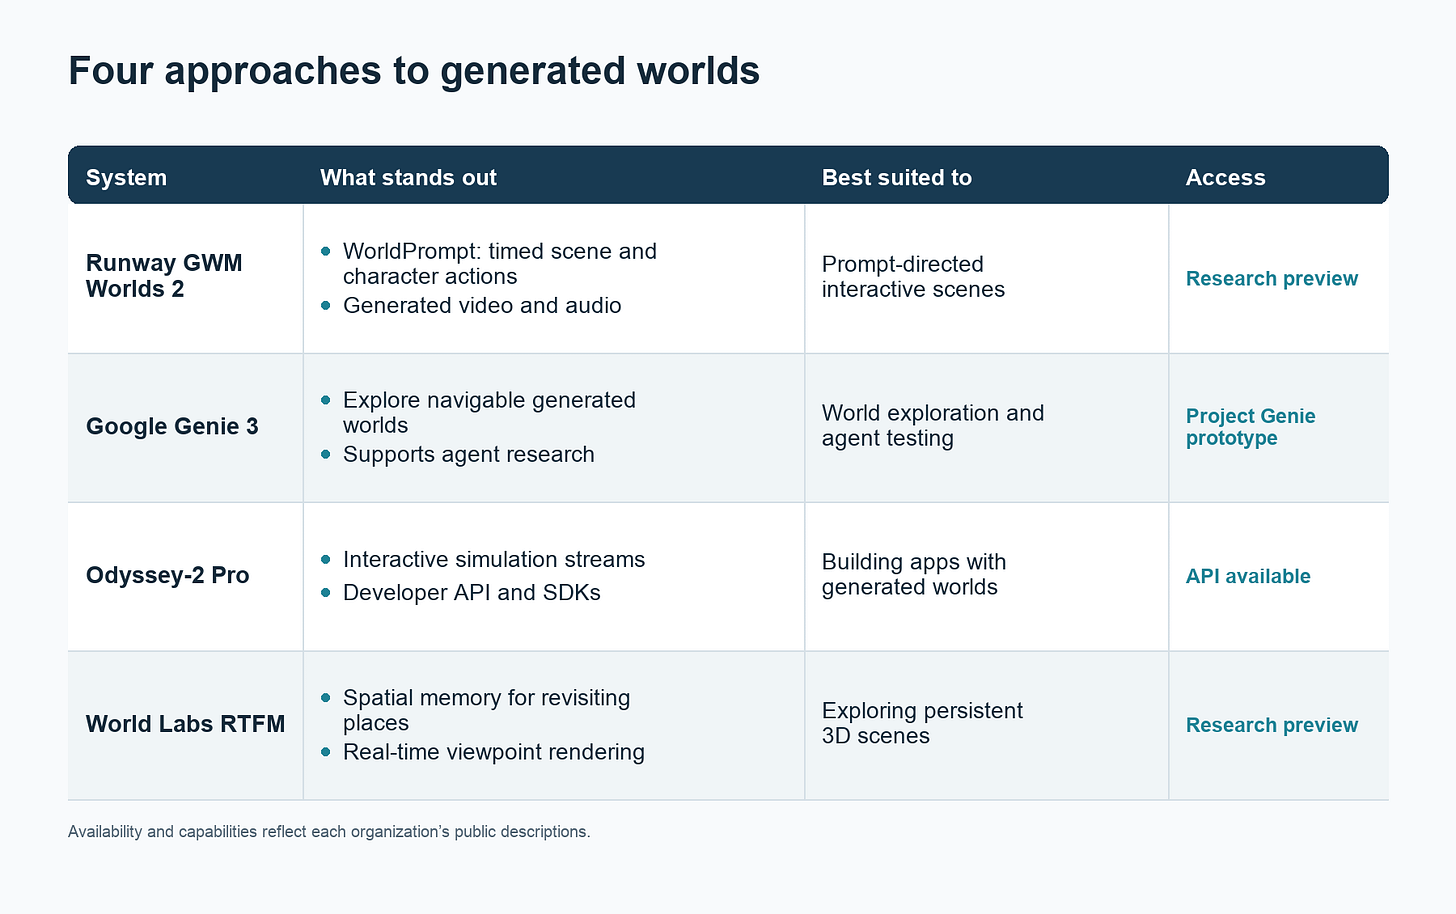
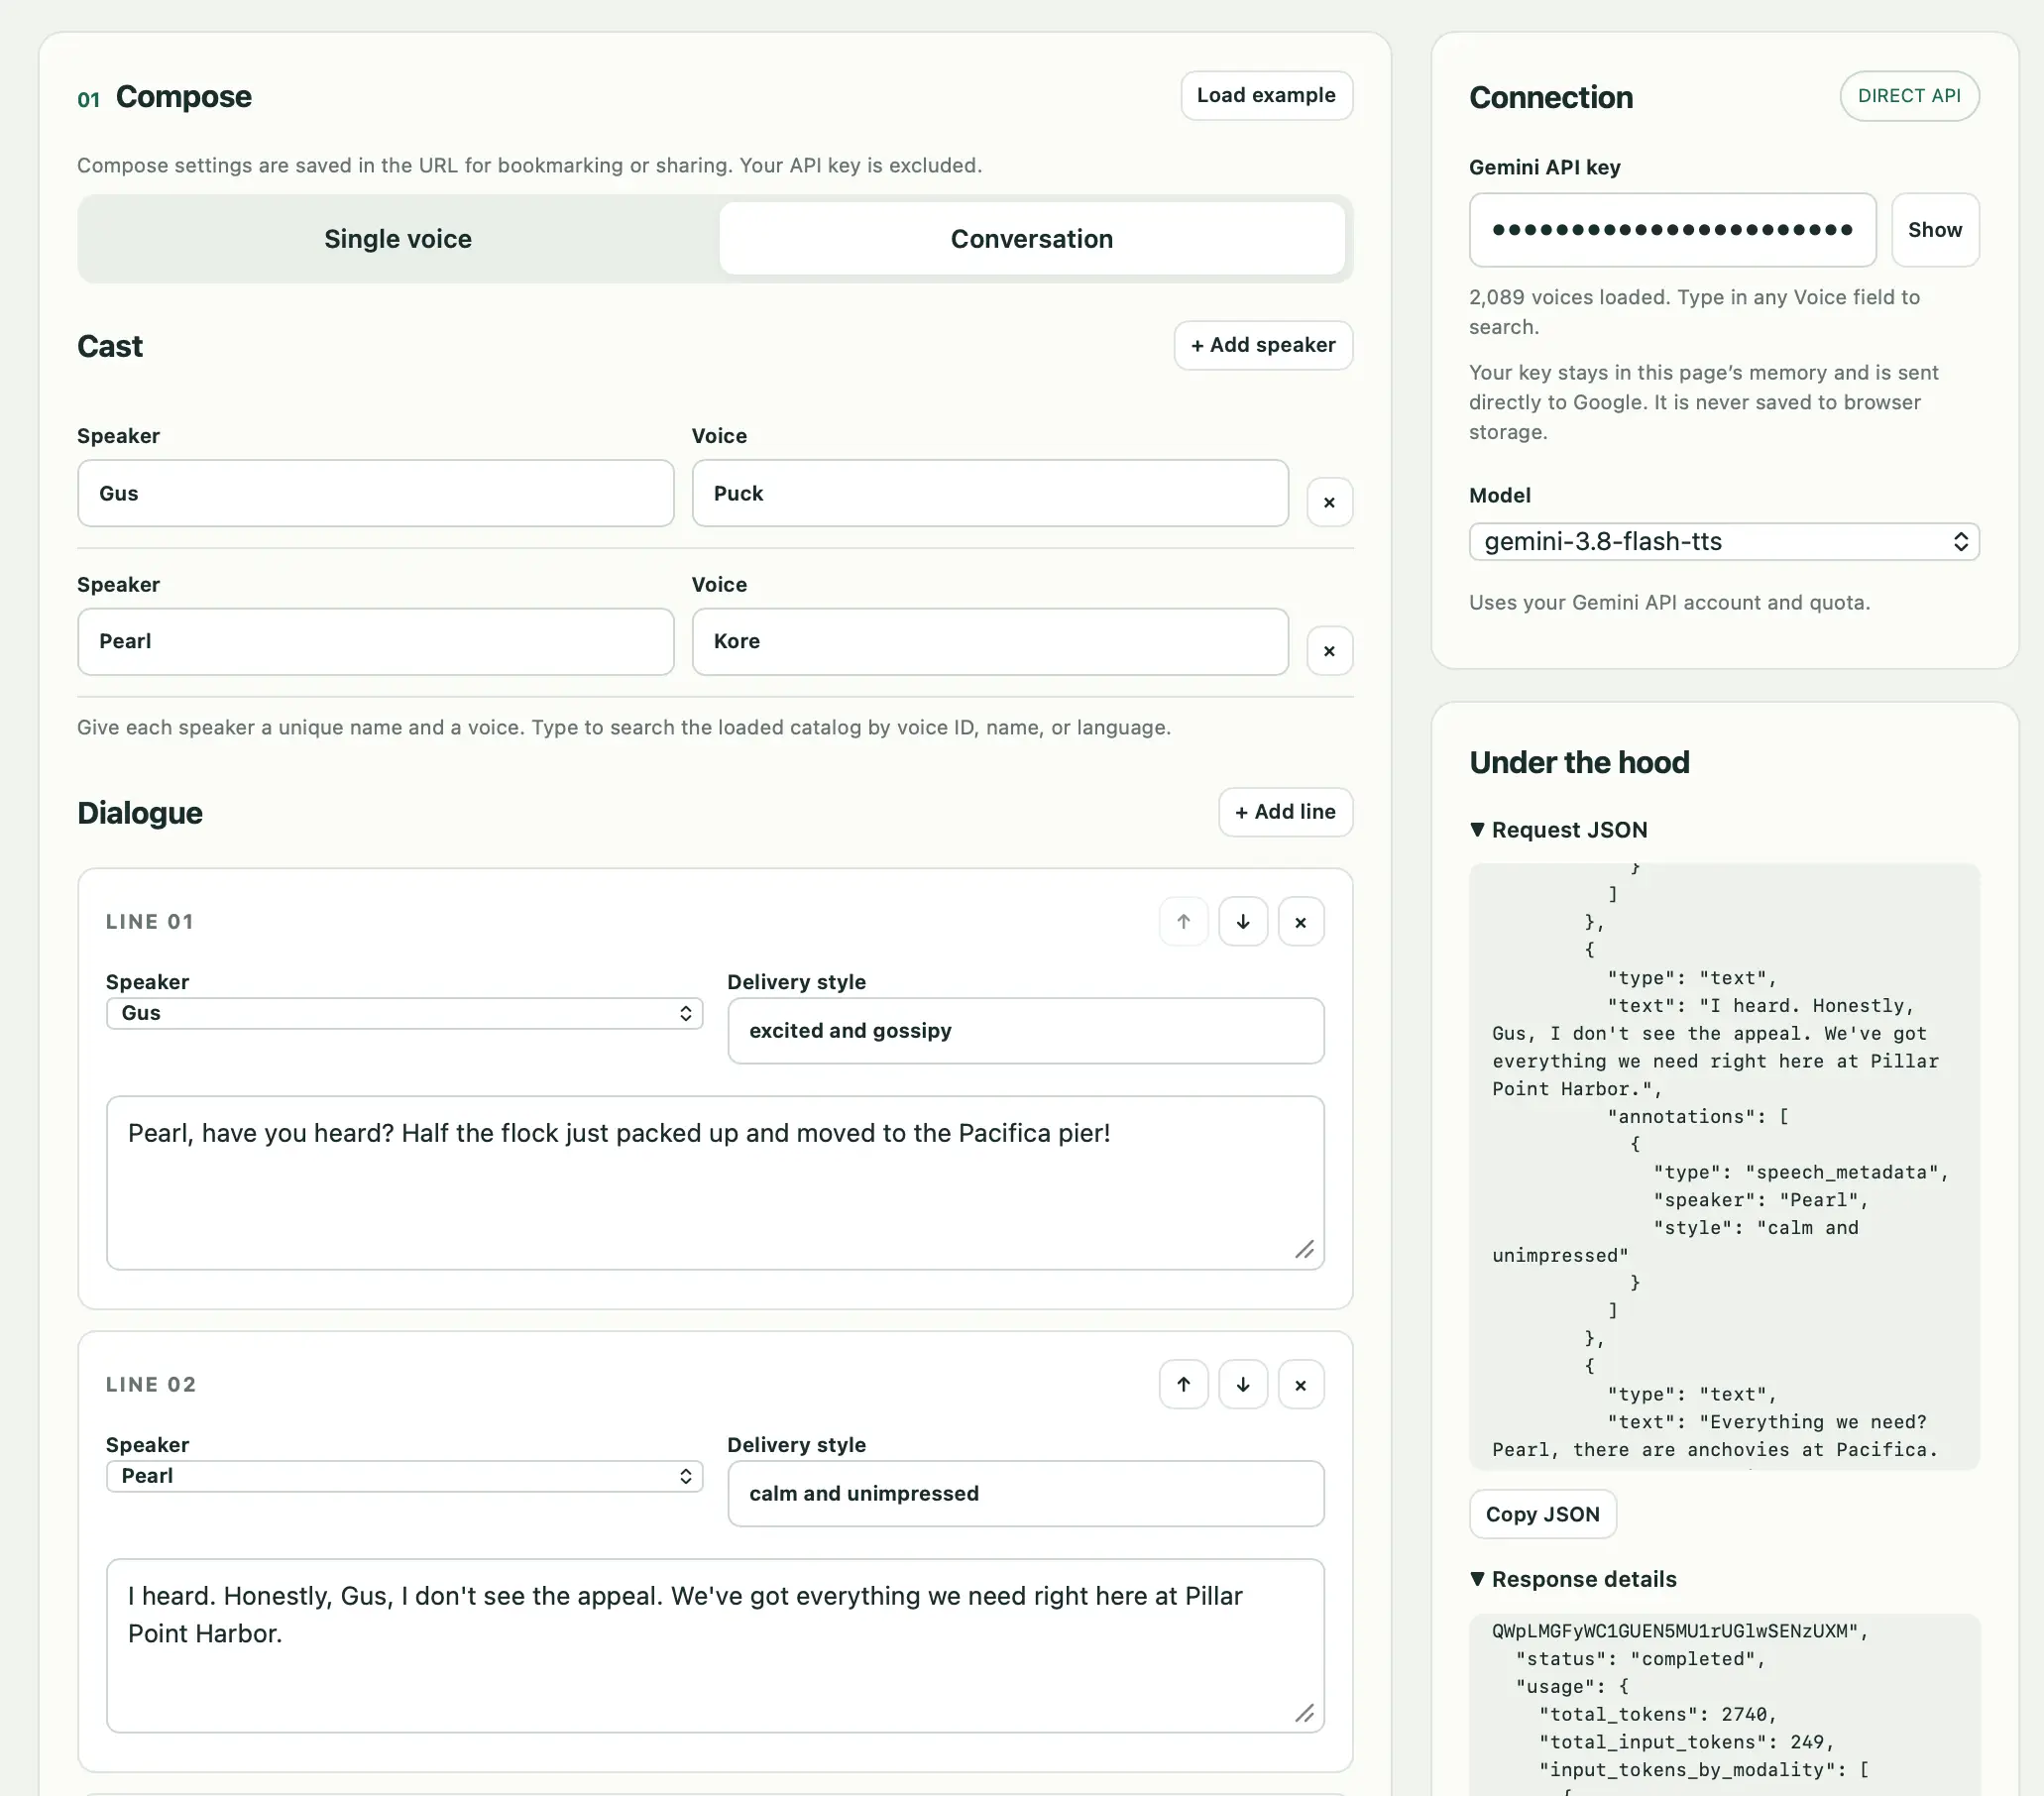
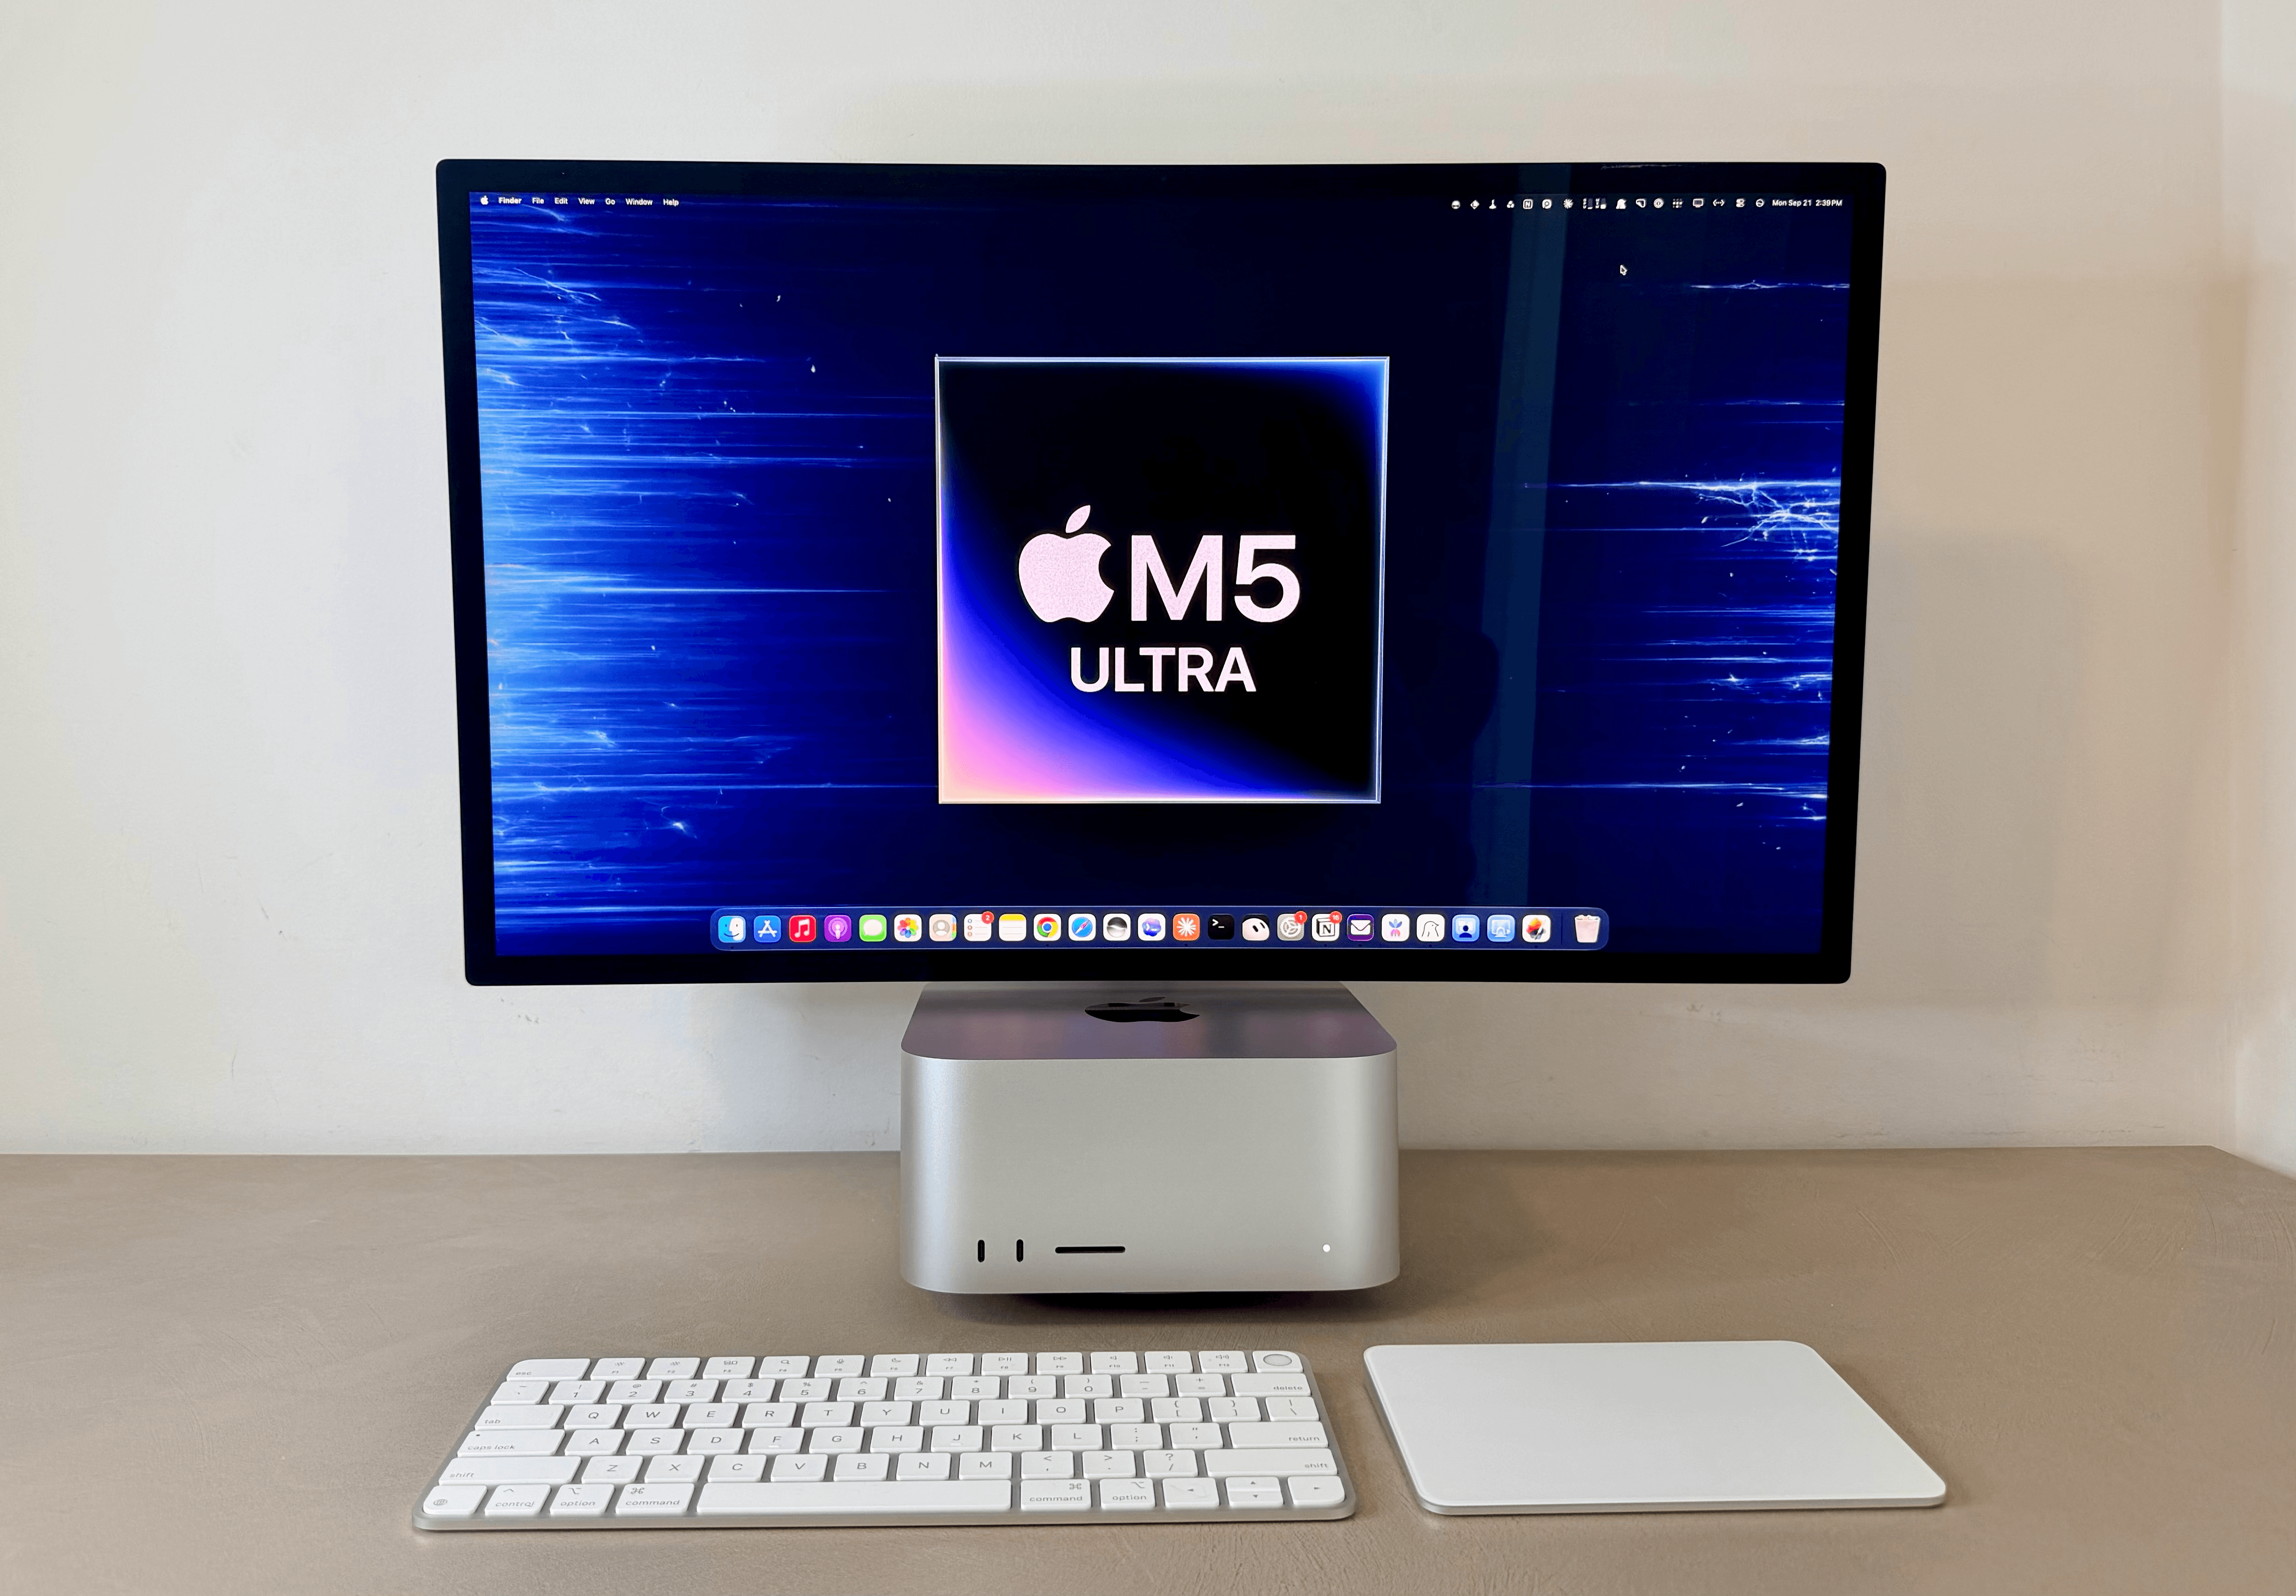
News / #music Tag Music 500 articles archived under #music · RSS Sign in to follow arXiv — NLP / Computation & Language research 7h ago AcoustiClaim: A Numeric Claim Benchmark with Instrument Ground Truth arXiv:2609.30483v1 Announce Type: cross Abstract: Audio language models state numbers for acoustic quantities, and neither human opinion nor a judge model says whether such a number is true of the signal. AcoustiClaim extracts each numeric claim from free text, scores it against… 4 arXiv — NLP / Computation & Language research 7h ago Don't CLAP: Are Music-Text Models Bag-of-Words? arXiv:2609.30540v1 Announce Type: cross Abstract: Text-to-music systems are assessed on audio quality and on how faithfully the music follows its prompt, and the CLAP score, the cosine similarity between a music-text model's audio and text embeddings, is the standard objective… 7 arXiv — NLP / Computation & Language research 7h ago Symbiotic Architecture for Post-Hoc Audio Extension of Frozen Language Models arXiv:2609.30784v1 Announce Type: cross Abstract: This paper proposes an architecture for equipping large language models (LLMs) with audio-understanding capabilities without fine-tuning their weights. The proposed symbiotic architecture employs an injector module that writes… 23 arXiv — NLP / Computation & Language research 7h ago Closing the Speech-Text Gap with Limited Audio for Effective Domain Adaptation in LLM-Based ASR arXiv:2604.06487v3 Announce Type: replace Abstract: Conventional end-to-end automatic speech recognition (ASR) systems rely on paired speech-text data for domain adaptation. Recent LLM-based ASR architectures connect a speech encoder to a large language model via a projection… 34 r/LocalLLaMA community 1d ago How accessible is local AI actually, and what happens if affordable access to frontier models doesn’t last? Sometimes it’s easy to forget that this sub and others like it are probably the extreme minority when it comes to this hobby. Most people, I would think, don’t use or can’t afford one good GPU, let alone multiple GPUs, Mac Studios, Sparks, Strix Halos, etc. Is the average tech… 14 llama.cpp releases dev-tools 2d ago b11190 mtmd: fix mel preprocessor in LFM2 audio ( #29403 ) which resulted in different greedy transcripts for 4.5% of English and 6.5% of Japanese test utterances. In Japanese, some differences changed entire words. This change: uses log(x + 2^-24) instead of clamping to the log floor… 27 r/LocalLLaMA community 2d ago I compared diarization models on 15 clinical conversations: Nemotron 3, Pyannote, Sortformer and VibeVoice I've been working on clinical speaker attribution at Omi and wanted to compare the current diarization models on the same audio. I used 15 mock doctor–patient consultations from PriMock57, about 2.4 hours. Full recordings, automatic speaker counts, without telling the models… 35 arXiv — NLP / Computation & Language research 3d ago agentic-ger: terminology recovery in long-form speech using global context arXiv:2609.29428v1 Announce Type: new Abstract: Recent advances in speech language models have improved automatic speech recognition (ASR) for long-form audio. However, accurately and consistently transcribing domain-specific terminology remains challenging. Motivated by the… 25 arXiv — NLP / Computation & Language research 3d ago YODAS v3: Over 1 Million Hours of High-Bandwidth, Stereophonic, Multilingual Speech arXiv:2609.29448v1 Announce Type: new Abstract: We present YODAS v3, a weakly-labeled speech corpus containing over 1.1 million hours of 48kHz multi-channel audio in 147 languages, released under a CC BY 3.0 license. YODAS v3 is not only the largest open speech dataset to date,… 30 arXiv — NLP / Computation & Language research 3d ago What, When, and How: Audio Description as Constrained Global Optimization arXiv:2609.30121v1 Announce Type: new Abstract: Audio Description (AD) makes movies accessible to blind and visually impaired audiences by narrating visual information in gaps between dialogue. Existing automatic AD systems largely treat generation as a local video-to-text… 24 arXiv — NLP / Computation & Language research 3d ago Do Audio Language Models Hear and Read Distinctive Features Alike? arXiv:2609.30167v1 Announce Type: new Abstract: Audio language models pass speech and text through a single decoder. We ask whether that decoder represents a distinctive feature in the same direction when a phoneme is heard and when it is read. For minimal pairs of phonemes… 10 arXiv — NLP / Computation & Language research 3d ago Spooftral: Can Voxtral Audio-Language Model Detect Speech Spoofing? arXiv:2609.28713v1 Announce Type: cross Abstract: Self-supervised learning (SSL) countermeasures (CMs) have shown strong performance in recent years. However, they often show degraded performance while facing unseen spoofing attacks and mismatched conditions. This study examines… 10 arXiv — NLP / Computation & Language research 3d ago Reward-Tilted On-Policy Distillation for Acoustic Grounding in Audio-Language Models arXiv:2609.28778v1 Announce Type: cross Abstract: Audio-language models (ALMs) can exploit textual shortcuts to answer questions while overlooking acoustic evidence, weakening audio understanding. On-policy distillation (OPD) trains compact ALMs by supervising student-generated… 28 r/LocalLLaMA community 3d ago M5 Ultra 80Core GLM-5.3-Flash on DwarfStar Speeds I've been playing around with various models on the M5 Ultra 256GB 80-core Mac Studio. These are the results over many rounds of agentic inferencing. I'm happy with the performance. Glad to have the large amount of RAM. But it does feel like the GPU is underpowered for this… 6 Latent.Space news-outlet 3d ago Runway’s WorldPrompt and the Engineering of Real-Time Worlds GWM Worlds 2 uses persistent context and timed actions to steer a world model generating video and audio in real time. 25 r/LocalLLaMA community 3d ago Mac Studio M5 Ultra 96GB vs M5 Max 128GB for local LLMs? I'm about to buy a Mac Studio mainly for running LLMs locally and I'm stuck between two configs: M5 Ultra (30/64) with 96GB : 1.2 TB/s bandwidth, roughly 1.7x faster generation and much faster prefill M5 Max (40-core GPU) with 128GB : 614 GB/s, but 32GB more memory and a bit… 15 r/LocalLLaMA community 4d ago MacBook Pro M5 Max LSE LLM running an AMD Radeon AI PRO R9700 over Thunderbolt 5 in a Razer enclosure Hello Everyone! Good news for anyone who can compile code on apple, you can now experience using a AMD Radeon AI Pro R9700 on a MacBook Pro or Mac mini, Mac Studio or any OSX variant as long as it has Thunderbolt, next up is a iPad with a M series processor ! The driver seems to… 11 arXiv — Machine Learning research 4d ago Live Assistant: Learning Whether, When, and Whom to Assist in Real-World Live Social Streams arXiv:2609.27303v1 Announce Type: new Abstract: Livestreams are long-lasting interactive environments where audiovisual content, viewer activity, host behavior, and platform signals evolve together, creating assistance needs that emerge from the stream itself. We introduce… 29 arXiv — NLP / Computation & Language research 4d ago Text Scores Can Miss Waveform Use: A Qwen2-Audio Quantization Case Study arXiv:2609.26823v1 Announce Type: cross Abstract: Post-training quantization of speech language models is often summarized with text-output scores and nominal bit widths. Those numbers alone do not establish behavior that depends on information missing from a transcript, or… 38 arXiv — NLP / Computation & Language research 4d ago When Entanglement Lower-Bounds Disparity: Auditing and Repairing Demographic Fairness in Audio Understanding Models arXiv:2609.27382v1 Announce Type: cross Abstract: Speech technology penalizes some voices: recognition errs nearly twice as often for Black speakers, and accuracy declines for second-language accents and older speakers. We introduce TRIAD, an audit grid crossing 120 texts, 24… 8 Simon Willison community 4d ago Gemini 3.8 TTS Playground Tool: Gemini 3.8 TTS Playground Google released two new Gemini text-to-speech models today - gemini-3.8-flash-tts and gemini-3.8-flash-lite-tts . They come with a library of over 2,000 voices, plus the ability to create a custom voice with "just a 30-second audio sample of your… 16 Google DeepMind official-blog 4d ago Gemini 3.8 text-to-speech says hello Gemini 3.8 text-to-speech says hello Sep 23, 2026 | x.com Facebook LinkedIn Mail Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS are our most expressive audio generation models yet. Generate custom character voices and direct scene dialogue across Google AI Studio, Gemini… 26 TechCrunch — AI news-outlet 4d ago YouTube releases new AI features for creators within its Studio app YouTube is adding new features to generate ideas and monitor the performance of thumbnails. 23 arXiv — NLP / Computation & Language research 5d ago Qwen-Audio-3.1-Realtime: Towards Reliable Agentic Voice Interaction arXiv:2609.25176v1 Announce Type: cross Abstract: Real-time voice assistants must reason over evolving requests, execute actions, and follow conversational rules. Qwen-Audio-3.1-Realtime brings these requirements together through Think, Act, and Speak and Coordinate. Think… 9 r/LocalLLaMA community 5d ago Unsloth Studio VS LM Studio... Which one do you prefer? So I've been experimenting with various platforms and even on day 1 Unsloth Studio was released, I knew that LM Studio had it's days numbered. LM studio will always be the OG but I wonder how much longer they have, especially with all these new platforms arising. It feels like… 28 r/LocalLLaMA community 5d ago Qwen image 2.1 (Fast FP8) generates premium quality images Don't know how they did it, but for under 10GB model, the results are astonishing. I am running it on Unsloth Studio. They just released the update, so if you are not seeing the option, I recommend updating your Unsloth Studio. Cheers!   submitted by   /u/108er [link]… 18 arXiv — Machine Learning research 6d ago Generalized Multimodal Foundation Model arXiv:2609.22107v1 Announce Type: new Abstract: Making prediction with multimodal data is widely used in diverse scenarios. Existing multimodal fusion models, once deployed, can only handle predefined modalities (e.g., vision, text and audio) and single tasks, making it… 31 arXiv — Machine Learning research 6d ago Common Cause, Not Cross-Attention: Blocking Visual Shortcuts in Audio-Video Generation arXiv:2609.22361v1 Announce Type: new Abstract: Joint audio--video generators are trained on data in which what an event looks like and what it sounds like are strongly, often spuriously, correlated: a particular material, texture, or object appearance co-occurs with a… 14 arXiv — NLP / Computation & Language research 6d ago Read-Best Is Not Steer-Best: A Probing--Steering Layer Dissociation in Omni-Modal Large Language Models arXiv:2609.22135v1 Announce Type: new Abstract: Omni-modal large language models integrate text, audio, and image signals into a shared residual stream, where concepts such as emotion can be linearly decoded and causally modified by activation steering. A common but rarely… 29 arXiv — NLP / Computation & Language research 6d ago Vox-Infinity: Benchmarking the Limits of Long-Context Spoken Language Models arXiv:2609.22452v1 Announce Type: new Abstract: Long-context understanding remains a fundamental challenge for large language models, as excessively long inputs often lead models to forget salient information. This issue is even more pronounced in the speech domain, where audio,… 33 arXiv — NLP / Computation & Language research 6d ago COT-TTS: Audio Context-Aware Text-to-Speech with Chain-of-Thought Reasoning arXiv:2609.22697v1 Announce Type: new Abstract: Recently, text-to-speech systems have made significant progress in speech expressiveness and controllability. However, the speaking style of generated speech typically relies on clear user-specified instructions. In natural… 7 The Information — AI news-outlet 6d ago Exclusive: Xbox to Cut Hundreds of Jobs, Consolidate Game Studios Xbox is planning to lay off hundreds of employees this week in its second major staff reduction this year, according to someone briefed on the plans. The Microsoft-owned firm also plans to consolidate several of its game studios, this person said. Xbox CEO Asha Sharma in July… 34 r/LocalLLaMA community 6d ago M5 Ultra Mac Studio Review: The Dream Mac for Local AI Agents - MacStories   submitted by   /u/themixtergames [link]   [comments] 17 Hacker News — AI on Front Page community 6d ago M5 Ultra Mac Studio Review Article URL: https://www.macstories.net/stories/m5-ultra-mac-studio-review-the-dream-mac-for-local-ai-agents/ Comments URL: https://news.ycombinator.com/item?id=49787313 Points: 213 # Comments: 202 14 arXiv — Machine Learning research 7d ago TierKV: Long-Context On-Device LLMs via Predictive Multi-Tier KV Caching arXiv:2609.21172v1 Announce Type: new Abstract: Large language models (LLMs) are moving onto mobile devices for increasingly diverse workloads over text, images, video, and audio. These applications often require long contexts, making the Key-Value (KV) cache a dominant memory… 28 arXiv — NLP / Computation & Language research 7d ago Reading Less While Writing: A Closed-Form Bandwidth Dial for Streaming Multimodal Decoders arXiv:2609.20845v1 Announce Type: new Abstract: A decoder that turns video or audio into text conventionally consumes the entire input before emitting a word. Offline this is merely more than the task requires; live it is impossible, since a caption cannot wait for a match to… 21 arXiv — NLP / Computation & Language research 7d ago Enhancing Audio Reasoning via Semantic Summary Prediction arXiv:2609.20849v1 Announce Type: new Abstract: Large Audio Language Models (LALMs) perform well on complex question answering but often show a reasoning gap, where explicit Chain-of-Thought (CoT) reduces accuracy compared to direct answers. We hypothesize that long reasoning… 9 arXiv — NLP / Computation & Language research 7d ago Scaling Forced Alignment to End-User Devices arXiv:2609.21145v1 Announce Type: new Abstract: The Viterbi algorithm has been previously used to perform forced alignment of audio to text to mine training data from online resources. However, many existing implementations have quadratic time and space complexity, scaling… 5 arXiv — NLP / Computation & Language research 7d ago Omni Demand Understanding: A Benchmark for Contextual User-Intent Inference in Multimodal Interaction arXiv:2609.21392v1 Announce Type: new Abstract: Natural audio-visual interaction is emerging as an important interface for AI assistants, allowing users to communicate through speech and vision rather than carefully composed text prompts. However, existing benchmarks of… 28 arXiv — NLP / Computation & Language research 7d ago I'll Keep an Ear Out: Teaching AudioLLMs Proactive Audio Assistance arXiv:2609.21183v1 Announce Type: cross Abstract: Audio large language models (AudioLLMs) operate reactively, responding only when queried. We introduce proactive audio assistance, where an AudioLLM monitors an audio stream and autonomously decides when to alert the user from a… 27 Vercel — AI dev-tools 7d ago MiMo V2.6 models now available on AI Gateway MiMo V2.6 Pro , MiMo V2.6 Flash , and MiMo V2.6 Pro UltraSpeed from Xiaomi are now available on AI Gateway . MiMo V2.6 combines coding, reasoning, and tool use with native text, image, audio, and video understanding. Its 1M token context supports long repositories, tool traces,… 14 TechCrunch — AI news-outlet 7d ago ScrollEd wants to turn textbooks into TikTok ScrollEd turns textbooks into a scrollable, Instagram-like feed with video, audio, and quizzes. The Palo Alto startup, founded by student co-founders (and spouses) Utsav Gupta and Rebecca Neff, pitches at TechCrunch Disrupt. 38 r/LocalLLaMA community 8d ago What is the best tts to create audio books? One that support emotions? I tried google and on almost each mode.people complains it’s not good enough? is there any good tts right now that support English and can express emotions for audio and not read it in monotone voice?   submitted by   /u/Alarmed_Wind_4035 [link]   [comments] 21 r/LocalLLaMA community 9d ago Ternary Bonsai 2 27B (1.75bpw) vs. Gemma 26B-A4B MoE Introduction My audiobook pipeline that has to decide who speaks each line of dialogue in a novel, so the TTS can cast voices per character. It's been running on Gemma 4 26B-A4B (QAT Q4). Bonsai 2 27B looked like it should win: a 27B-class model in 5.9 GB means a stronger base… 13 r/LocalLLaMA community 9d ago inclusionAI/Realtime-Venus · Hugging Face do you want some omni? here is omni for you 1. 🧭 Overview This repository hosts two checkpoints of the Realtime-Venus system: Realtime-Venus-Omni ( Realtime-Venus-Omni/ ): the 9B audio-visual interaction model. It continuously watches and listens, decides whether and when to… 27 arXiv — NLP / Computation & Language research 10d ago Before the Warning Comes Too Late: Incremental Phone-Scam Detection from Speech arXiv:2609.20223v1 Announce Type: new Abstract: We study weakly supervised incremental telecom fraud detection from raw telephone audio, where training provides only conversation-level labels and predictions must be updated before a call ends. We introduce StreamFraudNet, which… 34 OpenAI Python SDK releases dev-tools 10d ago v3.15.0 3.15.0 (2026-09-18) Features api: add agent session model settings ( #3882 ) ( 4b15817 ) api: add audio-mini model choices ( #3886 ) ( a6eeb3f ) api: add compaction progress events ( #3866 ) ( 98e1d24 ) api: add managed Responses WebSocket sessions ( #3887 ) ( 3b865af ) api: add… 31 arXiv — NLP / Computation & Language research 11d ago G-Mamba: Sparse Graph-Guided Mamba for Audio-Visual Speech Enhancement arXiv:2609.18009v1 Announce Type: cross Abstract: Lightweight audio-visual speech enhancement (AVSE) models face a critical trade-off between computational efficiency and cross-modal alignment accuracy. While simple concatenation lacks relational expressiveness, dense… 23 arXiv — Machine Learning research 12d ago You Don't Need To Train: Agentic Heuristic Learning Studio for Executable Human Activity Recognition arXiv:2609.16065v1 Announce Type: new Abstract: Human activity recognition (HAR) is usually framed as gradient-based training of neural networks. Agentic Heuristic Learning (AHL) Studio explores a complementary view inspired by human cognitive learning: people learn activities… 29 arXiv — NLP / Computation & Language research 12d ago Language Orthogonalization for Zero-Shot Cross-Lingual Audio Deepfake Detection arXiv:2609.16458v1 Announce Type: cross Abstract: Audio deepfake detectors need to transfer to languages absent from training, as multilingual speech synthesis outpaces labeled anti-spoofing resources. While detectors increasingly rely on self-supervised speech models (S3Ms),… 10 Page 1 of 10 · 500 articles Older →