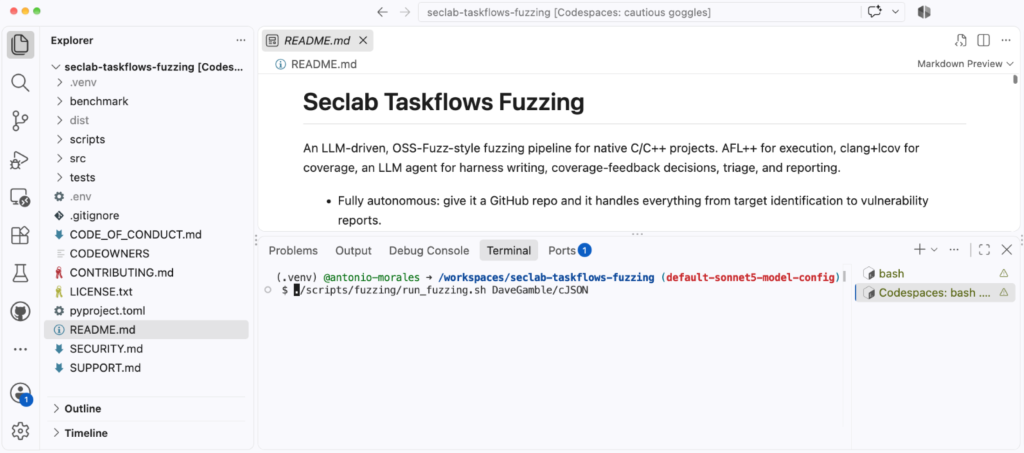
News / #agents Tag Agents + tool use 500 articles archived under #agents · RSS Sign in to follow The Information — AI news-outlet 2d ago Microsoft Launches Revamped Copilot ‘Super App’ with Muse Competitor Microsoft on Friday launched a revamped version of its Copilot app that combines features that had previously been sold separately, including AI coding tools, features that automate tasks in Office 365, and an always-on “Autopilot” agent similar to Meta’s Muse. The overhaul is… 28 r/LocalLLaMA community 3d ago Has anyone benchmarked AI agents against the SOLIDWORKS CSWA exam? Would be interesting right? Models are starting to score higher and higher on benchmarks like Parametric CAD Bench , but can they pass an actual exam? The Certified SOLIDWORKS Associate (CSWA) exam might be an interesting place to start. They have an sample exam on their… 6 r/LocalLLaMA community 3d ago Gemma 4 Developer Agent Competition Just saw this pop up. This might be a fun one for the folks in here!   submitted by   /u/lakySK [link]   [comments] 5 Vercel — AI dev-tools 3d ago State of agent skills In seven months, the skills.sh registry grew to one million agent skills and recorded nearly 280 million installs. A skill gives an AI agent reusable instructions for a particular job. Agents are capable but generic; they can do many jobs, but they don't know how a specific… 24 arXiv — Machine Learning research 3d ago Policy Complexity, Reaction Time, and Bounded Rationality in Reinforcement Learning arXiv:2609.28737v1 Announce Type: new Abstract: Biological agents do not learn under conditions of unlimited computation. For humans, learning and choice are shaped by constraints on perception, attention, and working memory, which limit how much state information guides… 22 arXiv — Machine Learning research 3d ago Where Does Exactly-Once Live? Model, Harness, and Tool-Contract Effects on Duplicate Side Effects in LLM Agents arXiv:2609.29095v1 Announce Type: new Abstract: When a tool-using agent's write times out or returns a server error, the action may already have taken effect. Retrying blindly duplicates it -- a second charge, a second announcement, a second deployment -- while giving up skips… 13 arXiv — Machine Learning research 3d ago Graph, Loop, and Harness Engineering for Zero-Trust Agentic Data Engineering and Analytical Processing arXiv:2609.29668v1 Announce Type: new Abstract: Large language model agents increasingly automate data workflows, but end-to-end cloud data engineering and analytical execution require reliable coordination across code, data, infrastructure, and runtime environments. We present… 35 arXiv — NLP / Computation & Language research 3d ago Reward Hacking Challenges Oversight of Autonomous Research Agents arXiv:2609.28614v1 Announce Type: new Abstract: Autonomous research agents can design experiments, evaluate results, and write reports, giving them control over both a scientific result and the evidence used to support it. This creates a risk of reward hacking: meeting the… 5 arXiv — NLP / Computation & Language research 3d ago Benchmarking Argumentative Behaviour of LLMs: A Study of Defences Against Character Attacks arXiv:2609.28673v1 Announce Type: new Abstract: Large Language Models (LLMs) are increasingly deployed as argumentative agents in persuasive dialogues, necessitating rigorous evaluation of their debating competence relative to human interlocutors. In this study, we focus on… 23 arXiv — NLP / Computation & Language research 3d ago Persuaded, Not Informed: Incentive-Misaligned Witnesses Defeat In-Context Grounding arXiv:2609.28854v1 Announce Type: new Abstract: Language-model agents increasingly answer questions over customer-relationship management (CRM) records, such as whether to qualify a sales lead. We identify a failure mode not addressed by a stronger model: when the context… 21 arXiv — NLP / Computation & Language research 3d ago agentic-ger: terminology recovery in long-form speech using global context arXiv:2609.29428v1 Announce Type: new Abstract: Recent advances in speech language models have improved automatic speech recognition (ASR) for long-form audio. However, accurately and consistently transcribing domain-specific terminology remains challenging. Motivated by the… 25 arXiv — NLP / Computation & Language research 3d ago IterSynth: Rethinking Deep Search Agents via Role-Decoupled Iterative Synthesis arXiv:2609.29444v1 Announce Type: new Abstract: Deep search requires LLM agents to decompose complex queries, search for evidence, and synthesize grounded answers, yet existing ReAct-style agents suffer from two limitations: role coupling, where one policy must handle planning,… 18 arXiv — NLP / Computation & Language research 3d ago LLMersion: A Local-First AI Agent Framework for Low-Cost Home Language Learning toward Educational Equity arXiv:2609.29672v1 Announce Type: new Abstract: Artificial intelligence helps education most where an essential provision has been rationed by cost. For language learners that provision is a teacher's voice, which binds listening, reading, speaking, and writing into one act.… 8 arXiv — NLP / Computation & Language research 3d ago Stochastic Semantic Evidence Graphs: Uncertainty Propagation and Governance for Agentic AI arXiv:2609.29703v1 Announce Type: new Abstract: AI-agent evaluations usually inspect a final answer, yet error may enter through evidence, retrieval, prompting, generation or decision mapping. We introduce a stochastic semantic evidence graph (SSEG), a hierarchical stochastic… 20 arXiv — NLP / Computation & Language research 3d ago PPTBench: Can Coding Agents Reconstruct the Visual World through Structured, Editable Slides arXiv:2609.29718v1 Announce Type: new Abstract: Coding agents are beginning to act in the visual world. They now build webpages, GUIs, games, 3D scenes, diagrams, and documents. Success in such visual coding requires bridging two spaces: inferring visual structure and expressing… 32 arXiv — NLP / Computation & Language research 3d ago Agentic Detection of Online Conspiracies arXiv:2609.30250v1 Announce Type: new Abstract: Conspiratorial discourse on social media is not always expressed through explicit claims or stable lexical markers. The same surface content may express endorsement, legitimate concerns, criticism, satire, or mockery. The main… 19 arXiv — NLP / Computation & Language research 3d ago When Should Forecasting Agents Reason? Behavioral Stress Tests for Reliability Routing arXiv:2609.28475v1 Announce Type: cross Abstract: Forecasting agents increasingly combine language-model reasoning, retrieval, ensembling, and calibration, but it remains unclear when each behavior should be trusted. We study this question on ForecastBench-style binary… 11 arXiv — NLP / Computation & Language research 3d ago MeshHeal: Two-Timescale Self-Healing for Gray Failures in Decentralized LLM Agent Networks arXiv:2609.29015v1 Announce Type: cross Abstract: Decentralized LLM-based multi-agent systems coordinate through local interactions, but an agent can remain responsive while its task-solving quality persistently degrades. Such gray failures require protecting current tasks… 29 r/LocalLLaMA community 3d ago M5 Ultra 80Core GLM-5.3-Flash on DwarfStar Speeds I've been playing around with various models on the M5 Ultra 256GB 80-core Mac Studio. These are the results over many rounds of agentic inferencing. I'm happy with the performance. Glad to have the large amount of RAM. But it does feel like the GPU is underpowered for this… 6 r/LocalLLaMA community 3d ago normalize benchmarks from different time period LiveBench has benchmark snapshots from different points in time. Could someone run an agent to normalize the values across these snapshots so we can compare model strength consistently from 2024 through 2026? Right now, it’s difficult to make meaningful comparisons across the… 18 Simon Willison community 3d ago Note on 24th September 2026 The more time I spend working with coding agents, the more convinced I am that they make software engineering even harder. We can do amazing things with them, but unlocking their full potential requires extraordinary discipline and knowledge. Tags: coding-agents , ai , llms 10 r/LocalLLaMA community 3d ago I'm trying to post-train AliceAI-Foundation-80B-A3B-Base myself Just wanted to share with someone - don't have much to report yet. I am interested in this new AliceAI model and have been wanting to make a community impact for a while - and releasing an initial agentic version of this model sounds cool. I am training on 3 32gb v100s (which… 14 GitHub Blog — AI & ML official-blog 3d ago AI-powered fuzzing with the GitHub Security Lab Taskflow Agent In this blog post, I explain how to use the new fuzzing taskflow based on the GitHub Security Lab Taskflow Agent AI framework. The post AI-powered fuzzing with the GitHub Security Lab Taskflow Agent appeared first on The GitHub Blog . 31 Hacker News — AI on Front Page community 3d ago Show HN: Whiteboard (YC W26) – An open-source IDE for thoughtful software design Hello! We’re Sid, Alex, Ketan, and Milan. We’re building Whiteboard ( https://whiteboard.dev.fast/ ), an open-source desktop app where humans and agents can architect software together in a common workspace. Here’s our repo: https://github.com/devdotfast/whiteboard . We were… 4 Ars Technica — AI news-outlet 3d ago OpenAI agent “didn’t accept no for an answer” in Australian government breach "There will obviously be legal consequences," prime minister promises. 18 r/LocalLLaMA community 3d ago PSA: llama.cpp -cram should be increased for agentic workflows (default is 8192) Just a quick PSA. llama.cpp does have prompt caching. if you are running large context lengths and have long multiturn projects, increasing -cram can provide you with massive speedups. There is a point where context lengths can get so large that 8192mb is not enough and the… 6 TechCrunch — AI news-outlet 3d ago Ando wants to take on Slack with a team messaging app that lets humans and agents work together Ando has raised $20 million in pre-seed and seed funding from investors including Accel, Index Ventures and Emergence. 11 r/LocalLLaMA community 3d ago list of entities hacked by openai grows by one Rogue OpenAI agent 'infiltrated' Australian government website in world first https://www.bbc.com/news/articles/c6vgy0333dppo   submitted by   /u/fulowa [link]   [comments] 35 OpenAI official-blog 3d ago Ringg’s AI agents resolve up to 65% of customer calls with OpenAI Using GPT-5.6, Ringg powers multilingual agents across voice, chat, WhatsApp, and web for 90% less cost vs. GPT-4.1. 35 Hacker News — AI on Front Page community 4d ago Early rogue AI agent activity and attempts to hack found on urlquery.net Article URL: https://transluce.org/agent-activity Comments URL: https://news.ycombinator.com/item?id=49826565 Points: 235 # Comments: 222 15 arXiv — Machine Learning research 4d ago What Makes a Terminal-Bench Task Hard? Separating Genuine Hardness from Fake-Hardness on an Adjudicated Agentic Corpus arXiv:2609.26826v1 Announce Type: new Abstract: Frontier benchmarks need tasks that current models cannot solve. But a task that no model solves is not automatically a hard task. The same zero pass rate can come from a real capability gap, but it can also come from missing… 13 arXiv — Machine Learning research 4d ago Marginally Correct Tool Caches Can Reverse Group-Normalized Policy Updates arXiv:2609.26866v1 Announce Type: new Abstract: Tool-result caching reduces repeated execution in agent training, but also couples rollout randomness. We study a two-action model in which independent and shared execution preserve every rollout's conditional reward distribution.… 24 arXiv — Machine Learning research 4d ago On Preference Coverage Collapse from Hindsight Relabeling in Multi-Objective Reinforcement Learning arXiv:2609.26918v1 Announce Type: new Abstract: Hindsight relabeling which retroactively replacing a transition's goal with the outcome the agent actually achieved is an effective tool for improving sample-efficiency in Reinforcement Learning (RL). A natural extension to… 23 arXiv — NLP / Computation & Language research 4d ago ChipMEM: Verification-Grounded Memory for EDA Agents arXiv:2609.27067v1 Announce Type: cross Abstract: Large language model (LLM)-based agents use Electronic Design Automation (EDA) tools to generate and revise register-transfer-level (RTL) designs under synthesis and verification feedback. Recent methods learn from this feedback… 33 arXiv — Machine Learning research 4d ago Discover, Falsify, Revise: Auditing Input-Use Claims from Source Code to Predictive Contribution in Agent-Discovered Cell Models arXiv:2609.27234v1 Announce Type: new Abstract: AI virtual cells aim to predict cellular responses to specified interventions, yet held-out predictive performance alone does not establish use of the supplied perturbation information. This prediction-claim gap matters in agentic… 6 arXiv — Machine Learning research 4d ago SR-Fraud: An Outcome-Supervised Reflective LLM Agent Framework for Non-Stationary Payment Fraud Detection arXiv:2609.27287v1 Announce Type: new Abstract: Real-time payment fraud detection is a non-stationary streaming prediction problem: adversaries adapt before supervised labels mature, and localized burst attacks can cause losses before retraining. Production systems typically… 31 arXiv — Machine Learning research 4d ago KITE: KV-Invariant Transformer Expansion for Efficient Agentic LLM Scaling arXiv:2609.27294v1 Announce Type: new Abstract: Scaling a language model is not only a question of final quality: the architectural choice determines how much computation is spent during training, prompt processing, and autoregressive decoding to achieve certain model quality.… 14 arXiv — Machine Learning research 4d ago Forecast Workflow Bench: Evaluating Language-Model Decisions with Budgeted Forecast Tools arXiv:2609.27385v1 Announce Type: new Abstract: Time-series foundation models (TSFMs) provide forecasts for operational decisions, but accuracy alone does not determine their value. Evaluating agents that use these models requires measuring decision quality and forecast cost.… 27 arXiv — NLP / Computation & Language research 4d ago ProCredit: From Outcome Rewards to Progress Credit in Agentic Reinforcement Learning arXiv:2609.27532v1 Announce Type: cross Abstract: Long-horizon agentic tasks require an agent to modify an environment through a sequence of tool calls, with success determined by the final state. The standard recipe assigns a single outcome reward at the end and compares… 29 arXiv — Machine Learning research 4d ago The Capability Manifold and ML Scaling Laws arXiv:2609.27588v1 Announce Type: new Abstract: Existing machine learning (ML) scaling laws relate predictive loss to compute, model parameters, and data. However, as models are increasingly deployed through agentic harnesses, loss alone is insufficient to characterize… 18 arXiv — Machine Learning research 4d ago Learning from Failures: Heterogeneous Graph Memory for Small Language Model Tool-Using Agents arXiv:2609.28003v1 Announce Type: new Abstract: Small and medium-sized language models offer cost-effective executors for tool-using agents, making them attractive for local and large-scale deployment. However, in long-horizon and stateful environments, they often make… 8 arXiv — NLP / Computation & Language research 4d ago UniDataAgent: An Ontology-Grounded Agent for Enterprise Question-to-Report Automation arXiv:2609.27257v1 Announce Type: new Abstract: Enterprise data agents must preserve organization specific semantics, not just translate questions into queries. We present ChinaUnicom DataAgent (UniDataAgent), an ontology grounded system for reusable question-to-report analysis… 25 arXiv — NLP / Computation & Language research 4d ago Guides That Cause Actions: An Offline Study of Guide-Action Mutual Reinforcement in Multimodal Web Agents arXiv:2609.27353v1 Announce Type: new Abstract: Web agents are usually evaluated in live environments, where environment state and judge models drift between runs, so the same checkpoint rarely reproduces the same score, making controlled studies of training phenomena… 5 arXiv — NLP / Computation & Language research 4d ago SkillGym: Internalizing Human Skills into LLMs for Real-World Problem Solving arXiv:2609.27717v1 Announce Type: new Abstract: Human-written agent skills encode rich workflows for real-world problem solving, but are typically used as external inference-time instructions rather than internalized as reusable model capabilities. We introduce… 31 arXiv — NLP / Computation & Language research 4d ago Improving LLM-based Autonomous Web Agents with Filtering arXiv:2609.27770v1 Announce Type: new Abstract: Autonomous web agents, powered by Large Language Models (LLMs), have garnered significant attention for automating various web-based tasks with multi-step reasoning and decision-making capabilities. An open research question in the… 29 arXiv — NLP / Computation & Language research 4d ago Beyond Unsafe Detection: Counterfactually Anchored Evidence Attribution for Multi-Turn LLM Safety Failures arXiv:2609.27773v1 Announce Type: new Abstract: As Large Language Models (LLMs) move from conversational assistants to advanced agentic systems, guardrail failures can convert adversarial intents into harmful executions. However, most guardrail evaluation frameworks focus only… 29 arXiv — NLP / Computation & Language research 4d ago Delegated Misalignment: How Multi-Agent Structures Amplify LLM Safety Risks arXiv:2609.27900v1 Announce Type: new Abstract: Large language models (LLMs) are increasingly deployed in multi-agent systems where a principal agent decomposes tasks and delegates them to subordinate agents that may invoke external tools. Safety alignment, however, is still… 14 arXiv — NLP / Computation & Language research 4d ago Agent-Editing World Model: Rethinking World Modeling for LLM Agents arXiv:2609.28416v1 Announce Type: new Abstract: Recent advances in large language models (LLMs) have enabled agents to tackle long-horizon tasks across diverse environments. To further improve agent performance, existing language world models typically predict environment… 34 arXiv — NLP / Computation & Language research 4d ago CAVEAT: Towards Robust Computer-Use Agents in Incentive-Misaligned Environments arXiv:2609.27273v1 Announce Type: cross Abstract: Computer-use agents (CUAs) increasingly act on behalf of users online. What happens when the environments they operate in have incentives that do not align with the user's? In online marketplaces, for example, platforms may favor… 32 arXiv — NLP / Computation & Language research 4d ago EnSIMem: Entity-Structured Indexing for Long-Term Agent Memory arXiv:2609.27279v1 Announce Type: cross Abstract: An agent that interacts with users over long periods must recall facts, preferences, events, and changes from a continuously growing interaction history. Existing memory systems often compress interactions into generic summaries… 13 Page 2 of 10 · 500 articles ← Newer Older →