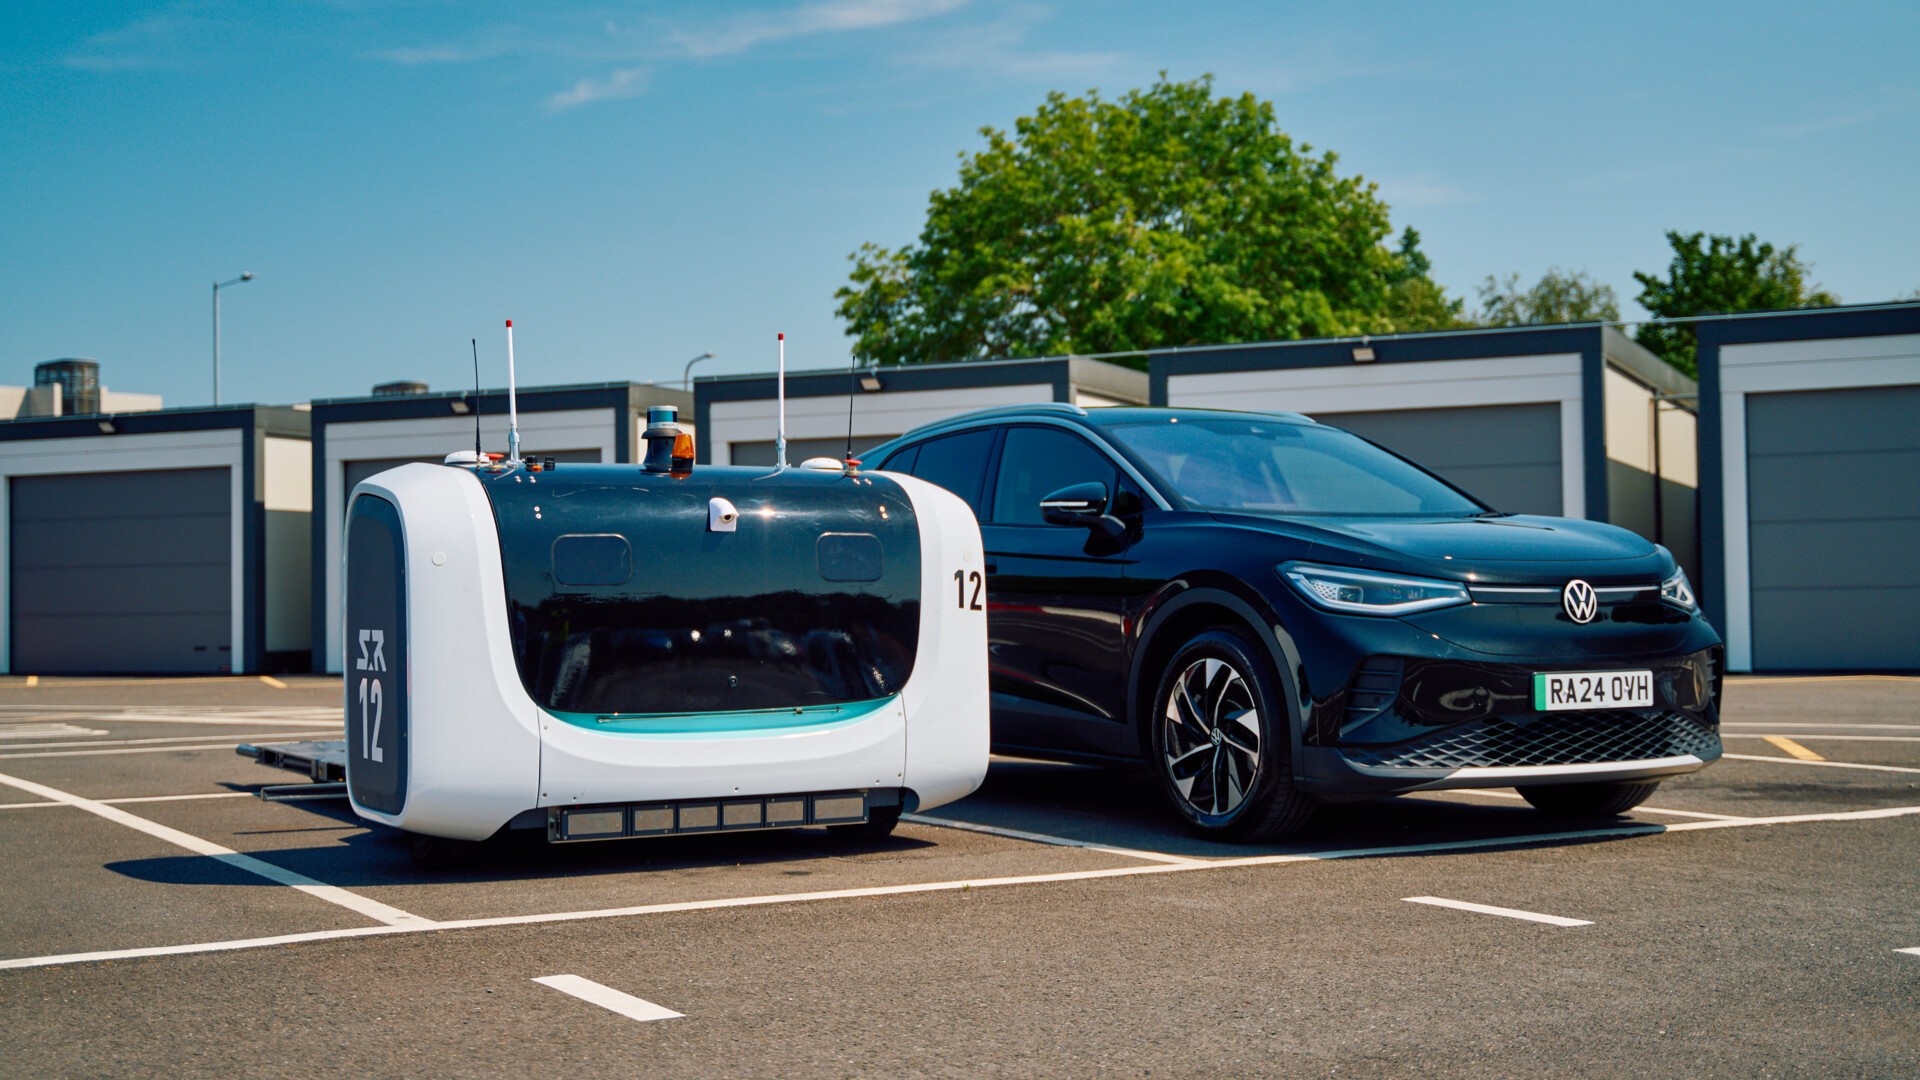
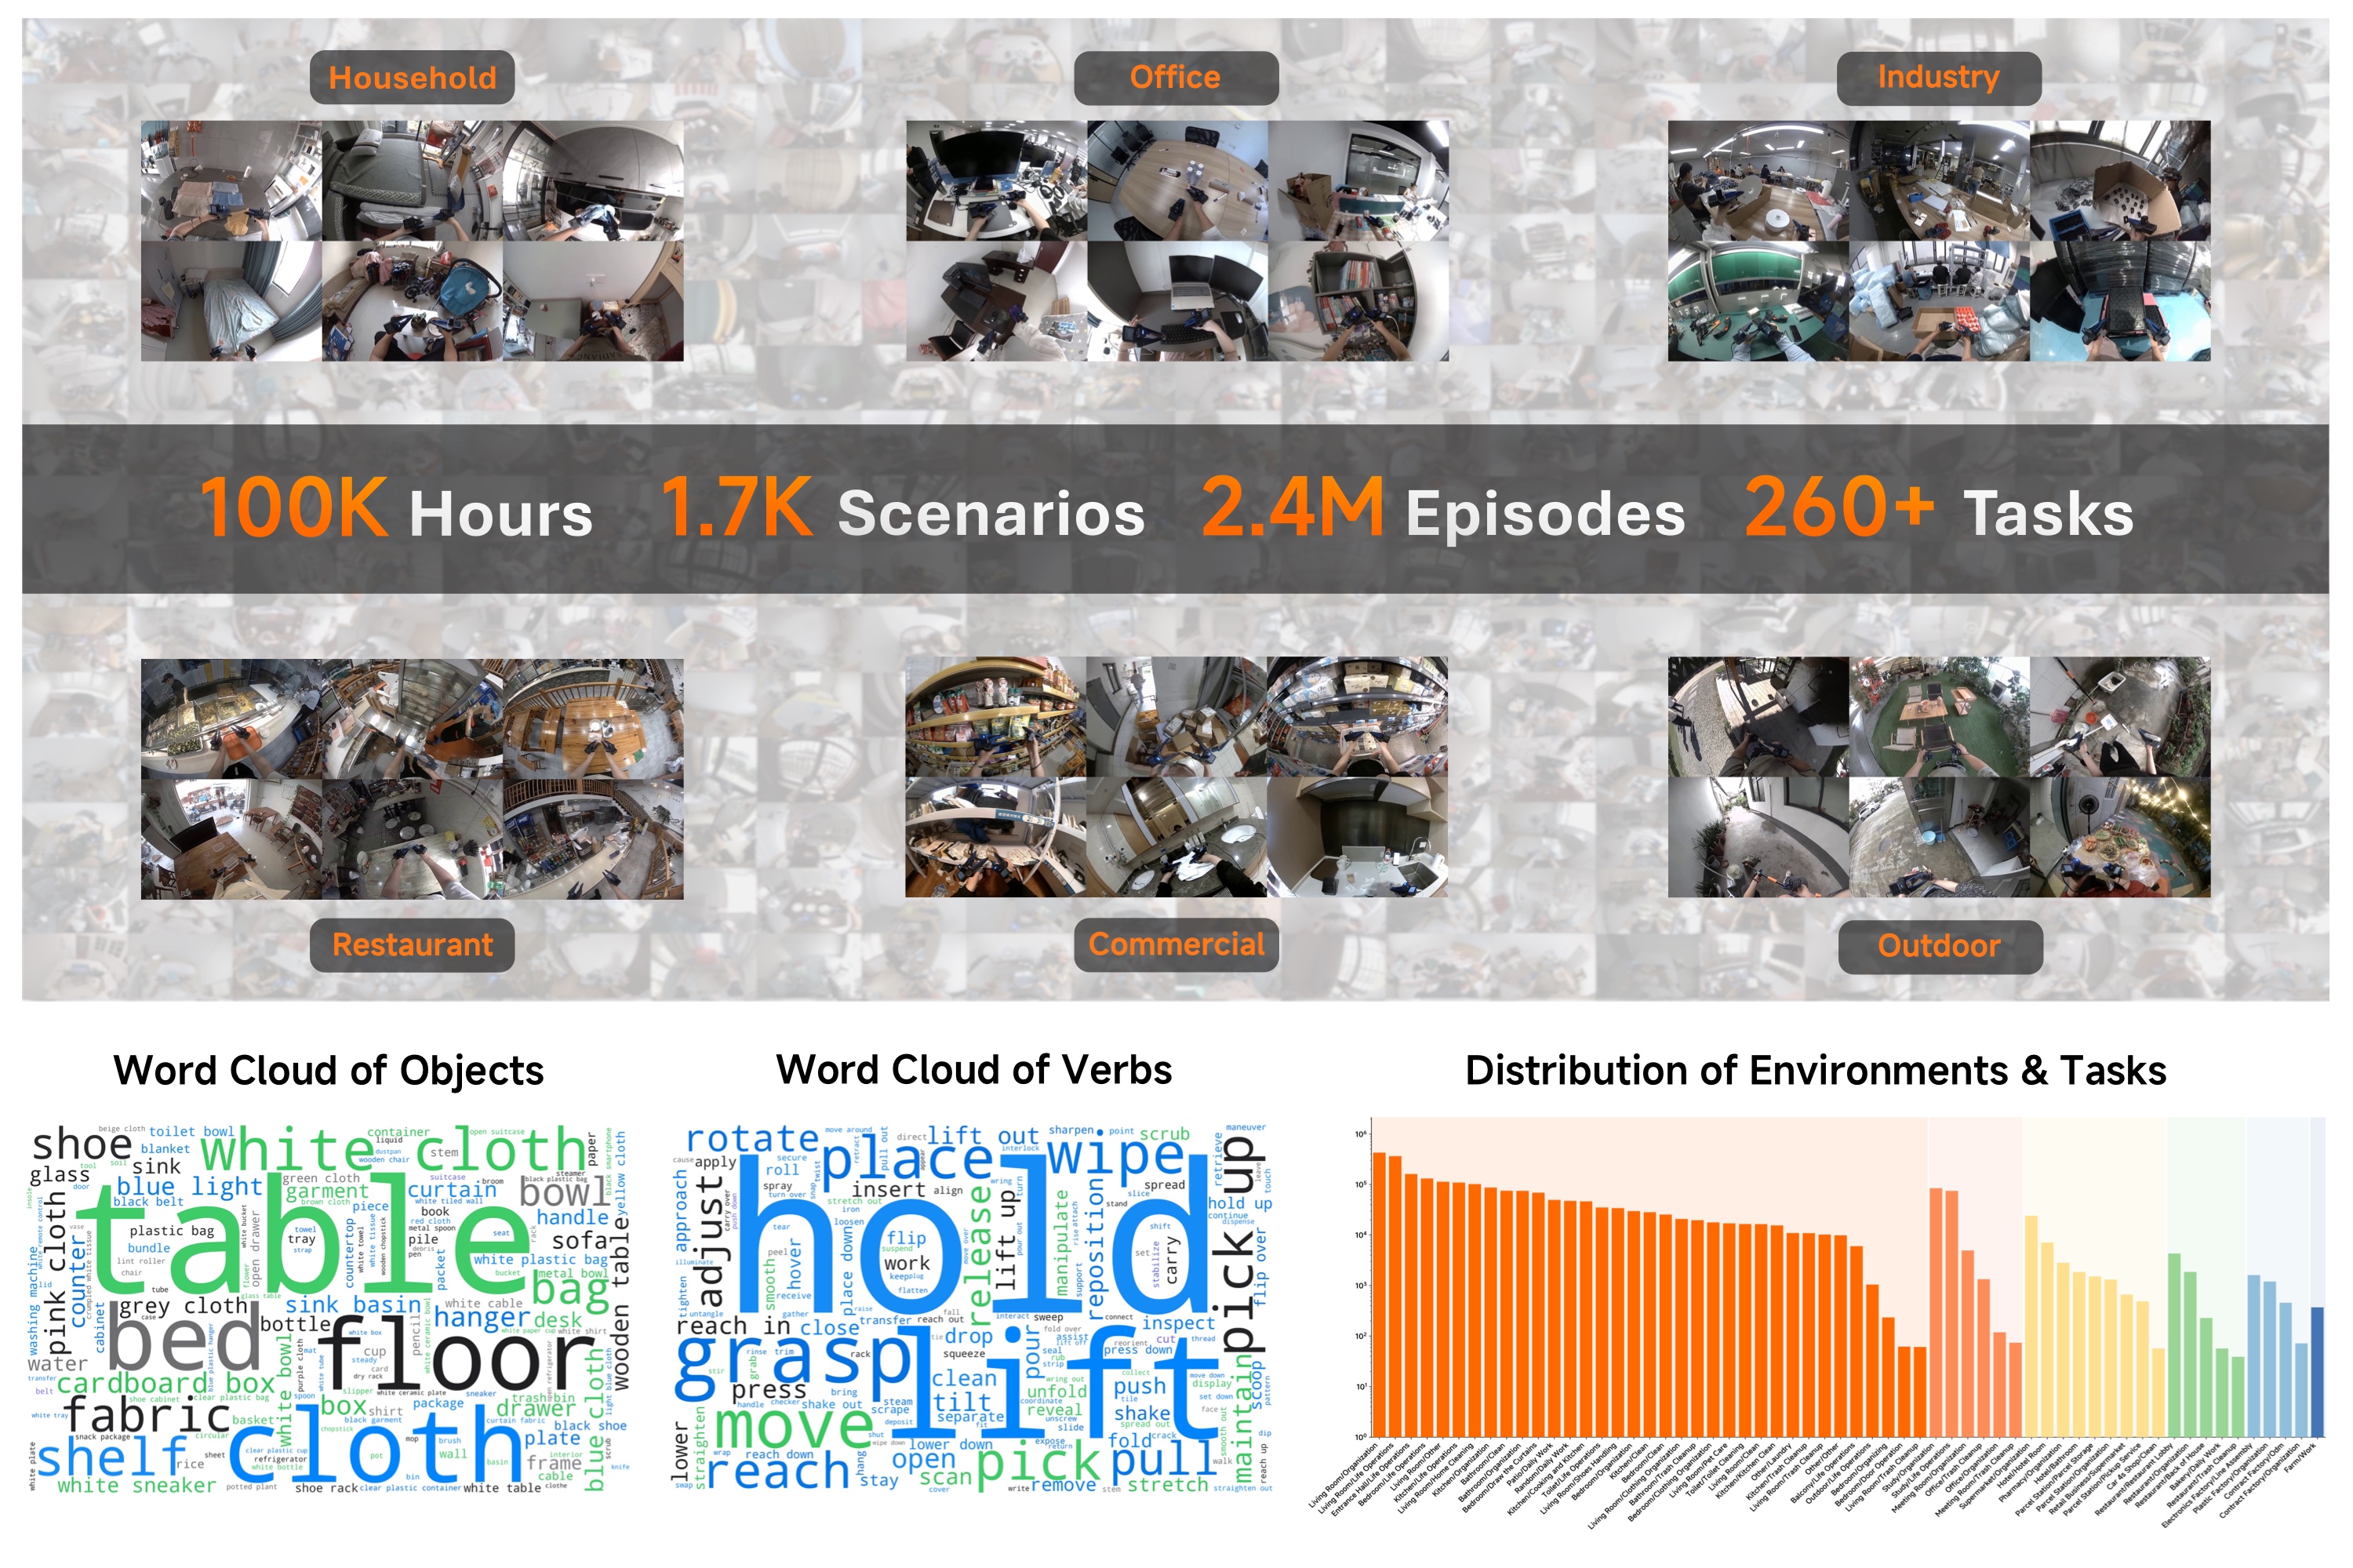
News / #robotics Tag Robotics 500 articles archived under #robotics · RSS Sign in to follow r/MachineLearning community 2mo ago I built a deep learning library from scratch in C that lets you train language models [P] my goal was to train a Language model (SLM) entirely from scratch so no ML libraries allowed . so i gathered what's needed to make it happen : from tensor manipulation (views, operations , allocations) the autograd ( a DAG that retains the previous operations and inputs in order… 7 Google DeepMind official-blog 2mo ago Gemini Robotics 2 brings whole body intelligence to robots July 30, 2026 Models Gemini Robotics 2 brings whole body intelligence to robots Carolina Parada Share From feet to fingertips — we are teaching robots intelligent whole-body control, fine dexterity, and teamwork to complete a broad range of complex tasks For decades, we’ve… 20 Hugging Face Daily Papers research 2mo ago Data Pyramid for Embodied Manipulation Abstract Multimodal foundation models learned to see and to speak by consuming the whole internet. Embodied agents admit no such shortcut, since they require data that couple observations with physical states and actions. These signals can be provided, to varying degrees, by… 18 Hugging Face Daily Papers research 2mo ago Progress Reward Modeling for Robotic Learning: A Comprehensive Survey Abstract Robotic learning takes place in dynamic environments with large behavior spaces. A terminal success signal only tells the robot whether the task is completed. It does not explain whether the current behavior is making progress, remaining unchanged, or undoing earlier… 31 Import AI (Jack Clark) community 2mo ago Import AI 466: The bitter lesson for robotics, AIs complete week-long programming tasks; and OpenAI's accidental AI hacker The warning shots will continue until civilization wakes up 16 TechCrunch — AI news-outlet 2mo ago Enigma raises $70M to make controlling a robot as easy as adjusting the volume The massive seed round was led by Index Ventures and Ribbit Capital, with participation from Sarah Guo's Conviction Partners. 32 Hugging Face official-blog 2mo ago NVIDIA Cosmos-H-Dreams: Bringing Real-Time Generative Simulation to Surgical Robotics Back to Articles a]:hidden"> NVIDIA Cosmos-H-Dreams: Bringing Real-Time Generative Simulation to Surgical Robotics Enterprise + Article Published July 27, 2026 Upvote 1 Lukas Zbinden lzbinden nvidia Javier Gamazo javirk1 nvidia Mostafa Toloui mtoloui nvidia Sean Huver shuver… 12 arXiv — Machine Learning research 2mo ago Ordered Action Tokens for Visuomotor Policy Learning arXiv:2607.21670v1 Announce Type: cross Abstract: Action tokenization maps continuous robot action chunks to discrete tokens and has become an important interface for modern visuomotor policies. Existing approaches either rely on analytical discretization methods that produce… 11 arXiv — NLP / Computation & Language research 2mo ago Progress Reward Modeling for Robotic Learning: A Comprehensive Survey arXiv:2607.21655v1 Announce Type: cross Abstract: Robotic learning takes place in dynamic environments with large behavior spaces. A terminal success signal only tells the robot whether the task is completed. It does not explain whether the current behavior is making progress,… 8 r/LocalLLaMA community 2mo ago Unexpected use of local llm I was refreshing my youtube and found out my favourite reviewer uploaded a battery test of 78 smartphones: https://youtu.be/MpgUFrsIWSQ the author said they started using robotic arm to simulate a person using the phone but they wanted to further enhance it by using agentic ai.… 19 TechCrunch — AI news-outlet 2mo ago Are brain waves the next unlock for physical AI? Forget YouTube videos—frontier physical AI models need multiple camera angles, dense annotation, and soon, brain wave readings. 28 Hacker News — AI on Front Page community 2mo ago London Gatwick has launched a robotic airport parking service Article URL: https://aerospaceglobalnews.com/news/gatwick-airport-robotic-parking-stanley-robotics/ Comments URL: https://news.ycombinator.com/item?id=49058669 Points: 211 # Comments: 146 33 r/MachineLearning community 2mo ago Why first person video may matter for robot learning[D] I can see why first-person video might help a robot model, but not because the robot can copy a human hand. The joints, reach, timing, and control space are all different. What may transfer is the sequence of visual attention: which object enters view, what changes before… 20 Hugging Face Daily Papers research 2mo ago Robostral Navigate Abstract Deploying navigation systems at scale requires a recipe that minimizes sensor assumptions, generalizes across robot embodiments, and trains efficiently. Yet, today's best systems depend on depth sensors, multi-camera rigs, or pre-built maps, limiting the hardware they… 33 Hugging Face Daily Papers research 2mo ago TableVerse: A Large-scale Tabletop Dataset with Real-world Grounded Layouts for Generalizable Manipulation Abstract The development of generalizable robotic manipulation policies is inherently bounded by the availability of large-scale, high-fidelity scene data. While recent automated synthesis methods attempt to bridge this gap via text-to-layout hallucination or simplified… 5 Latent.Space news-outlet 2mo ago [AINews] Black Forest Labs FLUX 3 - Multimodal Flow Models that beat Seedance 2.0, Gemini Omni and Grok Imagine, and FLUX-mimic video-action robotics model A HUGE win for BFL! 22 Hugging Face Daily Papers research 2mo ago SLAM in Low-Light Environments: Project Report Abstract Simultaneous localization and mapping (SLAM) is one of the fundamental problems in robotics, as it enables autonomous operations in real-world scenarios. Under low illumination, reduced contrast, sensor noise, and motion blur degrade both feature extraction and feature… 15 Hugging Face Daily Papers research 2mo ago SeededGrasp: Language-Guided Grasping in Complex Scenes with Multiple Embodiments Abstract Practical robotic grasping in complex scenes requires both 3D spatial reasoning and alignment with task-specific requirements. Vision-language models (VLMs) offer a natural way to specify these requirements using language, but existing approaches either use a VLM to… 37 arXiv — Machine Learning research 2mo ago Towards Torque-Driven Reinforcement Learning for Quadruped Locomotion arXiv:2607.18365v1 Announce Type: cross Abstract: Reinforcement learning (RL) for legged robots is advancing locomotion, demonstrating its ability to adapt to new and challenging terrain. Traditionally, these RL locomotion frameworks are position-based, making the policy less… 25 Hugging Face Daily Papers research 2mo ago Generalizable VLA Finetuning via Representation Anchoring and Language-Action Alignment Abstract Finetuning a pretrained vision-language model (VLM) on robot demonstrations via behavior cloning (BC) has become the standard recipe for vision-language-action (VLA) policies. However, BC finetuning progressively overwrites the pretrained representations that support… 31 TechCrunch — AI news-outlet 2mo ago Travis Kalanick’s robotics company raises $1.7B, led by a16z Uber is also investing in Travis Kalanick's company Atoms, which has made gauzy claims about using industrial AI to modernize the world. 6 Ars Technica — AI news-outlet 2mo ago Hyundai claims humanoid robot plan is not part of talks with striking workers Union previously warned automaker that any robot deployment must be negotiated. 21 Hugging Face Daily Papers research 2mo ago Masked Visual Actions for Unified World Modeling Abstract Video models absorb rich priors over how the visual world moves, interacts, and responds to contact, making them promising substrates for robotic world modeling. The central challenge is how to communicate action to such models in a form aligned with the visual space in… 27 arXiv — Machine Learning research 2mo ago Deep learning-based prediction of time-resolved adhesive forces in viscoelastic Hertzian contacts arXiv:2607.19060v1 Announce Type: new Abstract: Fast prediction of the response of adhesive soft viscoelastic contacts represents a current challenge in soft robotics and for gripping and manipulation tasks. Determining the complete time-resolved force trajectory requires full… 34 Hugging Face official-blog 2mo ago The State of Simulation for Physical AI: An Overview Back to Articles a]:hidden"> The State of Simulation for Physical AI: An Overview Enterprise + Article Published July 21, 2026 Upvote - Johnny Nuñez Cano johnnynv nvidia Mitesh Patel mitp nvidia Asier Arranz asiernvidia nvidia lior ben horin liorbenhorin-nv nvidia Raymond Lo… 23 TechCrunch — AI news-outlet 2mo ago Gritt exits stealth with $34 million for robots to build solar plants—then, everything else Gritt is coming out of stealth with $34 million and plan to automate the hardest tasks on construction sites. 31 arXiv — NLP / Computation & Language research 2mo ago Cross-Branch Conflict as a Shield: Safeguarding Facial Identities in Unified Multimodal Image Editing arXiv:2607.16898v1 Announce Type: cross Abstract: Unified multimodal models (UMMs) have recently demonstrated powerful instruction-based image editing capabilities, but they also raise serious concerns about unauthorized manipulation of personal portraits. Existing adversarial… 9 Hugging Face Daily Papers research 2mo ago JoyNexus: Service-Oriented Multi-Tenant Post-Training for VLA Models Abstract The post-training of Vision-Language-Action (VLA) models is essential due to the diversity of simulators, robot embodiments, and task objectives. Existing compute services, whether offered as direct accelerator rental or batch-workload submission, typically allocate an… 13 Hugging Face official-blog 2mo ago Grabette: an open system to record robot-manipulation data Back to Articles a]:hidden"> Grabette: an open system to record robot-manipulation data. And build a shared dataset, together. Published July 21, 2026 Update on GitHub Upvote 5 Steve Nguyen SteveNguyen pollen-robotics Claire Houziel chouziel pollen-robotics Gaelle Lannuzel… 17 Hugging Face official-blog 2mo ago Introducing Cosmos 3 Edge Back to Articles a]:hidden"> Introducing Cosmos 3 Edge Enterprise + Article Published July 20, 2026 Upvote - Pranjali Joshi PranjaliJoshi nvidia Saeed Babamohamadi SaeedBabamohamadi nvidia The real world is vast and to operate in it physical AI systems need to understand how a… 32 NVIDIA Developer Blog official-blog 2mo ago Integrate NVIDIA Omniverse RTX Sensor Simulation Into Existing Apps Developers building 3D, design, simulation, robotics, and industrial digital twin applications need ways to bring physical AI capabilities into the tools and... 12 Hugging Face Daily Papers research 2mo ago See like a Robot: Robot-Centric Pointmaps for Vision-Language-Action Models Abstract Vision-language-action (VLA) models predict robot actions from visual observations and language instructions. These actions are defined in the robot's own 3D coordinate frame, yet most VLAs observe the scene in the camera frame, creating a frame mismatch between where… 16 r/LocalLLaMA community 2mo ago MiniCPM-Robot model series - MiniCPM-RobotManip & MiniCPM-RobotTrack 🚀 MiniCPM enters the physical world — enabling robots to understand, remember, and act. We open-source MiniCPM-Robot, our first embodied AI model series, including: 🤖 MiniCPM-RobotManip — a 1.5B general-purpose Vision-Language-Action (VLA) model for robotic manipulation. 🐕… 23 Hacker News — AI on Front Page community 2mo ago Xiaomi-Robotics-1 Article URL: https://robotics.xiaomi.com/xiaomi-robotics-1.html Comments URL: https://news.ycombinator.com/item?id=48974454 Points: 215 # Comments: 150 9 Hugging Face Daily Papers research 2mo ago Xiaomi-Robotics-1: Scaling Vision-Language-Action Models with over 100K Hours of Real-World Trajectories Abstract We present Xiaomi-Robotics-1, a foundational vision-language-action (VLA) model capable of (1) following diverse language instructions to perform a wide range of mobile manipulation tasks in unseen environments out-of-the-box, and (2) efficiently adapting to novel… 21 r/LocalLLaMA community 2mo ago How long before Chinese models fully surpass US models? Given the rate at which they have been advancing, I predict we are six months away from a leapfrog moment. EDIT - For those responding “never - they just copy everything”, how is that working out for EV and robotics? The idea that China is still some backwater knock-off empire… 14 r/LocalLLaMA community 2mo ago SigLIP 2 text embedding on CPU with Rust + ONNX We’re building a robotics data platform with a lot of images, video, and text metadata. For search, we use SigLIP 2. GPUs handle batched asynchronous image/video embedding and indexing, while this small Rust + ONNX Runtime service handles live text queries on CPU. Both land in… 37 TechCrunch — AI news-outlet 2mo ago Agility Robotics plants its flag in Tesla’s backyard Agility is opening a new training center for its Digit robots in Fremont, California. 29 TechCrunch — AI news-outlet 2mo ago Patreon stops asking AI bots not to scrape — and starts blocking them Patreon is strengthening its defenses against AI scraping by working with Cloudflare to block bots that train AI models on creators’ content without permission. The move marks a shift away from relying on websites using robots.txt alone to actively block unauthorized AI training. 36 Hugging Face Daily Papers research 2mo ago SUFLECA: Scaling Up Feature Learning for CAD-to-image Alignment Abstract CAD-to-image alignment aims to estimate an object's 9D pose (rotation, translation, and anisotropic scale) from a single RGB image, enabling applications in robotics and augmented reality. Recent zero-shot methods use visual foundation models to match image regions to… 22 Hugging Face Daily Papers research 2mo ago RoboTTT: Context Scaling for Robot Policies Abstract Recent robot foundation models operate with single-step or short-history visuomotor context. We introduce Test-Time-Training Robot Policies (RoboTTT), a robot model and training recipe that scale visuomotor context to 8K timesteps, three orders of magnitude beyond… 29 arXiv — Machine Learning research 2mo ago Active Real-World Factor-Based Evaluation for Generalist Robot Policies arXiv:2607.14439v1 Announce Type: new Abstract: Generalist robot manipulation policies trained on large, diverse datasets have shown remarkable promise across a wide range of tasks. However, rigorously evaluating these policies remains a fundamental challenge. Real-world… 18 arXiv — Machine Learning research 2mo ago Never Too Late for Force: Accelerating VLA Post-Training with Reactive Force Injection arXiv:2607.14236v1 Announce Type: cross Abstract: Pretrained vision-language-action (VLA) policies provide strong language-conditioned manipulation knowledge, but they remain largely vision-driven and can struggle once manipulation enters contact states where the scene is… 27 arXiv — Machine Learning research 2mo ago DiMaS: Distribution Matching for Steering Vision-Language-Action Models arXiv:2607.14280v1 Announce Type: cross Abstract: Flow-matching-based vision-language-action (VLA) models have emerged as powerful policies for robotic manipulation, yet a critical capability remains underexplored: fine-grained behavioral control, the ability to govern how a… 22 arXiv — NLP / Computation & Language research 2mo ago MEMORA: Embodied Action Memory from Egocentric Videos for Reasoning and Planning arXiv:2607.14252v1 Announce Type: cross Abstract: Long-horizon robot planning requires more than predicting what actions will do next; it also requires memory of the embodied experience that makes future goals interpretable. People do not plan from the present scene alone: they… 36 Ars Technica — AI news-outlet 2mo ago Fear of humanoid robots spurs human workers to strike at Hyundai auto factory Hyundai aims to deploy 25,000 Atlas robots starting with US factories in 2028. 11 Hugging Face Daily Papers research 2mo ago SPEAR: A Simulator for Photorealistic Embodied AI Research Abstract Interactive simulators have become powerful tools for training embodied agents and generating synthetic visual data, but existing photorealistic simulators suffer from limited generality, programmability, and rendering speed. We address these limitations by introducing… 14 Latent.Space news-outlet 2mo ago 🔬 The Lab of the Future Should Feel Like a Data Center — Andy Beam & Rafa Gómez-Bombarelli, Lila Sciences Lila is betting that science, not the internet, is the last untapped source of training data. We went to find out what that actually looks like in a room full of robots. 30 arXiv — Machine Learning research 2mo ago Where Should RL Post-Training Compute Go? Model Size, Search, Learning, and Feedback arXiv:2607.13389v1 Announce Type: new Abstract: Reinforcement Learning (RL) post-training is increasingly used to adapt foundation models for reasoning, planning, and feedback-driven robot-learning pipelines, but constrained post-training resources are often summarized by a… 17 arXiv — Machine Learning research 2mo ago HRIBench: Benchmarking Interaction-Centric Human-Robot Collaboration arXiv:2607.13056v1 Announce Type: cross Abstract: Current vision-language-action (VLA) benchmarks primarily evaluate isolated manipulation skills while leaving human-robot interaction structure largely unmodeled. However, real-world collaboration fundamentally requires… 12 Page 5 of 10 · 500 articles ← Newer Older →