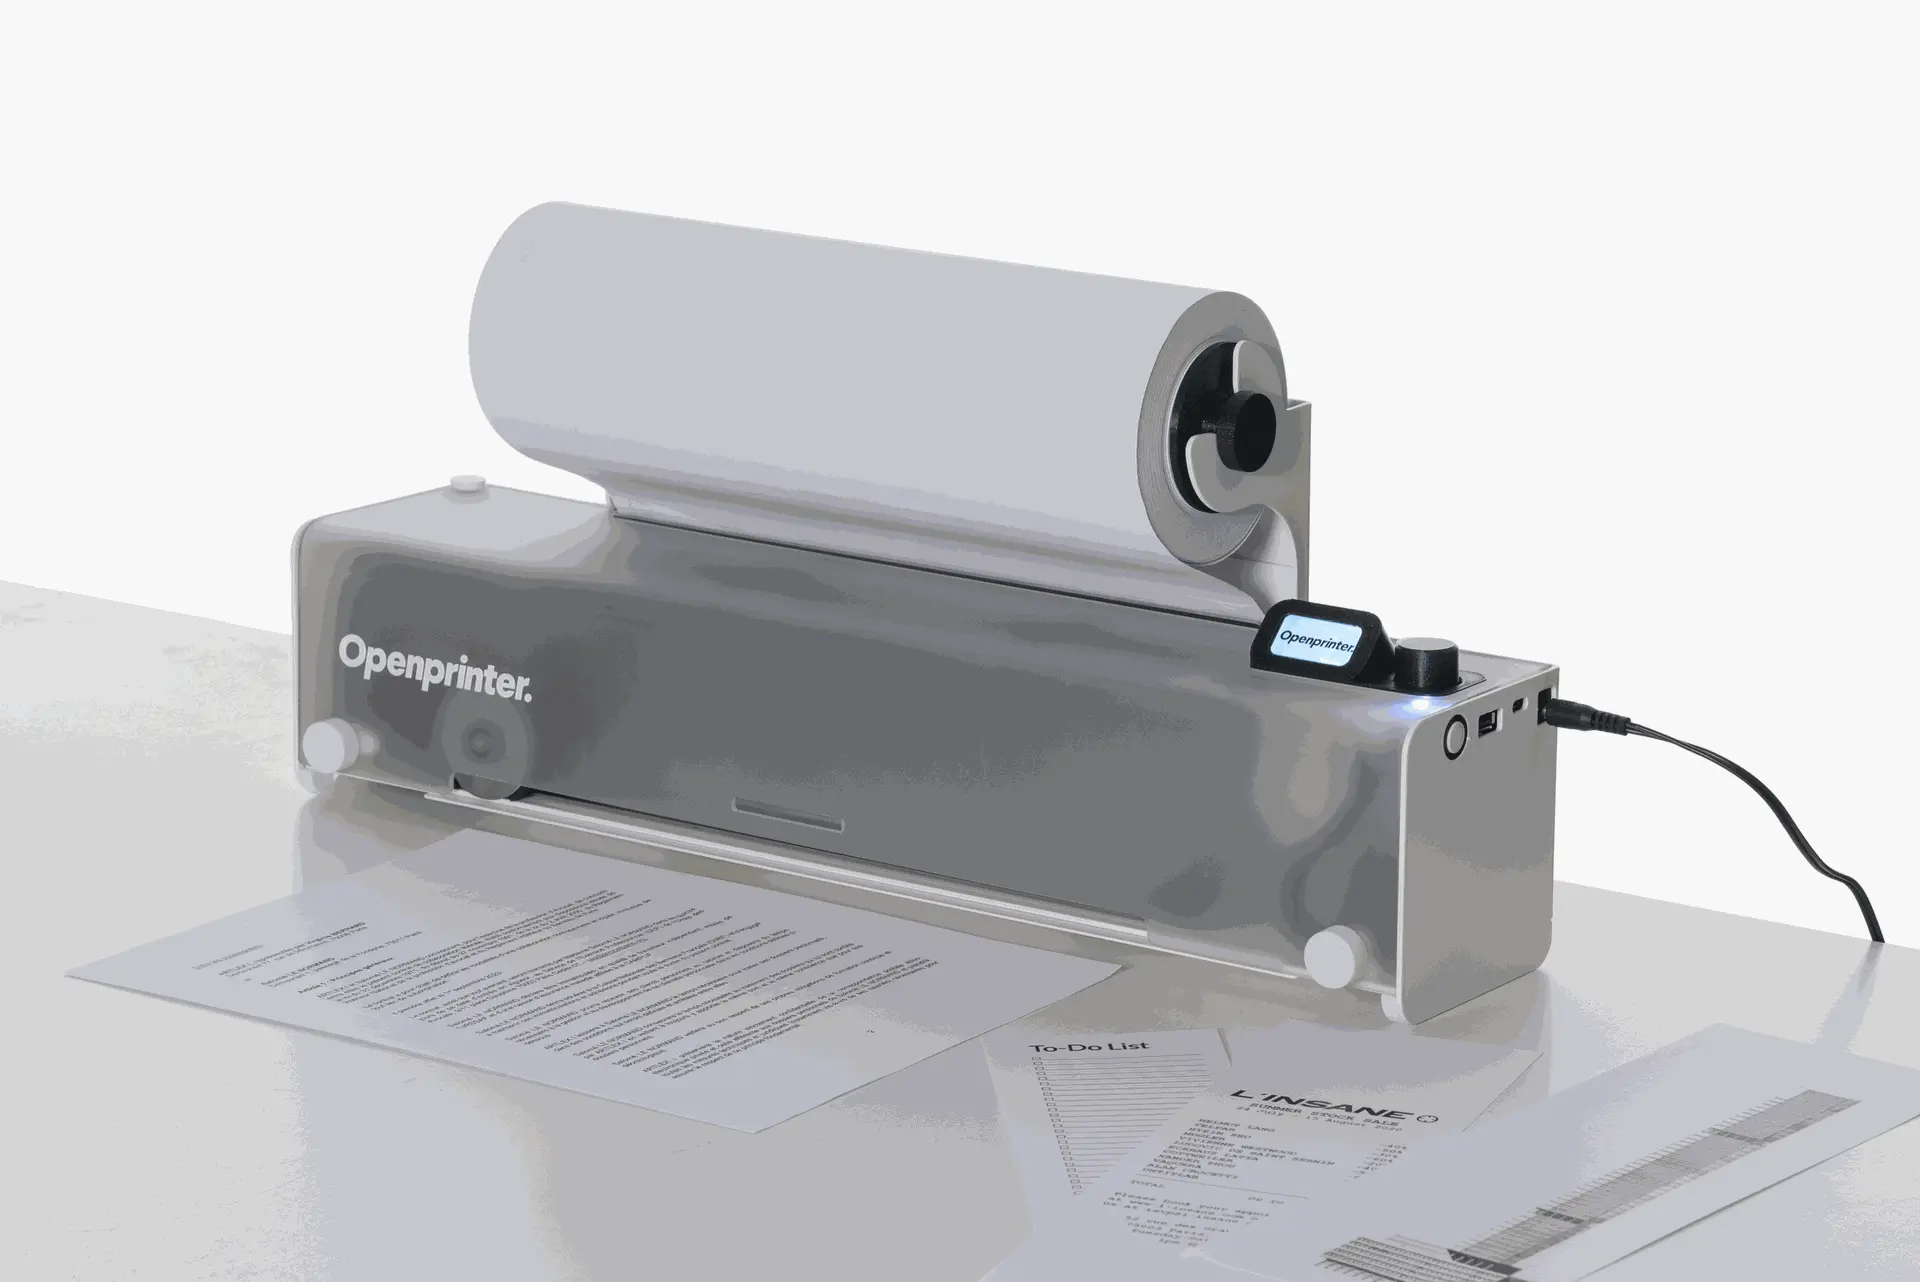
News / #music Tag Music 500 articles archived under #music · RSS Sign in to follow Hacker News — AI on Front Page community 4mo ago OpenPrinter Article URL: https://www.opentools.studio/ Comments URL: https://news.ycombinator.com/item?id=48797916 Points: 372 # Comments: 101 18 r/LocalLLaMA community 4mo ago is LM Link just too uncooked/experimental? Newbie here. Setup LM Studio with Gemma and QWen, setup a local SearXNG container, verified that it works in the browser, linked LM Studio and the SearXNG instance using rzk/searxng-search. Everything works locally and both models now retrieve data from the Internet. Enabled LM… 37 TechCrunch — AI news-outlet 4mo ago Midjourney wants Hollywood studios to reveal the details of their AI usage As part of an ongoing legal dispute with three Hollywood studios, Midjourney is seeking to compel those studios to reveal how they use AI themselves. 24 r/LocalLLaMA community 4mo ago RTX3060 12GB + Quadro RTX5000 16GB worth it? Found cheap one RTX5000 16GB is it worth to add to RTX3060? And is it difficult to make them work together in LM Studio? Do I need to use studio drivers and is RTX5000 still supported with driver updates? Or should I just go for 5060Ti instead? Thanks guys!   submitted by… 17 r/LocalLLaMA community 4mo ago Gemma4 with audio input: 16.8 tok/s on Macbook M2 Max 64GB Here's the setup I decided on for embedding gemma4-12b into a Tauri2 desktop app: Native Rust FFI into llama.cpp via llama-cpp-2 (Metal enabled) Model: gemma-4-12b-it-Q5_K_S quantized by Unsloth, Q5_K - Small Audio input is a 607 KB 16-bit mono 16 kHz PCM WAV. Prompt path: Gemma… 38 r/LocalLLaMA community 4mo ago How hot does your Mac get? Ok I now started testing different LLM on my MacStudio and I am just curious. I use Menubar to see the teperatures of the components - and yeah the CPU and Grafic are all quite hot. Average CPU cores are at 62 celsius and all Graphic cores are at over 80 celsius. Ok my mac is… 35 Google DeepMind official-blog 4mo ago Google DeepMind and A24 announce first-of-its-kind research partnership Today, Google DeepMind and A24 are announcing a first-of-its-kind partnership focused on research. The collaboration pairs a world-leading research lab with the industry’s most filmmaker-forward studio to help artists develop new workflows and techniques. This ensures the tools… 13 arXiv — NLP / Computation & Language research 4mo ago Audio-Based Understanding of Audiobook Narration Appeal arXiv:2607.02473v1 Announce Type: new Abstract: Narration is central to the audiobook listening experience, shaping how listeners engage with and understand the content. This work explores how narration qualities shape an audiobook's appeal, noting that their effects can vary by… 38 arXiv — NLP / Computation & Language research 4mo ago Self-Supervised Test-Time Tuning for Packet Loss Concealment arXiv:2607.01823v1 Announce Type: cross Abstract: Packet loss concealment (PLC) reconstructs audio packets that are missing at the receiver, usually with a trained model whose parameters remain fixed at deployment time. This treats the PLC model as static, even though each call… 30 r/LocalLLaMA community 4mo ago [audio.cpp] The Sound of GGML — C++/GGML native ACE-Step, Stable Audio, HeartMuLa, RoFormer, HTDemucs released. 10-Minute Music in 60 Seconds! https://preview.redd.it/yxa9dlzquxah1.png?width=2000&format=png&auto=webp&s=b07c74b8832b26b46531e2fddba19fd2437ce4c6 I just released a big music/audio expansion in audio.cpp . This batch adds music generation , SFX generation , and source separation to the released framework… 22 r/LocalLLaMA community 4mo ago [Benchmark] Kimi K2.7 Code Q3 on Mac Studio M3 Ultra + RTX PRO 6000 over llama.cpp RPC: prefill improves, no changes in token generation/decode I came across this interesting article https://blog.exolabs.net/nvidia-dgx-spark/ while I don't have the DGX spark but it made me curious will this kind of arch speed up my setup for LLMs? Mac can host large models but the prefill speed sucks, so I tested in it on my setup for… 25 Hacker News — AI on Front Page community 4mo ago Sony Deletes 551 Movies PlayStation Owners Paid For Article URL: https://reclaimthenet.org/sony-deletes-551-studiocanal-movies-playstation-owners-paid-for Comments URL: https://news.ycombinator.com/item?id=48747389 Points: 245 # Comments: 122 8 Hacker News — AI on Front Page community 4mo ago FFmpeg 9.1's new AAC encoder Article URL: https://hydrogenaudio.org/index.php/topic,129691.0.html Comments URL: https://news.ycombinator.com/item?id=48747116 Points: 260 # Comments: 89 18 arXiv — Machine Learning research 4mo ago BEST-RQ-2: Contextualize-Then-Predict, a Two-Step Approach for Self-Supervised Audio Representations arXiv:2606.30700v1 Announce Type: cross Abstract: Self-supervised learning enables audio representations that transfer across domains and tasks. We present BEST-RQ-2, an evolution of BEST-RQ that retains frozen randomprojection-based discrete targets while introducing a two-step… 19 arXiv — NLP / Computation & Language research 4mo ago Building a Multimodal Dataset of Academic Paper for Keyword Extraction arXiv:2606.31069v1 Announce Type: new Abstract: Up to this point, keyword extraction task typically relies solely on textual data. Neglecting visual details and audio features from image and audio modalities leads to deficiencies in information richness and overlooks potential… 14 Hugging Face Daily Papers research 4mo ago AVTok: 1D Unified Tokenization for Holistic Audio-Video Generation Abstract AVTok is a unified tokenizer for audio-video generation that uses a dual-stream transformer architecture with shared encoder-decoder and modal-specific queries to create compact one-dimensional latent representations. Generated by Qwen/Qwen2.5-Coder-32B-Instruct… 21 r/LocalLLaMA community 4mo ago [audio.cpp] VibeVoice 1.5B released — 90-min podcast in 22.95 min, 4.08x real-time, 2.86x faster than Python without quantization. Native C++/ggml I’m the author of audio.cpp, a C++/ggml runtime for local audio models. I just added VibeVoice 1.5B support and wanted to share the benchmark because long-form multi-speaker TTS is a good stress test for local inference runtimes. Result on RTX 5090: VibeVoice 1.5B Audio length:… 26 Simon Willison community 4mo ago Nano Banana 2 Lite Nano Banana 2 Lite Also known as Gemini 3.1 Flash Lite Image ( gemini-3.1-flash-lite-image in their API ), this is the "fastest and cheapest Gemini image model, engineered for velocity and scale". I used AI studio to run this prompt: Do a where's Waldo style image but it's where… 30 Ars Technica — AI news-outlet 4mo ago Trump's plan to redesign every .gov website leads to AI-designed horrors A year in, National Design Studio delays plan to update government web standards. 19 r/LocalLLaMA community 4mo ago What's the full local AI "doomsday prepper" kit for cold storage? 16-bit safetensors of LLMs (obv), copies/source codes of Llama.cpp, ComfyUI, vLLM, Kobold, LMStudio, etc, macOS, Linux OSes, Windows 10&11, etc, Rufus (including older ones), various VMs, P-E-W's Heretic/Grimoire,… For those who want to be as paranoid and maximally doomsday prepped as possible, I am curious what the most thorough "doomsday kit" is of things to store offline copies of "just in case", to still be able to use local AI if things go truly crazy to a super extreme level. So far… 23 Vercel — AI dev-tools 4mo ago Build realtime voice agents on AI Gateway AI Gateway now supports audio/voice. You can add realtime voice, text to speech, and speech to text with the same calls you already use for text, image, and video, routed through AI Gateway alongside every other modality. Audio launches with models from OpenAI and xAI . Each… 26 arXiv — Machine Learning research 4mo ago HybridCodec: Modeling Discrete and Continuous Representations for Efficient Speech Language Models arXiv:2606.27627v1 Announce Type: new Abstract: Discrete audio representations have become increasingly popular for building multimodal text-audio systems and integrating audio capabilities into Large Language Models (LLMs). However, numerous studies report performance… 7 arXiv — Machine Learning research 4mo ago A Comparison of Fusion Techniques for Multi-Modal Human Activity Recognition on the HARMES Dataset arXiv:2606.27886v1 Announce Type: new Abstract: Recent advances in Human Activity Recognition (HAR) from wearable sensors have shown that multi-modal deep learning models consistently outperform their uni-modal counterparts. Modalities can include IMUs, RGB cameras, audio… 27 arXiv — Machine Learning research 4mo ago Elastic Time: Dynamic Frame Rate Bottlenecks for Neural Audio Coding arXiv:2606.27320v1 Announce Type: cross Abstract: Neural audio autoencoders have become a core component of compression, feature extraction, and generation. However, while existing systems support variable bitrate, the vast majority of models still operate at a fixed latent… 38 Vercel — AI dev-tools 4mo ago Realtime voice, speech, and transcription now supported on AI Gateway AI Gateway now supports voice and audio models. You can build realtime voice agents, generate speech from text, and transcribe audio to text. This provides the same observability, spend controls, and bring-your-own-key support as text, image, and video models in AI Gateway, with… 17 Vercel — AI dev-tools 4mo ago xAI Grok audio models now available on Vercel AI Gateway xAI's audio models are now live on AI Gateway. Realtime voice, text to speech, and speech to text are all available through the AI SDK with the same routing, observability, and spend controls as your other models. These capabilities are available on the AI SDK 7 release.… 11 r/LocalLLaMA community 4mo ago Any better models in coding for single dgx spark in near future? I’m an owner of single dgx spark with 128 gb unified memory. and I’m hosting through all my local network my ppm over lmstudio. I’m mainly using it for coding,some long document sorting tasks and some sequruty testing. my favorite rn is stepfun step-3.7-flash q3 xxl it’s a bit… 32 r/LocalLLaMA community 4mo ago audio.cpp: 12 audio models (Qwen3-TTS, PocketTTS, VeVo2 etc) in 1 C++/ggml runtime — TTS up to 5x faster than Python on CUDA I’ve been working on audio.cpp , a native C++ inference framework for audio models built on top of ggml. The framework currently has 25 model families, but I want to be precise about its state: 12 are released in the repo now and ready for normal use. I’m not counting anything… 24 r/MachineLearning community 4mo ago Looking for arXiv endorsement (eess.AS or cs.SD) [R] Hi, I'm an undergrad researcher looking for an arXiv endorsement to submit my first paper in the audio/speech processing domain (keyword spotting on microcontrollers). I've submitted to a peer-reviewed IEEE conference and am awaiting results, but want to get a preprint up in the… 26 Vercel — AI dev-tools 4mo ago AI SDK 7 is now available AI SDK 7 is a major release for building production agents in TypeScript. The SDK has grown from model calls and chat primitives into a broader agent platform for developing, running, integrating, and observing agents across text, audio, realtime, image, and video. Every major… 8 Hugging Face Daily Papers research 4mo ago UnityShots: Memory-Driven Multi-Shot Audio-Video Generation with Boundary-Aware Gating Abstract UnityShots is a memory-driven audio-video generation system that maintains consistent subject appearance and audio across video cuts using fixed-size long-term and short-term memory slots with boundary-conditioned gates and discrete cut-type priors. Generated by… 7 arXiv — NLP / Computation & Language research 4mo ago Robustness assessment of large audio language models in multiple-choice evaluation arXiv:2510.04584v2 Announce Type: replace Abstract: Recent advances in large audio language models (LALMs) have primarily been assessed using a multiple-choice question answering (MCQA) framework. However, subtle changes, such as shifting the order of choices, result in… 13 Hugging Face Daily Papers research 4mo ago Wan-Streamer v0.1: End-to-end Real-time Interactive Foundation Models Abstract Wan-Streamer is a unified, end-to-end multimodal model that enables real-time audio-visual interaction through causal attention mechanisms and integrated processing of visual, audio, and text modalities. Generated by Qwen/Qwen2.5-Coder-32B-Instruct We present… 20 arXiv — NLP / Computation & Language research 4mo ago AVOC: Enhancing Hour-Level Audio-Video Understanding in Omni-Modal LLMs via Retrieval-Inspired Token Compression arXiv:2606.24286v1 Announce Type: new Abstract: Multimodal Large Language Models have achieved remarkable progress in short-form audio-video understanding, yet long-form audio-video comprehension remains challenged by limited context windows and severe information redundancy. To… 15 arXiv — NLP / Computation & Language research 4mo ago Poster: Exploring the Limits of Audio-Based Detection of Turkish Phone Call Scams arXiv:2606.24523v1 Announce Type: new Abstract: Scam phone calls exploit vulnerable communities worldwide, yet research on detection has focused almost exclusively on English and other high-resource languages. In low-resource settings such as Turkish, detection is especially… 11 arXiv — NLP / Computation & Language research 4mo ago ParaPairAudioBench: Paralinguistic Pairwise Audio Benchmark for LALM-as-a-Judge arXiv:2606.24648v1 Announce Type: cross Abstract: Large Audio-Language Models (LALMs) have been widely used as judge models for the automatic evaluation of generated speech. However, prior approaches predominantly focus on holistic naturalness, leaving fine-grained… 15 r/LocalLLaMA community 4mo ago GLM 5.2 on Mac Studio Speedup PR Just a heads up for the lucky few 512 gb mac owners: GLM 5.2 is a game changer because prefill speeds stay above 100 t/s at much higher context, and also take less space, so we can run 4 bit quants well above 100k context. See this PR by the oMLX creator:… 5 Hugging Face Daily Papers research 4mo ago Libretto: Giving LLM Agents a Sense of Musical Structure Abstract Libretto provides a structured framework for symbolic music generation and revision using LLM-native grammar and statistical evaluation across musical dimensions. Generated by Qwen/Qwen2.5-Coder-32B-Instruct Generative music systems can now produce impressive audio from… 18 r/LocalLLaMA community 4mo ago CPU-only TTS benchmark: Kokoro 82M vs Supertonic 3 vs Inflect-Nano-v1 (4.6M params), with UTMOS scoring on every sample Ran three open-weight TTS models head to head on CPU. Intel Xeon, 4 cores, 15.6GB RAM, no GPU. Five configs, six text lengths from 12 to 1712 chars, 5 timed reps per cell after warmup, 150 timed runs total. Every audio output scored with UTMOS (utmos22_strong) so quality isn't… 19 Hugging Face Daily Papers research 4mo ago Improving Text-to-Music Generation with Human Preference Rewards Abstract A text-to-music generation system uses reward conditioning, expert iteration, and preference tuning to improve audio quality while maintaining efficiency within a 120M-parameter model framework. Generated by Qwen/Qwen2.5-Coder-32B-Instruct We describe our entry to the… 19 r/LocalLLaMA community 4mo ago EU AI Act requires TEXT from models and providers to be watermarked 2nd August onwards. Everyone here is affected, regardless where you live. Anyone hate the cookie banners ? Those are absolutely nothing in comparison to what is about to come. The AI Act requires lots of things, many people know it requires every AI modified or generated audiofile to be metadata tagged and fingerprint-watermarked from August on (32M$… 9 r/MachineLearning community 4mo ago Recommendations for speech annotation tools [D] I'm looking for human-in-the-loop platforms that allow you to automatically transcribe audio followed by manually fixing the transcriptions and fine tuning the model. Is there a local (not an online service) installable platform for doing this?   submitted by  … 11 r/LocalLLaMA community 4mo ago Qwen code companion on vscode marketplace - thoughts I just came across this extension in vscode few days ago and tried to use with LM studio hosted models and it really is pretty good compared to `continue`, `kilo`, `cline`, `roo` like I felt without much tweaks, gets straight to the point, if any tweaks required u could do… 36 r/LocalLLaMA community 4mo ago Local agent on 4090 - looking for LM Studio settings I have moved on from Ollama to just dink around and instead want to start running a local agent from time to time. With the 24GB of a 4090 (Gigabyte OC edition) that should be quite possible. But no matter what settings I use for context and batching, token generation is slow as… 36 r/LocalLLaMA community 4mo ago Single RTX 3090 (MSI TRio) giving trouble on inference. Hi, I'm having weird issues with my 3090 on inferencerence via lmstudio , it just: unloads the model/ model crashes + nvidia driver resets freezes the pc gives blue/black screen and the computer restarts or straight up restarts everything. I tried running it regularly,… 33 r/LocalLLaMA community 4mo ago Best Harness for Web Searching Looking for opinions on the best software to do web searching resources. What I've tried: LM Studio + plugins Odysseus I think the problem they're both running into is the search engines they're using max out at like, 10 requests per day/hour or something without an api. I don't… 17 Hugging Face Daily Papers research 4mo ago Duration Aware Scheduling for ASR Serving Under Workload Drift Abstract Duration-aware scheduling policies improve ASR serving latency by leveraging audio length as a predictor for processing time, with SJF and HRRN algorithms showing significant median latency reductions while maintaining throughput. Generated by… 26 r/LocalLLaMA community 4mo ago GLM-5.2 can now run locally in llama.cpp and Unsloth Studio. The 2-bit model retains ~82% accuracy after we shrunk it from 1.51TB to 238GB (-84% size). Run on a 256GB Mac or RAM/VRAM setups. GLM-5.2 is the strongest open model to date. Check the graph for the accuracy of each GLM-5.2-GGUF quantization. Full guide:… 35 arXiv — NLP / Computation & Language research 4mo ago ReNikud: Audio-Supervised Hebrew Grapheme-to-Phoneme Conversion arXiv:2606.20179v1 Announce Type: new Abstract: Grapheme-to-phoneme (G2P) conversion for Modern Hebrew is needed for applications like text-to-speech (TTS), but is challenging due to the language's abjad writing system, which leaves vowels largely unwritten, creating substantial… 21 Hugging Face Daily Papers research 4mo ago MaineCoon: Pursuing A Real-Time Audio-Visual Social World Model Abstract MaineCoon represents the first real-time audio-visual autoregressive model for social worlds, achieving high frame rates and long-horizon generation through novel training techniques and inference frameworks. Generated by Qwen/Qwen2.5-Coder-32B-Instruct As an increasing… 21 Page 9 of 10 · 500 articles ← Newer Older →