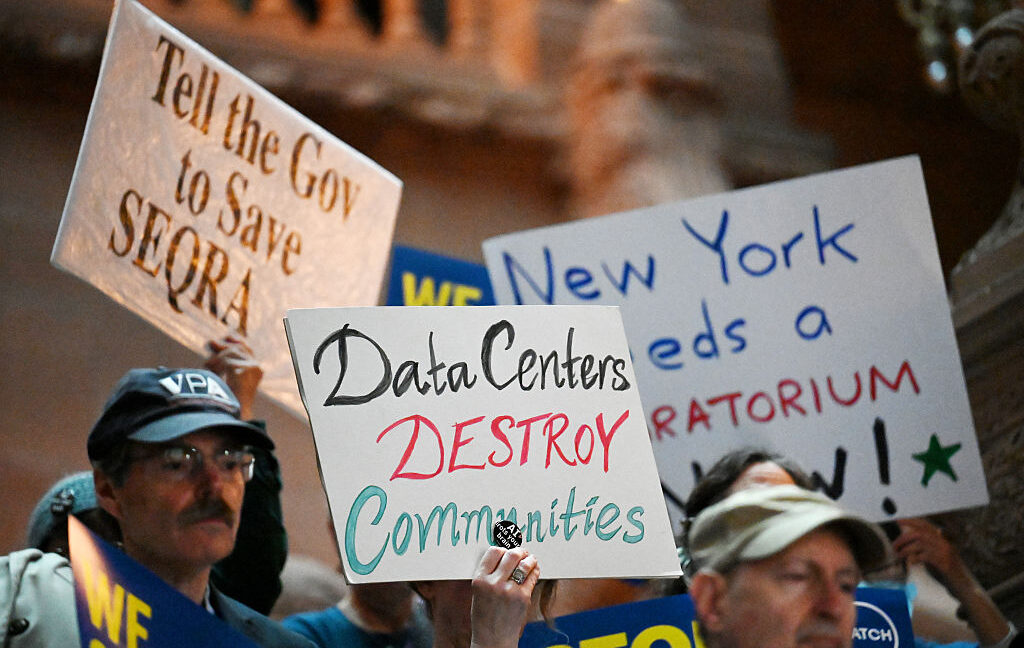
News / #hardware Tag Hardware 500 articles archived under #hardware · RSS Sign in to follow arXiv — Machine Learning research 3mo ago Hierarchical $\mathcal{F}$-Clustering: Approximation and Hardness of Clustering into Trees and Bounded Diameter Graphs arXiv:2607.13217v1 Announce Type: cross Abstract: Consider the following variation on the Hierarchical Clustering problem: Usually, while building a hierarchical clustering, one recursively partitions the data until each cluster becomes a singleton. We relax the halting… 4 r/LocalLLaMA community 3mo ago RL post-training on 14 Macs across 4 countries Disclosure: I work at Pluralis Research, the lab that built this. Code is open, and I'm happy to answer questions. TL;DR: As far as we can tell, this is the first RL post-training run whose entire rollout fleet ran on consumer Macs over the open internet. Setup 14 Macs across 4… 19 Hacker News — AI on Front Page community 4mo ago Mysteries of Telegram Data Centers (2022) Article URL: https://dev.moe/en/3025 Comments URL: https://news.ycombinator.com/item?id=48920475 Points: 221 # Comments: 110 7 arXiv — Machine Learning research 4mo ago Cluster-Weighted EDMD arXiv:2607.12243v1 Announce Type: new Abstract: Extended Dynamic Mode Decomposition (EDMD) approximates Koopman operators from data, but a single global operator is inefficient when different state-space regions exhibit distinct local dynamics. We introduce Cluster-Weighted EDMD… 13 arXiv — Machine Learning research 4mo ago Energy-Based Physics-Informed Form Finding for Clustered Tensegrity Structures arXiv:2607.12888v1 Announce Type: new Abstract: Tensegrity form-finding and physical property prediction are fundamental inverse problems in structural mechanics, which aim to determine equilibrium configurations and internal force distributions. These problems are challenging… 27 Hacker News — AI on Front Page community 4mo ago Jurassic Park computers in excruciating detail Article URL: https://fabiensanglard.net/jurrasic_park_computers/index.html Comments URL: https://news.ycombinator.com/item?id=48915709 Points: 277 # Comments: 62 7 r/MachineLearning community 4mo ago Things I got wrong building an incremental indexing pipeline [P] I've been working on incremental indexing pipelines lately, basically keeping a vector store in sync as the source data changes, and I keep finding the same bugs never show up until it's been running a while. Biggest one for me is deletes. I tested the "new doc comes in, gets… 10 TechCrunch — AI news-outlet 4mo ago OpenAI’s new flagship model deletes files on its own, people keep warning A number of social media posts claim that GPT-5.6 Sol deleted files and data without warning. OpenAI had basically disclosed the problem in June. 11 Hugging Face Daily Papers research 4mo ago A Theory of Contrastive Learning with Natural Images Abstract Why does contrastive learning with simple images and augmentations yield useful representations for downstream tasks? We address this question by analytically computing the optimal representation in terms of a contrastive loss for a range of basic augmentations and any… 33 TechCrunch — AI news-outlet 4mo ago New York State halts construction of all new data centers New York has become the first state to temporarily halt approval of large data centers, as Gov. Kathy Hochul argues the AI-driven building boom shouldn’t come at the expense of higher electricity costs, water supplies, or local control. 27 Ars Technica — AI news-outlet 4mo ago New York bans data center construction for a year, rattling AI industry New York’s data center moratorium may become the blueprint for anti-AI movement. 17 TechCrunch — AI news-outlet 4mo ago Sam Altman’s space data center trash talk is what most experts already believe "homeboy you're the one sellling [sic] public market investors on short-term space datacenters." 5 arXiv — Machine Learning research 4mo ago Group Invariant Spectral Embedding arXiv:2607.08987v1 Announce Type: new Abstract: Spectral embedding methods are widely used for dimensionality reduction and clustering of high-dimensional datasets with intrinsic low-dimensional structures. Although many datasets of practical interest exhibit invariance under… 19 arXiv — NLP / Computation & Language research 4mo ago Relation Extraction Model Based on Semantic Enhancement Mechanism arXiv:2311.02564v2 Announce Type: replace Abstract: Relational extraction is one of the basic tasks related to information extraction in the field of natural language processing, and is an important link and core task in the fields of information extraction, natural language… 9 r/LocalLLaMA community 4mo ago Has anyone gotten Llama.cpp (or other) working using Intel iGPU (arrowlake) where it actually improves anything? I Recently did a bunch of tests and wrote them all up on here, but the short version is that Vulkan basically doesn't work (or when it does, it's at 1tok/s at best). SYCL works pretty well, seems to run the Qwen3.6 35b models at around 12tok/s. The prefill part is around 20tok/s… 17 r/LocalLLaMA community 4mo ago If you use Open Code or other agenting programs you are leaving a lot of t/s if you don't actually use agents in parallel. Benchmark : RTX5090, Qwen3.6 35B loaded via LM studio with parallel tasks set to 8 As many of you know t/s is super important. It's how fast your stuff gets done. I create via open code benchtest and run it. Thanks to it i know that if i don't run at least 4 agents i basically leave HALF of performance. So whatever you do single project in open code that uses… 34 llama.cpp releases dev-tools 4mo ago b9957 server: improve tools, remove apply_diff ( #25498 ) server: improve tools, remove apply_diff improve edit tool add tools_io abstraction add tools_io_basic fix build move utils to class member add const macOS/iOS: macOS Apple Silicon (arm64) macOS Apple Silicon (arm64, KleidiAI… 9 llama.cpp releases dev-tools 4mo ago b9949 opencl: cluster-parallel decode FA for Adreno ( #25473 ) macOS/iOS: macOS Apple Silicon (arm64) macOS Apple Silicon (arm64, KleidiAI enabled) DISABLED macOS Intel (x64) iOS XCFramework Linux: Ubuntu x64 (CPU) Ubuntu arm64 (CPU) Ubuntu s390x (CPU) Ubuntu x64 (Vulkan) Ubuntu arm64… 37 arXiv — Machine Learning research 4mo ago Structure Learning on Clustered Data arXiv:2607.08238v1 Announce Type: new Abstract: Recent algorithmic advances have made directed acyclic graph (DAG) structure learning scalable for causal discovery. Yet, the currently available techniques assume a completely homogeneous population, precluding their application… 6 arXiv — Machine Learning research 4mo ago CASL-VAE: Learning Structured Latent Variables from Unpaired Data for Semi-supervised Clustering and Paired Sample Generation arXiv:2607.08254v1 Announce Type: new Abstract: Quantifying variability in a target population relative to a reference population is central to many scientific and clinical problems (e.g., diseased vs. healthy). Yet, without paired data and in the presence of heterogeneous… 12 arXiv — NLP / Computation & Language research 4mo ago A Multi-cluster Boundary Learning Method for Out-of-Scope Intent Detection via MiniLM Embedding arXiv:2607.07974v1 Announce Type: new Abstract: Intent detection is a critical task that bridges human intents and system actions in human-machine interaction systems. However, there still exist challenges for detecting out-of-scope (OOS) intents. (i) The traditional methods… 35 r/LocalLLaMA community 4mo ago Qwen 3.6 Q2-FP8 Terminal Bench 2 and GPQA Scores TL;DR: Quantization has a marked impact on agentic performance but little effect on knowledge. I manage a small HPC cluster at a university, and we have recently begun running common benchmarks to help our users understand the effects of quantization. We have just completed the… 34 r/LocalLLaMA community 4mo ago Exploring FlashAttention-3/4 optimizations on RTX GPUs I was curious whether any of the FA-3/4 optimizations transfer to RTX GPUs. vLLM/SGLang attention falls back to FA-2 on consumer cards (FA-3 and FA-4 are datacenter-only), so I wanted to know if there's any performance left on the table, and I rebuilt the attention kernels from… 21 Hacker News — AI on Front Page community 4mo ago No leap second will be introduced at the end of December 2026 Article URL: https://datacenter.iers.org/data/latestVersion/bulletinC.txt Comments URL: https://news.ycombinator.com/item?id=48846281 Points: 209 # Comments: 167 18 arXiv — Machine Learning research 4mo ago Converge to Surprise: Evolutionary Self-supervised Image Clustering arXiv:2607.06887v1 Announce Type: new Abstract: Most self-supervised image clustering models, actually almost all deep learning approaches, are based on gradient descent: In order to calculate the loss, every optimization step requires a clearly defined target, whether a… 17 arXiv — Machine Learning research 4mo ago Imputation Meets Clustering: Exploiting Latent Subgroup Structure for Missing Data Recovery arXiv:2607.06930v1 Announce Type: new Abstract: Missing data is prevalent in practical applications, making effective imputation an essential preprocessing step for downstream analysis. Real-world datasets often exhibit complex latent structures composed of multiple subgroups… 18 arXiv — Machine Learning research 4mo ago FMMVCC: Fuzzy Mamba-based Multi-View Contrastive Clustering for Univariate Time Series arXiv:2607.07258v1 Announce Type: new Abstract: In many realistic scenarios, large volumes of time series data are generated with limited or expensive annotations. This limitation makes supervised learning methods difficult to apply and leads to the use of unsupervised… 25 r/LocalLLaMA community 4mo ago What GUI-first coding tool tool are you pairing your local LLMs with? Opencode isn't it for me. I've grown very frustrated with OpenCode. The web GUI and desktop app ideas are good, but the execution not so much. The GUI is lacking so many basic features. It's clear that the TUI is more important to the devs. Is there anything free that provides a more feature-rich GUI?… 14 r/MachineLearning community 4mo ago Why does the same H100 cost 5x more depending on where you rent it? [D] I kept finding wildly different prices for the same GPU across providers and data centers, so I built a OS CLI that searches live GPU capacity and shows the cheapest available routes npx gpu-price-finder Supports RTX 4090, RTX 5090, L40S, A100, H100 and lets you filter by… 20 arXiv — Machine Learning research 4mo ago Learnable Weighting of Intra-Attribute Distances for Categorical Data Clustering with Nominal and Ordinal Attributes arXiv:2607.05464v1 Announce Type: new Abstract: The success of categorical data clustering generally much relies on the distance metric that measures the dissimilarity degree between two objects. However, most of the existing clustering methods treat the two categorical… 19 arXiv — Machine Learning research 4mo ago Breaking Structural Isolation: Scalable Graph Clustering via Community-Aware Sampling and Structural Entropy arXiv:2607.05469v1 Announce Type: new Abstract: Unsupervised graph clustering is a fundamental technique for uncovering underlying semantic patterns in large-scale networks. Although Graph Contrastive Learning has demonstrated promising performance, existing methods often suffer… 30 arXiv — Machine Learning research 4mo ago Modeling Normal Is All You Need: Joint Latent Clustering for Anomaly Detection in Multimodal Cyber-Physical Systems arXiv:2607.06094v1 Announce Type: new Abstract: Faults on a cyber-physical system (CPS) are too rare and unrepresentative to characterise, or even to select a model on, so detection must instead model normal behaviour; the standard point-adjusted evaluation, however, rewards… 26 arXiv — Machine Learning research 4mo ago Performance Optimization and Comparative Analysis of Generative AI Models on Advanced Accelerators arXiv:2607.05400v1 Announce Type: cross Abstract: Generative AI models, such as Large Language Models (LLMs) and diffusion models, have demonstrated impressive performance across a wide range of tasks. Despite these advances, deployment remains challenging due to substantial… 25 Ars Technica — AI news-outlet 4mo ago Data centers’ energy demand threatens Trump’s “Made in America” plan Squeeze on Rust Belt electricity bills threatens Trump’s manufacturing plan. 32 Hugging Face Daily Papers research 4mo ago Speaker-Aware Temporal Aggregation Strategies on Segment Representations for Depression Detection in Dyadic Interaction: A Benchmark Study Abstract Temporal aggregation methods for speech-based depression detection show inconsistent performance across different backbones and training runs, highlighting the need for robust benchmarking criteria. Generated by Qwen/Qwen2.5-Coder-32B-Instruct Speech-based depression… 6 arXiv — Machine Learning research 4mo ago Back to Basics: Improving Molecular Understanding in LLMs via SMILES-Graph Translation arXiv:2607.03007v1 Announce Type: new Abstract: Recent advances in molecular large language models have led to strong performance on molecular understanding and generation tasks, yet these gains often come without reliable structural grounding. In particular, existing approaches… 12 arXiv — Machine Learning research 4mo ago Heterogeneous Graph Condensation via Role-Aware Clustering arXiv:2607.03097v1 Announce Type: new Abstract: Heterogeneous Graph Neural Networks (HGNNs) have exhibited remarkable efficacy in modeling complex systems with multiple types of nodes and relations, yet their training on large-scale heterogeneous graphs remains computationally… 37 Hugging Face Daily Papers research 4mo ago Measuring the Gap Between Human and LLM Research Ideas Abstract Large language models generate research ideas that cluster around specific opportunity patterns and paradigms, diverging systematically from the broader and more diverse distributions found in human research papers. Generated by Qwen/Qwen2.5-Coder-32B-Instruct LLMs are… 21 TechCrunch — AI news-outlet 4mo ago Station F ramps up as a launchpad for Europe’s hottest AI startups Station F, a Paris-based startup hub founded by French billionaire Xavier Niel, is gearing up for a new edition of its F/ai accelerator program in a bid to strengthen its positioning as a stepping stone for promising AI startups. 20 r/LocalLLaMA community 4mo ago GLM 5.2 FP8 with FP8 KV - Terminal-Bench 2.1 = 79.8 (with one time-out that I didnt re-run) I wanted to test the official results vs fp8 + fp8 kv. basic sglang setup on H200. If anyone wants one of the official tests do ping me. I didnt rerun the one so it might go up a bit :) TERMINAL-BENCH 2.1 — FINAL RESULTS (mymodel via mini-swe-agent) TOTAL: 89 tasks PASSED: 71… 17 r/LocalLLaMA community 4mo ago Supra Reasoning Summarizer — a tiny model to summarize thinking traces from coding agents Hi, r/LocalLLaMA ! SupraLabs just released a model called: SupraLabs/reasoning-summarizer-800m-pre-gguf It is a thought trace summarizer. Basically, the user/dev can send a reasoning + tool calls (if you want), and then the model will generate a JSON which looks liek this: {… 4 r/LocalLLaMA community 4mo ago Learning to write AI harness old fashioned way. Need help with attention drift and ignoring tool call results! I've been writing a no-compile node.js based AI Harness for llama.cpp as a learning exercise and can really use some help. I'm basing my code off https://github.com/av/mi and https://pi.dev/ with really basic agentic loops. It basically loop until there are no more tool calls… 7 r/LocalLLaMA community 4mo ago [RELEASE] Supra-Router-51M - a tiny prompt routing model/orchestrator Hey r/LocalLLaMA ! SupraLabs is back with a new model. Supra-Router-51M. Basically, this is a model which is made for routing requests to smaller or bigger models - based on the user prompt/request. This is so cool, because it has only 51M parameters and so it can be used in… 34 r/LocalLLaMA community 4mo ago Considering Buying Another RTX 3090 - Benefits? Currently using dual RTX 3090s, and am happy with it. But never satisfied lol :) I know I've basically maxed out my single stream TPS. (140+ on standard benchmarks now). But I only have 48GB VRAM, So I can only do two concurrent requests @ 256k Context Length, anymore and my… 6 r/LocalLLaMA community 4mo ago Best choice of model 40B+ Parameters currently using Qwen3.6 35B as my main assistant model + coding agent but I think sometimes it misses basical general knowledge things, and it is more like executioner that assistant. That's why I though should I go with bigger models, But I don't want to lose speed I am on… 38 Hacker News — AI on Front Page community 4mo ago GPT-5.5 Codex reasoning-token clustering may be leading to degraded performance Article URL: https://github.com/openai/codex/issues/30364 Comments URL: https://news.ycombinator.com/item?id=48789428 Points: 213 # Comments: 75 28 r/LocalLLaMA community 4mo ago Gemma 4 12B - MLX Kernel I've mentioned this kernel project I was working on in a few posts and figured I would just open the project code for anyone curious: MLX Gemma 12B The main constraints for this on my end is an M5 16GB Macbook Pro. I usually do a model development on clusters in the cloud but… 26 arXiv — Machine Learning research 4mo ago Predicting Closed-Loop Performance of Latent World Models: Offline Checkpoint Selection for MPC and Model-Based RL Under Non-Markovian Rewards in LunarLander arXiv:2607.01736v1 Announce Type: new Abstract: We study how to predict the downstream closed-loop performance of a learned latent world model from validation-time diagnostics alone. Choosing the right checkpoint from a world-model training run is difficult: validation loss and… 17 arXiv — NLP / Computation & Language research 4mo ago ProWAFT: A ROMA-LPD Instance for Workload-Aware and Dynamic Fault Tolerance in FPGA-Based CNN Accelerators arXiv:2607.01602v1 Announce Type: new Abstract: SRAM-based FPGAs provide an attractive platform for energy- and latency-constrained CNN inference at the network edge, yet transient faults can lead to silent errors that compromise reliability. Always-on redundancy (e.g., full… 17 arXiv — NLP / Computation & Language research 4mo ago Evaluating Chunking Strategies for Retrieval-Augmented Generation on Academic Texts arXiv:2607.01852v1 Announce Type: cross Abstract: Retrieval-Augmented Generation (RAG) systems use the question-answering capabilities of Large Language Models (LLMs) to access information outside their parameters. We evaluate if cluster-based semantic chunking improves… 29 Page 10 of 10 · 500 articles ← Newer