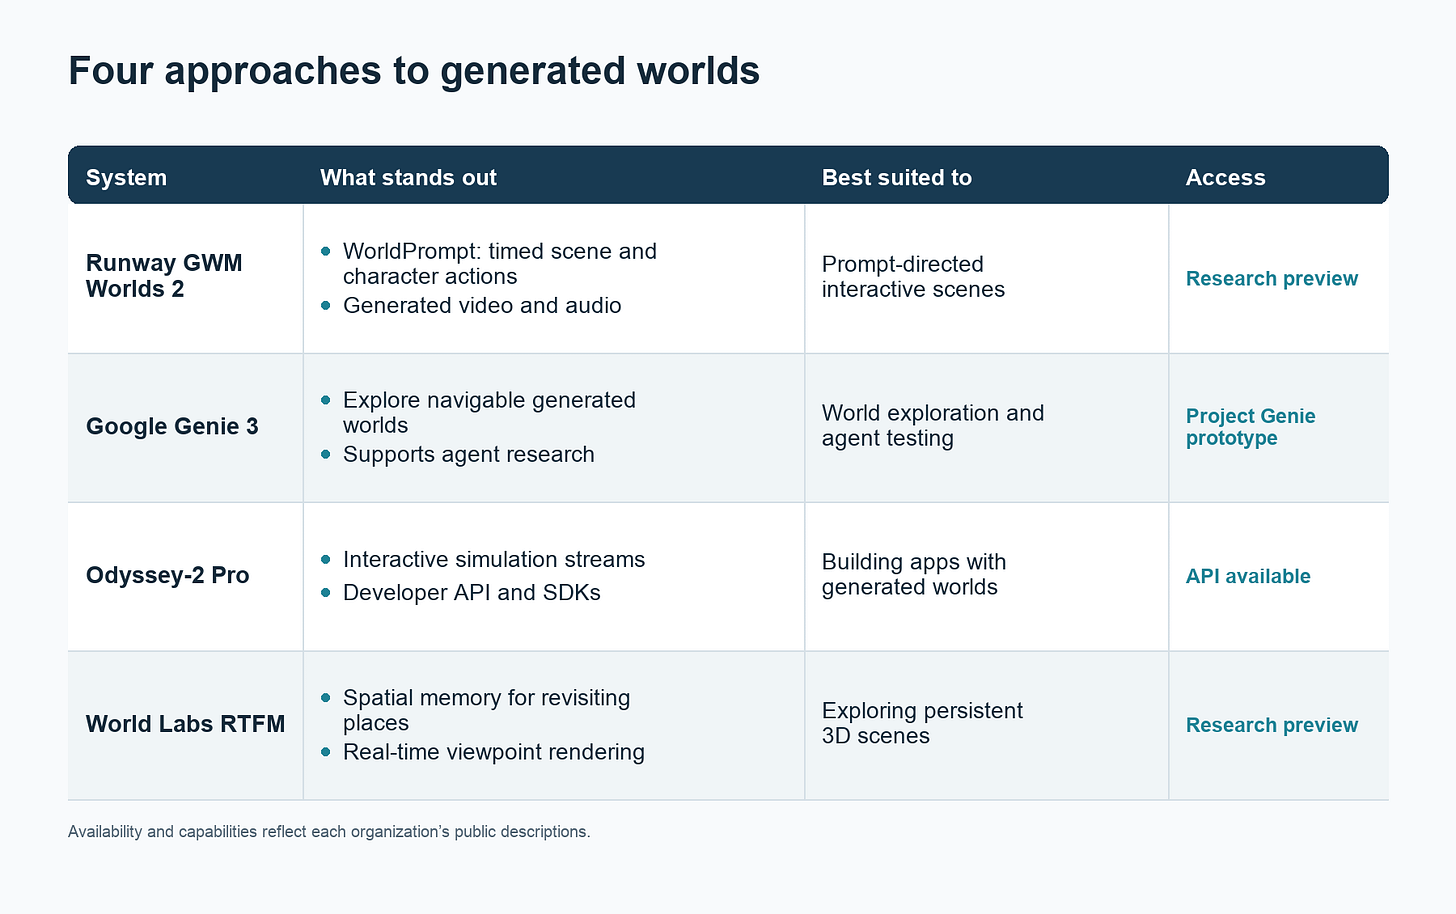
News / #video-gen Tag Video Gen 156 articles archived under #video-gen · RSS Sign in to follow Latent.Space news-outlet 3d ago Runway’s WorldPrompt and the Engineering of Real-Time Worlds GWM Worlds 2 uses persistent context and timed actions to steer a world model generating video and audio in real time. 25 arXiv — Machine Learning research 6d ago Common Cause, Not Cross-Attention: Blocking Visual Shortcuts in Audio-Video Generation arXiv:2609.22361v1 Announce Type: new Abstract: Joint audio--video generators are trained on data in which what an event looks like and what it sounds like are strongly, often spuriously, correlated: a particular material, texture, or object appearance co-occurs with a… 14 Hugging Face Daily Papers research 11d ago VC-Attention: Value Smoothing and Softmax Casting for Low-bit Attention Abstract Diffusion Transformers deliver state-of-the-art video generation, but their long spatiotemporal sequences make attention the dominant deployment cost, and a deployable low-bit kernel must be accurate and fast. Accuracy is limited by outliers: a block's quantization… 4 Hugging Face Daily Papers research 13d ago Vidu S2: Real-Time Interactive, Editable, and Spatial Video Generation Abstract Vidu S2 introduces real-time interactive avatar and video editing models that support high-resolution spatial video generation and dynamic reference updates. Generated by thinkingmachines/Inkling-Small We present Vidu S2, which comprises Vidu S2-Avatar, a real-time… 25 Hugging Face Daily Papers research 18d ago Programmable World Model Abstract A programmable world model separates explicit state evolution from video generation using executable rules and 3D bounding boxes to maintain persistent, controllable environments. Generated by thinkingmachines/Inkling-Small Recent video world models generate… 7 Hugging Face Daily Papers research 18d ago AgenticGen: Reward-Guided Agentic Video Generation for Advertising Abstract AgenticGen improves advertising video generation by decomposing it into strategy selection and draft generation stages supervised by online business feedback and human quality rewards. Generated by thinkingmachines/Inkling-Small Advertising video generation is not only… 34 arXiv — NLP / Computation & Language research 18d ago AgenticGen: Reward-Guided Agentic Video Generation for Advertising arXiv:2609.09187v1 Announce Type: cross Abstract: Advertising video generation is not only a video synthesis task, but also a product-conditioned reasoning problem whose success is measured by online business metrics. Recent video foundation models can generate realistic clips… 23 The Information — AI news-outlet 18d ago Jeffrey Katzenberg Teams Up with Former OpenAI Sora Head on New AI Video Startup Hollywood mogul Jeffrey Katzenberg is teaming up with the former head of OpenAI’s Sora app to launch a new AI startup that would train its own video models and try to win over filmmakers, people familiar with the matter said. The founders have been talking to potential investors… 12 The Information — AI news-outlet 18d ago Jeffrey Katzenberg Teams Up with Former OpenAI Sora Head on New AI Video Startup Hollywood mogul Jeffrey Katzenberg is teaming up with the former head of OpenAI’s Sora app to launch a new AI startup that would train its own video models and try to win over filmmakers, people familiar with the matter said. The founders have been talking to potential investors… 4 Hugging Face Daily Papers research 19d ago Multi-Grid Post-Training for Long-Form Multi-Shot Video Generation Abstract MovieGrid decomposes long videos into spatially arranged chunks for joint modeling, improving multi-shot coherence and scaling video length efficiently. Generated by thinkingmachines/Inkling-Small Generating long-form multi-shot videos requires coherent within-shot… 6 Hugging Face Daily Papers research 24d ago The Missing Temporal Link: Temporal Context Routing for Script-Driven Audio-Video Generation Abstract Temporal Context Routing improves script-aligned timing of shots and dialogue in joint audio-video generation by mapping structured script timing onto shared video-audio temporal axes. Generated by thinkingmachines/Inkling-Small Joint audio-video generation models have… 20 Hugging Face Daily Papers research 26d ago RECAP-Forcing: Retaining Content Appearances for Long Video Generation Abstract RECAP-Forcing improves long video generation by indexing memory according to appearance novelty rather than recency, preserving key-value caches for newly visible content to maintain long-range consistency without extra training. Generated by… 6 Hugging Face Daily Papers research 27d ago DreamX-Creator: Democratizing Native Audio-Video Generation at 2K Resolution Abstract A compact 7B native joint audio-video generator uses cross-modal attention, progressive joint training, reinforcement learning with multimodal feedback, and an autoregressive 2K refinement pipeline to produce synchronized high-resolution outputs. Generated by… 30 arXiv — Machine Learning research 27d ago On the Resilience of Text-to-Video Diffusion Models to Hardware Faults arXiv:2608.29598v1 Announce Type: new Abstract: We present the first systematic study of the resilience of text-to-video (T2V) diffusion models under random hardware-level faults. While T2V models are widely used for automated video generation due to their ability to produce… 19 Hugging Face Daily Papers research 28d ago LayerRecall: A State-Conditioned Memory Router for Long-Horizon Consistency in Video Generation Abstract LayerRecall selectively routes long-range historical memory into specific video diffusion layers to improve long-video consistency, supervised by cross-horizon prediction matching. Generated by thinkingmachines/Inkling-Small Autoregressive video diffusion enables… 32 r/LocalLLaMA community 28d ago Got MiniMax H3 video generation running in TensorSharp I’ve been experimenting with MiniMax H3 and finally have video generation working in TensorSharp. TensorSharp started primarily as a local GGUF/LLM inference engine, so getting a video-generation pipeline working in the same runtime has been an interesting change of direction.… 23 r/MachineLearning community 1mo ago WTF is a World Model? [D] I'm trying to understand what a world model is. I understand it has cognitive science and reinforcement learning. I understand at least at the moment what most people are building which they call world models are fancy video generation models. But what actually counts. Does a… 25 The Information — AI news-outlet 1mo ago SoftBank Explores Buying Majority Stake in 1X Humanoid Maker SoftBank is in talks to buy a majority stake in 1X Technologies, an OpenAI-backed humanoid robot developer, The Information reported late Wednesday . The investment would support SoftBank’s robotics ambition and give 1X more runway to put its soft-bodied bots in customers’… 20 Hugging Face Daily Papers research 1mo ago FIRM-Video: Check Before You Score for Reliable Text-to-Video Reward Modeling Abstract FIRM-Video uses checklist-driven verification of temporal visual evidence to build reliable reward models for text-to-video evaluation and alignment. Generated by thinkingmachines/Inkling-Small Reliable reward models are essential for text-to-video evaluation and… 32 Hugging Face Daily Papers research 1mo ago Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models Abstract Stream4D improves autoregressive video generation by replacing static 3D critics with a dynamic 4D reconstruction reward and motion prior to preserve coherent motion and reduce geometric drift. Generated by thinkingmachines/Inkling-Small Streaming autoregressive… 38 Hugging Face Daily Papers research 1mo ago VGI-BENCH: Probing Visual Intelligence in Video Generation Models Abstract VGI-bench evaluates visual reasoning in video generation models through 27 tasks, revealing limited reliability and minimal self-correction during generation. Generated by thinkingmachines/Inkling-Small Recent studies suggest that video generation models can exhibit… 25 Hacker News — AI on Front Page community 1mo ago EVE Online moves to Python 3 Article URL: https://www.eveonline.com/news/view/the-move-to-python-3-begins Comments URL: https://news.ycombinator.com/item?id=49433328 Points: 232 # Comments: 116 11 Vercel — AI dev-tools 1mo ago AI Gateway now supports asynchronous video generation Video generation on AI Gateway can now run asynchronously. By default, generateVideo keeps one HTTP request to AI Gateway open until the result is ready. Because video generation can take seconds or minutes, that request can exceed request timeouts. With asynchronous generation,… 27 Hugging Face Daily Papers research 1mo ago Partition the Support, Reconstruct the Residual: Training-Free Sparse Attention for Video Generation and World Models Abstract SparsePR accelerates video transformers via response-coupled partitioning and probe-fitted residual reconstruction, reducing attention error at low executed-pair densities with substantial speedups. Generated by thinkingmachines/Inkling-Small Training-free block-sparse… 33 Hugging Face Daily Papers research 1mo ago SemComp-Bench: Benchmarking Semantic Task Completion in Video Generation Abstract Semantic task completion video generation evaluates whether generated videos achieve intended outcomes with semantic grounding, supported by a curated dataset and vision-language model-based benchmark. Generated by thinkingmachines/Inkling-Small We introduce Semantic… 22 Hugging Face Daily Papers research 1mo ago V-RAE: Rethinking Video Latent Spaces for Generation Abstract V-RAE constructs semantically organized video latents from frozen vision representations to improve generation quality, convergence speed, and predictive modeling. Generated by thinkingmachines/Inkling-Small Latent video generation relies on autoencoders to define a… 32 Hugging Face Daily Papers research 1mo ago AnyTalk: Speech Animation for Arbitrary Characters Leveraging a Video Generation Model Abstract AnyTalk generates 3D speech animations for arbitrary characters without animation data by adapting video diffusion models via character-specific fine-tuning and optimizing blendshape parameters from synthesized talking-head videos, with a distilled real-time variant.… 9 llama.cpp releases dev-tools 1mo ago b10472 cuda : skip UMA override for HIP builds ( #27083 ) AMD APUs report accurate memory via hipMemGetInfo. Using MemAvailable over-promises on small-carveout systems. fixes #18159 Website: https://llama.app macOS/iOS: macOS Apple Silicon (arm64) macOS Apple Silicon (arm64, KleidiAI… 28 OpenAI Python SDK releases dev-tools 1mo ago v3.1.0 3.1.0 (2026-08-14) Features api: add WebSocket stream IDs ( #3612 ) ( d9029e3 ) api: add workload identity access token issued event ( #3601 ) ( df274d4 ) api: deprecate Sora video APIs ( #3610 ) ( 721cb1c ) api: Ultrafast tier, structured MCP and websocket errors, separate… 19 Hugging Face Daily Papers research 1mo ago Context-Matched Distillation: Teacher Causality for Autoregressive Video Distillation Abstract Context-Matched Distillation aligns teacher supervision with causal generation context for few-step autoregressive video models, improving control adherence and long-video quality. Generated by thinkingmachines/Inkling-Small Interactive autoregressive video generation… 12 Hugging Face Daily Papers research 1mo ago H2R-Bench: Benchmarking Human-to-Robot Manipulation Video Generation in World Models Abstract H2R-Bench evaluates video generation models on transforming human manipulation videos into robot-centric demonstrations across embodiment constraints and interaction fidelity. Generated by thinkingmachines/Inkling-Small Large-scale manipulation data is essential for… 22 Hugging Face Daily Papers research 1mo ago Alaya-EVOKE: From Linear-Scaling Supervision to Endless World Abstract Evoke is an interactive world model that uses external persistent memory and a redesigned long-horizon teacher to enable responsive, open-ended video generation with bounded context and low latency. Generated by thinkingmachines/Inkling-Small Interactive world models… 34 Hugging Face Daily Papers research 1mo ago AVA-Encoder: Towards Agent-Native Video Representation Learning Abstract AVA-Encoder learns structured video representations via agentic auto-encoding using knowledge graphs to enable cinematic video generation and reasoning with reduced token usage. Generated by thinkingmachines/Inkling-Small Creative agents still lack an effective way to… 30 Hugging Face Daily Papers research 1mo ago Sci-VBench: Evaluating Knowledge- and Reasoning-Intensive Video Generation in Science Domains Abstract Sci-VBench evaluates video generation requiring scientific reasoning across disciplines, revealing that visual realism advances have not ensured accurate scientific and causal dynamics. Generated by thinkingmachines/Inkling-Small We introduce Sci-VBench, a comprehensive… 19 r/LocalLLaMA community 1mo ago MiniMax H3: A New Open-Weight Video Model, Live in ComfyUI MiniMax H3 is an open-weight, general-purpose multimodal video generation model that works across text, images, video, and audio. In ComfyUI, you can use H3 for text-to-video, image-to-video, first- and last-frame generation, and reference-driven creation. H3 jointly generates… 10 Hugging Face Daily Papers research 1mo ago SimWAM: A Simple World Action Model for End-to-End Autonomous Driving Abstract World-Action Models (WAMs) improve end-to-end autonomous driving by transferring video dynamics priors to action prediction, but existing methods require costly future generation at inference. We present SimWAM, a simple yet effective WAM that uses video generation… 19 r/LocalLLaMA community 1mo ago Open-weight video gen that actually delivers. Five days with MiniMax H3 on local hardware. H3 weights went live on HuggingFace August 3rd and I started pulling them immediately. An omni-modal video model with native stereo audio in the same forward pass, where audio can actually drive the video generation? On open weights? I had to try it. Five days in, the quality is… 31 Hugging Face Daily Papers research 1mo ago MiniWorld: Democratizing the Training of Video World Models from Scratch Abstract Video world models predict future observations conditioned on historical observations and control signals, enabling long-horizon generation through autoregressive state transitions. Unlike conventional video generation models that primarily capture visual appearance and… 18 r/LocalLLaMA community 1mo ago [Deepseek-V4-Flash-0731] Full 1M context on a single RTX5090 + DDR5 Desktop Setup with VLLM CPU/Ram Offloading, ~800 tps pp & 15+ tps decode [Agentic Coding] First of all, obviously I took some help from AI to type this post and this is the topic that enabled me to accomplish all that: https://old.reddit.com/r/LocalLLaMA/comments/1veow4b/deepseek_v4flash_284b_moe_at_33_toks_single_68/ This post of mine is based on the link above. My… 11 Hugging Face Daily Papers research 1mo ago WorldExam: Benchmarking World Models from Apparent Appearance to Inherent Reactivity Abstract Controllable video generation models are increasingly being developed as world models. Accordingly, evaluating them in this role extends beyond the apparent appearance of generated videos to the inherent reactivity of the worlds they depict: the ability to infer from… 6 Hugging Face Daily Papers research 1mo ago VideoCoCo: Code-as-CoT for Physically-Consistent Video Generation via an Agentic Dual-Engine System Abstract Text-to-video models have achieved remarkable visual quality, yet they still struggle to generate physically consistent dynamics because the temporal evolution of a scene must be inferred implicitly from a highly compressed text prompt. Existing chain-of-thought… 11 Vercel — AI dev-tools 2mo ago MiniMax H3 now available on AI Gateway MiniMax H3 is now available on AI Gateway. H3 generates 2K video from a text prompt, a starting image, a pair of first and last frames, or reference material. Alongside text-to-video and first-frame image-to-video, the model supports first-to-last keyframe transitions and… 25 Hugging Face Daily Papers research 2mo ago Parallel Decoding Distillation for Fast Image and Video Generation Abstract Generation in video diffusion or flow models is computationally expensive due to the slow and iterative sampling process. Current state-of-the-art (SOTA) acceleration methods heavily rely on variational score distillation (VSD) and adversarial losses to distill… 31 Hugging Face Daily Papers research 2mo ago FilmBench: A Film-Grade Benchmark for Cinematic Video Generation Abstract Progress in video generation keeps narrowing the visual gap between AI-generated and professionally produced footage, yet most benchmarks still draw prompts from web sources or LLM templates and score them with untrained, generic multimodal models. More fundamentally,… 17 Hugging Face Daily Papers research 2mo ago Sol-Attn: Accelerating Video Generation Inference via On-the-Fly Attention Sparsification Abstract Diffusion transformers are essential for high-fidelity video generation, but long token sequences make attention a dominant inference bottleneck. Training-free dynamic sparse attention alleviates this bottleneck by computing only selected key-value blocks, yet existing… 19 Hugging Face Daily Papers research 2mo ago Closing the Loop: Training-Free Revisit Consistency for Autoregressive Generative Rendering Abstract Recent conditional video generation models have shown promising potentials to transform 3D engine renderings, such as depth maps and untextured geometry, into photorealistic videos for gaming and immersive content creation. These applications require long-horizon… 38 TechCrunch — AI news-outlet 2mo ago Midjourney acquired the astrology app Co-Star The AI lab Midjourney continues to expand its purview beyond image and video generation. 11 Hugging Face Daily Papers research 2mo ago SANA-Video 2.0: Hybrid Linear Attention with Attention Residuals for Efficient Video Generation Abstract We introduce SANA-Video 2.0, a hybrid video diffusion transformer instantiated at 5B and 14B scales under a unified architecture. Designed to generate high-quality video up to 720p on a single GPU, SANA-Video 2.0 matches full-softmax video DiTs in quality while… 19 Hugging Face Daily Papers research 2mo ago GraphVid: Interactive Graph-Controllable Video Generation Abstract Controllable video generation remains challenging due to the difficulty of specifying precise multi-object interactions using text prompts or motion-control inputs that primarily constrain pixel movement. In practice, trajectory-based control often requires users to… 12 TechCrunch — AI news-outlet 2mo ago Runway launches AI model router as generative media gets crowded Runway no longer wants to be just another AI model company. It wants to become the infrastructure layer for generative media. On Thursday, the startup launched Runway Media Router through Runway Dev, its developer platform, released earlier this month, that provides API access… 25 Page 1 of 4 · 156 articles Older →