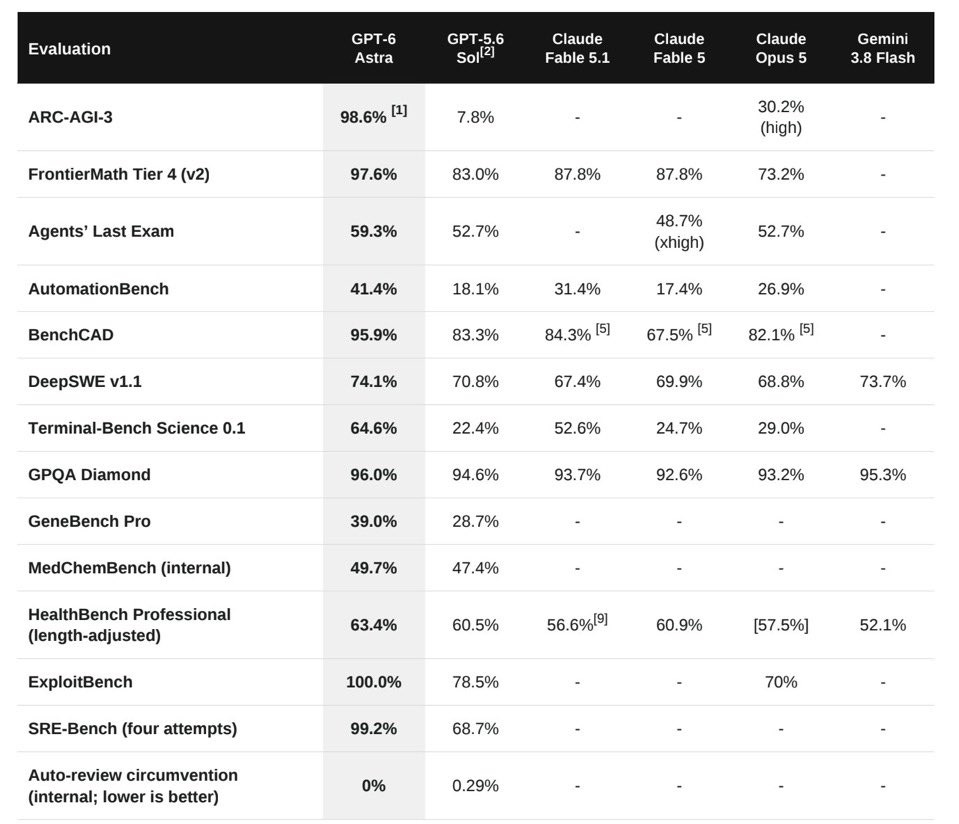
News / #rag Tag Rag 500 articles archived under #rag · RSS Sign in to follow r/MachineLearning community 1d ago Implementing Embedding Gemma from scratch in PyTorch [P]   submitted by   /u/Winter_Mistake_3185 [link]   [comments] 12 Hugging Face Daily Papers research 1d ago A Common Measure of Communication for Speech Brain-Computer Interfaces Abstract Open-vocabulary mutual information provides a unified metric to compare speech brain-computer interfaces across different vocabularies and conditions, revealing trade-offs between vocabulary coverage and decoding accuracy. Generated by thinkingmachines/Inkling-Small… 18 vLLM releases dev-tools 1d ago v0.29.0rc4: [Bugfix] Avoid sync in TRT-LLM ragged prefill Generated-by: Codex [email protected] Signed-off-by: Codex [email protected] 16 llama.cpp releases dev-tools 2d ago b10814 opencl: extend the elementwise and data‐movement op coverage ( #27633 ) opencl: add extended elementwise unary ops (sgn, step, elu, hardswish, hardsigmoid, floor, ceil, round, trunc) Adds nine GGML_UNARY_OP_* elementwise ops that were falling back to CPU on the OpenCL backend,… 14 Hugging Face Daily Papers research 2d ago Locked at the Entrance, Open Inside: Where RLVR Narrows the Solution Space Abstract Reinforcement learning with verifiable rewards narrows reasoning diversity primarily at the initial solution step rather than during execution, and targeted interventions can restore coverage without sacrificing accuracy. Generated by thinkingmachines/Inkling-Small… 23 MIT Technology Review — AI news-outlet 2d ago Architecting memory and storage in the AI era The era of AI inference has arrived. Imagine a healthcare system analyzing millions of data points in real time to accelerate life-saving medical research, or an intelligent assistant instantly resolving thousands of complex customer needs at once. These real-world breakthroughs… 18 r/LocalLLaMA community 2d ago How do you guys handle your personal RAG setup I am getting into developing a RAG setup, for getting information out of existing documents, new document ingestion, web searches, and good visuals. I am planning to use it for, alongside the regular "chat to my data", ingesting personal docs, invoices, creating tables views and… 7 r/MachineLearning community 2d ago How does one approach towards machine learning?[D] I honestly am so confused rn as the ml community is overburst with people only caring about building rag modules and agentic ai for larger corporations. I have a passion for machine learning but honestly it feels really confusing as to what really counts today. I would love some… 24 ThursdAI news-outlet 2d ago Welcome to AGI - our GPT-6 deep coverage, vibe check and demoes - part 2 of this insane week Sorry for the double email, but there was so much news this week, I decided to split the newsletter/pod into two parts. This one is all about GPT-6 Astra. 38 arXiv — NLP / Computation & Language research 2d ago The Geometry of Ignorance: LLMs Know When to Temper Bayesian Priors arXiv:2609.02959v1 Announce Type: cross Abstract: What does a language model predict when it has few clues? The answer lurks in its unembedding geometry: a single direction of the unembedding matrix encodes the unigram distribution of the training corpus, which serves as the… 35 arXiv — Machine Learning research 2d ago Equation Recast for Canonical Operator Learning Across Parametric PDEs arXiv:2609.02982v1 Announce Type: new Abstract: Learning solution operators across broad parameter ranges can require substantial coverage of both input functions and physical parameters, particularly for purely data-driven parametric models. In addition, the resulting models… 34 arXiv — Machine Learning research 2d ago Tail-Likelihood Reinforcement Learning arXiv:2609.02987v1 Announce Type: new Abstract: Reinforcement learning typically optimizes average reward. For generative policies, the average can hide an important distinction: two policies can achieve the same mean reward while having very different chances of producing a… 22 arXiv — Machine Learning research 2d ago ObserverBench: Testing Mechanistic Estimates for Intervention and Control arXiv:2609.03026v1 Announce Type: new Abstract: Mechanistic interpretability is increasingly used to guide interventions such as activation steering, circuit removal, and safety monitoring. Yet an internal estimate that is accurate on average can still choose a poor action. We… 28 arXiv — Machine Learning research 2d ago FlowBalance: Verifier-Grounded Self-Improvement from On-Policy Reasoning Experience arXiv:2609.03241v1 Announce Type: new Abstract: A reasoning model can improve from its own on-policy experience, but this inner loop is fragile: terminal verifiers provide reliable yet sparse supervision, while dense same-model guidance can reinforce false confidence or… 36 arXiv — Machine Learning research 2d ago RATL: Learning from Retrieved Residuals for Robust Multivariate Time-Series Forecasting arXiv:2609.03937v1 Announce Type: new Abstract: Retrieval-augmented generation (RAG) complements parametric models with retrieved external evidence. The same idea is attractive for continuous-output regression, but directly reusing retrieved target values is often not robust… 27 arXiv — NLP / Computation & Language research 2d ago Unifying Conformal Language Tasks with In-Context Ensembles arXiv:2609.03005v1 Announce Type: new Abstract: Many NLP tasks, such as summarization and extractive question answering, reduce to retrieving relevant content from documents under two constraints: coverage, retaining enough pertinent information to achieve some goal, and… 17 arXiv — NLP / Computation & Language research 2d ago R$^{2}$Adapter: A Routing and Rewriting Adapter for Efficient Hybrid RAG arXiv:2609.02894v1 Announce Type: new Abstract: Retrieval-Augmented Generation (RAG) has become a prevailing paradigm for enhancing Large Language Models (LLMs) with non-parametric knowledge. Vanilla RAG efficiently handles simple queries but struggles with relational or… 13 arXiv — NLP / Computation & Language research 2d ago Distilled Rapid Embedding Transfer (DRET): Parameter-Efficient Biomedical Domain Adaptation via Priority-Based Embedding Transfer arXiv:2609.02898v1 Announce Type: new Abstract: Large domain-specific language models such as BioBERT and ClinicalBERT achieve strong performance on biomedical NLP tasks, but their computational demands make them impractical for many real-world deployments. General-purpose,… 14 arXiv — NLP / Computation & Language research 2d ago Listen to the Latents: Self-Correcting Speech Recognition in Large Audio Language Models Through Hidden-State Interactions arXiv:2609.02940v1 Announce Type: new Abstract: Recent automatic speech recognition (ASR) systems increasingly integrate large language models (LLMs) to leverage their semantic knowledge, either externally through logit fusion or internally through warm initialization. However,… 11 arXiv — NLP / Computation & Language research 2d ago Decoupling Turn-Taking from Semantics: A Decoupled Data Approach for Finite-State-Machine-Based Full-Duplex Dialogue arXiv:2609.03321v1 Announce Type: new Abstract: The Neural Finite State Machine (NFSM) framework offers a pragmatic path to full-duplex dialogue by serializing turn-taking control and response generation onto a single causal tape under the standard next-token prediction… 23 arXiv — NLP / Computation & Language research 2d ago When Retrieval Helps: Selective Retrieval for Single-Turn Mental-Health QA arXiv:2609.03454v1 Announce Type: new Abstract: Retrieval-augmented generation (RAG) can improve the specificity and grounding of large language model responses, but its effect is not uniformly beneficial in single-turn mental-health question answering, where user queries often… 17 arXiv — NLP / Computation & Language research 2d ago Pattern Over-Generalization of Knowledge Graph Embedding arXiv:2609.03487v1 Announce Type: new Abstract: Knowledge graph embedding (KGE) demonstrates its effectiveness for predicting missing links in knowledge graphs (KGs) by projecting entities and relations into a low-dimensional vector space. It is crucial for KGE models to… 20 arXiv — NLP / Computation & Language research 2d ago KhatianDoc: A Human-Verified Benchmark Diagnosing Multimodal LLM Failure on Bengali Legal Land Records arXiv:2609.03597v1 Announce Type: new Abstract: Land ownership in Bangladesh is recorded in Ana-Ganda-Kora-Kranti-Til, a base-16 positional fraction system with dedicated Unicode glyphs, no mainstream font, and no coverage in any OCR pipeline or tokenizer. The handwritten… 24 arXiv — NLP / Computation & Language research 2d ago The Impact of Synthetic Data Augmentation on Discourse-Pragmatic Function Classification arXiv:2609.03652v1 Announce Type: new Abstract: Synthetic data augmentation has become a common strategy for addressing class imbalance in NLP, but most approaches focus on the quantity and diversity of generated examples rather than their geometric relationship to real training… 10 arXiv — NLP / Computation & Language research 2d ago Investigating the Ability of Large Language Models to Analyze Recipes for Diabetes arXiv:2609.03967v1 Announce Type: new Abstract: Several studies have evaluated the ability of Large Language Models (LLMs) for meal planning, yielding positive outcomes. These models can process natural language inputs and leverage learned knowledge from their pretraining to… 8 arXiv — NLP / Computation & Language research 2d ago Who Speaks for the Pruned? Visual Token Pruning as Coverage Optimization arXiv:2609.03158v1 Announce Type: cross Abstract: Visual token pruning reduces the inference cost of vision-language models (VLMs), but most methods only ask which tokens to keep. This retained-token view can keep redundant high-scoring tokens while leaving discarded evidence… 31 arXiv — NLP / Computation & Language research 2d ago Rent-a-RAG: Embedding-Space Watermarks for Auditing Third-Party RAG arXiv:2609.03749v1 Announce Type: cross Abstract: Third-party retrieval-augmented generation (RAG) marketplaces create a new auditing problem: data providers may license corpora to a RAG operator, yet later have no visibility into whether their documents are being reused without… 30 Hugging Face Daily Papers research 2d ago CORE: Improving Compositional Reasoning in MLLM Embedding via Reranker Distillation Abstract CORE distills compositional ranking judgments from a cross-attentive reranker into an embedding model via synthesized multi-level candidates and a Rank-KL objective, improving compositional retrieval without degrading standard performance. Generated by… 28 TechCrunch — AI news-outlet 3d ago Meta is paying to peek at how you use their latest AI model For its new Muse Spark model, intended for operating coding and other agents, Meta is offering an explicit discount averaging out to about 95% for users who "contribute" to the development of future models by sharing their prompts and model outputs. 13 Hugging Face Daily Papers research 3d ago Portfolio Risk Bounds without Cross-Asset Return Covariances: Distributional Fields from Language-Model Representations Abstract A framework using distribution-valued firm characteristics and embedding-based representations provides computable upper bounds on portfolio variance and yields low-variance allocations without cross-asset covariance estimates. Generated by… 8 Hugging Face Daily Papers research 3d ago Wasserstein-Barycentric Interaction Fields for Spatial Factor Models: Evidence from Language-Model Representations Abstract A language-model embedding field reconstructed via Wasserstein barycenters predicts peer-misalignment penalties more accurately than conventional weighting schemes. Generated by thinkingmachines/Inkling-Small Spatial return models take the interaction matrix as given… 31 Hugging Face Daily Papers research 3d ago NeoMME: A Single-Tower Multimodal-Native Multilingual Foundation Encoder for Efficient Fine-Tuning and Inference Abstract NeoMME introduces small bidirectional multimodal encoders pretrained with masked discrete diffusion that achieve strong visual document retrieval and high compression of late-interaction embeddings. Generated by thinkingmachines/Inkling-Small Multimodal models often… 21 Hugging Face Daily Papers research 3d ago A Glance Is All You Need: Single-Pass Fine-Grained Image Captioning with SimLoss Abstract SimLoss uses embedding-space contrastive supervision to enable single-pass fine-grained image captioning that matches multi-stage quality at much lower latency. Generated by thinkingmachines/Inkling-Small An image may be worth a thousand words, but most captioning… 19 arXiv — Machine Learning research 3d ago Convergence Theory of Knowledge Distillation in Asynchronous P2P Gossip Learning Network arXiv:2609.01952v1 Announce Type: new Abstract: Decentralized, serverless learning increasingly connects devices running different architectures, where the standard tool, decentralized SGD, is undefined as models with different parameter counts cannot be averaged. Knowledge… 7 arXiv — NLP / Computation & Language research 3d ago The Dynamics of Continuous Mixture Collapse in Language Models arXiv:2609.02049v1 Announce Type: cross Abstract: LLMs latent-state reasoning methods replace discrete intermediate tokens with continuous states, such as weighted mixtures of token embeddings, to retain multiple possible reasoning directions rather than committing to one. Yet… 37 arXiv — Machine Learning research 3d ago TC-Next: Zero-Shot Multimodal Cyclone Forecasting arXiv:2609.02085v1 Announce Type: new Abstract: We present TropicalCycloneNext (TC-Next), a multimodal deep learning model that forecasts tropical cyclone track and intensity at $6$-$24$ h leads by leveraging a foundation model's forecast fields of atmospheric kinematic and… 38 arXiv — Machine Learning research 3d ago Coverage, Not Targeting: A Structural Regime in Multi-Turn Agent Credit Assignment arXiv:2609.02417v1 Announce Type: new Abstract: Multi-turn agentic RL increasingly treats credit assignment as a targeting problem: given a terminal verifiable reward, per-turn methods localize credit onto the turns that mattered. We identify the structural quantity that… 30 arXiv — Machine Learning research 3d ago Source Distribution Estimation by Posterior Averaging arXiv:2609.02622v1 Announce Type: new Abstract: Simulation-based science often requires a distribution over simulator parameters whose push-forward reproduces a set of real observations: this is the source distribution estimation (SDE) problem. Existing methods fit the source… 4 arXiv — Machine Learning research 3d ago Hybrid Retrieval-Augmented Generation with Knowledge Graph Expansion, RRF Fusion, and Per-Chunk Grounded Evaluation for Enterprise Document Search arXiv:2609.01617v1 Announce Type: cross Abstract: Getting accurate, grounded answers out of large enterprise document repositories is a difficult problem. Dense vector retrieval alone frequently performs poorly on queries that mix technical terminology, vendor-specific acronyms,… 18 arXiv — Machine Learning research 3d ago Multi-Agent Retrieval-Augmented Generation for Efficient Cloud Knowledge Base Search in Telecom SNOC Environment arXiv:2609.01618v1 Announce Type: cross Abstract: Telecom Service and Network Operations Centers (SNOCs) rely on large collections of cloud documents, including Standard Operating Procedures (SOPs), vendor technical manuals, incident reports, and configuration guides, to… 9 arXiv — NLP / Computation & Language research 3d ago PRO-Step: Step-level Process Reward Optimization for Retrieval-Augmented Generation arXiv:2609.01658v1 Announce Type: new Abstract: Retrieval-Augmented Generation enhances Large Language Models by grounding responses in external knowledge, but multi-hop reasoning remains vulnerable to error propagation, where early retrieval failures confound subsequent steps.… 32 arXiv — NLP / Computation & Language research 3d ago MemeCULT-1K: Benchmarking South Asian Cultural Context and Humor Understanding of Multimodal Models arXiv:2609.01772v1 Announce Type: new Abstract: Meme understanding goes beyond recognizing visual content or literal text; it requires implicit cultural knowledge and pragmatic inference that most vision-language models still lack. We introduce MemeCULT-1K, a multilingual… 29 arXiv — NLP / Computation & Language research 3d ago VakyArth: Evaluating Pragmatic Competence in LLMs across Indic Languages arXiv:2609.01788v1 Announce Type: new Abstract: Real-world communication often requires pragmatic reasoning: interpreting meanings implied through context and cultural convention rather than stated literally. Existing pragmatic evaluation remains largely limited to English and… 18 arXiv — NLP / Computation & Language research 3d ago Improving Health Literacy through Lay Summarization of Radiological Reports: An Evaluation of BioNER and Retrieval-Augmented Generation arXiv:2609.02396v1 Announce Type: new Abstract: Radiology reports are written primarily for clinicians, and their specialized terminology often makes them difficult for patients to interpret. As a result, many patients turn to publicly available Large Language Models (LLMs) to… 26 arXiv — NLP / Computation & Language research 3d ago PragAlign: Feedback-Guided Pragmatic Alignment for Controlled Synthetic Dialogue Generation arXiv:2609.02480v1 Announce Type: new Abstract: Synthetic dialogue generation can support research in privacy-restricted service settings, but generated conversations must preserve communicative intent, affective meaning, and natural dialogue flow. We introduce PragAlign, a… 14 arXiv — NLP / Computation & Language research 3d ago From Tokens to Semantics: Leveraging Complementary Signals for Hallucination Detection in Black-Box LLMs arXiv:2609.02679v1 Announce Type: new Abstract: When LLMs support public-facing or high-stakes workflows, missed fabrications can harm users and institutions, while false alarms consume limited human-review capacity. When no trusted context or reference document is available, we… 31 arXiv — NLP / Computation & Language research 3d ago DKL: Decoupled Knowledge Learning for Instruction-Tuned Language Models arXiv:2609.02685v1 Announce Type: new Abstract: RAG has become the de facto method for incorporating new, corpus-specific knowledge into an instruction following LLM (Instruct LLM). Although RAG-based prompting improves factual grounding, it fails when retrieval is incorrect or… 36 arXiv — NLP / Computation & Language research 3d ago User Feedback Provides a Unique Signal that LLMs Can not Detect arXiv:2609.02859v1 Announce Type: new Abstract: Harnessing naturally occurring feedback from user interactions offers a promising learning signal for Large Language Models (LLMs). However, recent studies suggest this feedback is inherently noisy and difficult to leverage… 26 arXiv — NLP / Computation & Language research 3d ago ExecRetrieval: Measuring the Functional-Correctness Gap in Code-Embedding Retrieval arXiv:2609.01865v1 Announce Type: cross Abstract: Embedding-based code retrieval is a core component of coding agents and retrieval-augmented code generation, where retrieving correct code matters more than retrieving lexically similar code. Existing code-retrieval benchmarks do… 20 arXiv — NLP / Computation & Language research 3d ago From Detection to Characterization: A Large-Scale Study of Ragebait on Japanese X arXiv:2609.02262v1 Announce Type: cross Abstract: Ragebait refers to online content intentionally designed to provoke anger or outrage and thereby increase attention and engagement. However, reliable large-scale detection and systematic analysis of ragebait remain limited,… 33 Page 1 of 10 · 500 articles Older →