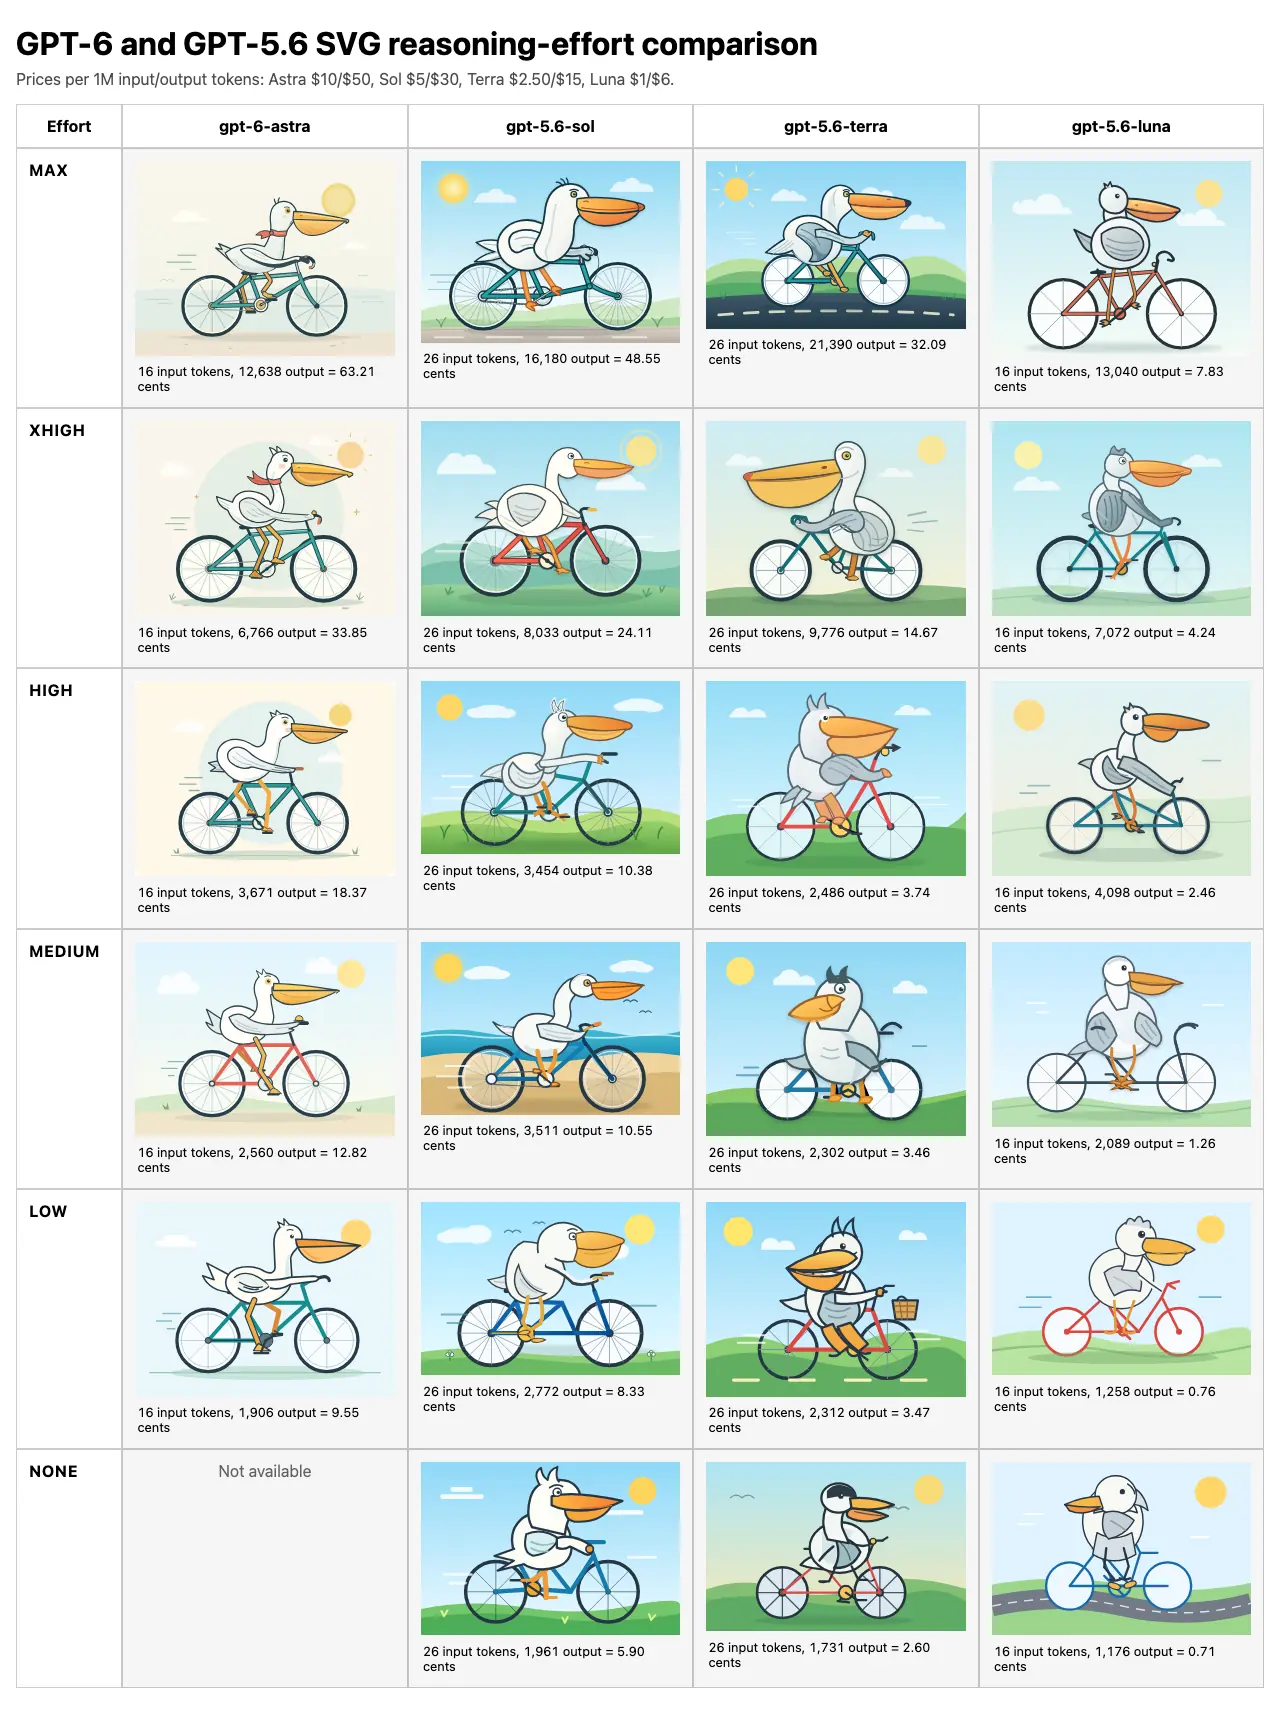
News / #reasoning Tag Reasoning 500 articles archived under #reasoning · RSS Sign in to follow r/MachineLearning community 11h ago Applying Sliding Window Attention to pretrained LLMs at inference time [P] I've been working on a practical implementation of Sliding Window Attention (SWA) for pretrained Hugging Face causal LLMs. The idea is simple: instead of allowing every generated token to attend to the complete historical KV cache, maintain a bounded cache consisting of:… 27 r/MachineLearning community 1d ago GPT-6 reportedly jailbroken within 24 hours using an extended Task-in-Prompt (TIP) attack [N] A researcher has reported a jailbreak of GPT-6 Astra within a day after release. The attack is described as combination of TIP (Task-in-Prompt) attack from ACL 2025 paper with four other unnamed techniques. TIP attacks exploit the model’s reasoning/instruction-following… 17 Simon Willison community 1d ago The Pelican comparison grid for Astra is pretty interesting I got access to GPT-6 Astra this afternoon, so naturally I used it to generate SVGs of pelicans riding bicycles - at low, medium, high, xhigh and max reasoning levels (Astra doesn't support reasoning=none). Then I rendered those pelicans in a comparison grid with GPT-5.6 Sol,… 12 Hugging Face Daily Papers research 1d ago VeriPhy: Agentic Physical Reasoning for World Model Evaluation and Refinement Abstract VeriPhy verifies generated video by compiling prompts into typed physical obligations, executing frozen expert analyses with provenance tracking, and mapping evidence to auditable three-valued verdicts. Generated by thinkingmachines/Inkling-Small Visual fluency in… 12 Hugging Face Daily Papers research 2d ago Locked at the Entrance, Open Inside: Where RLVR Narrows the Solution Space Abstract Reinforcement learning with verifiable rewards narrows reasoning diversity primarily at the initial solution step rather than during execution, and targeted interventions can restore coverage without sacrificing accuracy. Generated by thinkingmachines/Inkling-Small… 23 r/LocalLLaMA community 2d ago Ling-3.0-flash-VL, built on Ling-3.0-flash with visual understanding and visual agent capabilities It performs well across visual perception, STEM reasoning, document intelligence, multimodal agent tasks, frontend coding, and medical report interpretation.   submitted by   /u/niacolhealth [link]   [comments] 6 NVIDIA Developer Blog official-blog 2d ago Frontier Reasoning Reaches the Edge: How to Deploy and Optimize Models on NVIDIA Jetson Running reasoning and agentic AI at the edge has been harder than it needs to be. Until recently, models capable of multi-step reasoning were too large to run... 17 r/LocalLLaMA community 2d ago Even Qwen3.8 followed the instruction inside my translation data, and Gemma 4 beat the translation specialists I tested A month ago I posted about Gemma sometimes solving the reasoning problems inside my translation data instead of translating them . A few people suggested two very fixes, which is to use a proper translation model and/or use JSON with structured decoding. So I tested them those… 28 Hugging Face Daily Papers research 2d ago Principia: Relational Physics Tests for Video Models Abstract Principia evaluates video generators on Newtonian physics via calibration-independent relational consistency across paired objects, revealing major physical reasoning gaps. Generated by thinkingmachines/Inkling-Small Evaluating physical reasoning in video models is… 37 Hugging Face Daily Papers research 2d ago Beyond Retrieval: Progressive Latent Memory Evolution for Streaming Video Understanding Abstract LatentStream introduces a progressive latent working memory framework that internalizes streaming visual evidence into compact evolving tokens for continuous reasoning. Generated by thinkingmachines/Inkling-Small Streaming video understanding requires multimodal large… 27 arXiv — Machine Learning research 2d ago The Gradient Does Not See Rank: Rank-Indifference in Matrix-CODI on ProsQA arXiv:2609.03090v1 Announce Type: new Abstract: Continuous chain-of-thought models compress reasoning into latent tokens. Matrix-valued variants, which route each latent token through a d x d matrix bottleneck, introduce rank as a single-sample structural observable on the… 15 arXiv — Machine Learning research 2d ago Frontier LLMs are effective batch optimizers: Assessing reasoning models in continuous and discrete settings arXiv:2609.03177v1 Announce Type: new Abstract: Frontier large language models (LLMs) have become attractive priors for optimization due to their large-scale pretraining that enables them to navigate a variety of optimization settings. However, the effectiveness of modern… 14 arXiv — Machine Learning research 2d ago Language-encoded network topology enables large language models to reason about complex networks arXiv:2609.03229v1 Announce Type: new Abstract: Networks describe systems in biology and beyond, from protein interactions and social relationships to power grids and citation records. Reasoning about such systems requires understanding their structure: which elements are… 7 arXiv — Machine Learning research 2d ago FlowBalance: Verifier-Grounded Self-Improvement from On-Policy Reasoning Experience arXiv:2609.03241v1 Announce Type: new Abstract: A reasoning model can improve from its own on-policy experience, but this inner loop is fragile: terminal verifiers provide reliable yet sparse supervision, while dense same-model guidance can reinforce false confidence or… 36 arXiv — Machine Learning research 2d ago DE-Venus: A Data-Efficient RLVR Framework for Large Language Models arXiv:2609.03324v1 Announce Type: new Abstract: Reinforcement learning with verifiable rewards (RLVR) improves large language model reasoning, but its practical scaling is constrained by expensive on-policy rollouts and the cost of obtaining reliable targets at scale. Existing… 22 arXiv — Machine Learning research 2d ago Gradients Know What Outcomes Don't: Unlocking Reinforcement Learning for LLM Reasoning with Gradient-Aligned Rewards arXiv:2609.03342v1 Announce Type: new Abstract: Reinforcement learning from verifiable rewards (RLVR) drives chain-of-thought reasoning in large language models, yet its binary outcome reward cannot distinguish among correct trajectories. Existing dense reward alternatives, from… 6 arXiv — Machine Learning research 2d ago RecurTrace: Adaptive Latent Reasoning with Loop-Time Memory arXiv:2609.03379v1 Announce Type: new Abstract: Repeating a small block of middle layers increases a language model's effective inference depth without adding parameters or generating extra tokens, and recent work shows that this latent recurrence improves reasoning. However,… 6 arXiv — NLP / Computation & Language research 2d ago It's the Problem, Not the Path: Budget and Difficulty Confounds in LLM Reasoning Trajectories arXiv:2609.03436v1 Announce Type: cross Abstract: Reasoning traces of large language models are widely read as containing "breakthrough" moments and early-legible fates. Both readings rest on measurements missing a counterfactual control at the level of the claim; we supply both… 10 arXiv — Machine Learning research 2d ago Headroom-Drift Replay: A Primitive for Principled Replay Control in GRPO arXiv:2609.03941v1 Announce Type: new Abstract: RL-based post-training for reasoning models is increasingly bottlenecked by repeated fresh rollout generation, particularly in agentic settings where environment interaction dominates wall-clock cost. Replay can reduce this burden… 35 arXiv — NLP / Computation & Language research 2d ago Bounded Personas Match Retrieval on Classification but Not Regression for a Frozen Agent arXiv:2609.02890v1 Announce Type: new Abstract: A personalized language agent must convert a user's interaction history into behavior on each new request at inference time. Two strategies dominate. Retrieval pulls a few of the user's most relevant past items into the prompt,… 8 arXiv — NLP / Computation & Language research 2d ago Judging LLM-as-a-Judge: Concerning Rubric Artifacts in LLM-based Automated Text Generation Evaluation arXiv:2609.02942v1 Announce Type: new Abstract: LLM-as-a-Judge pipelines are increasingly used to evaluate AI-generated text, based on the assumption that judgments arise from reasoning over candidate responses with respect to a rubric. We show that this assumption warrants… 12 arXiv — NLP / Computation & Language research 2d ago Random Attention: Rethinking KV Cache Eviction for Efficient Reasoning arXiv:2609.03430v1 Announce Type: new Abstract: Large language models achieve superior performance on tasks that require extended reasoning, but long chains of thought make the KV cache a severe memory bottleneck. Existing KV cache compression methods share one paradigm: score… 17 arXiv — NLP / Computation & Language research 2d ago Lost in Reordering: Structural Sensitivity of Multilingual LLMs under Semantics-Preserving Perturbations arXiv:2609.03511v1 Announce Type: new Abstract: Large Language Models (LLMs) demonstrate strong multilingual reasoning performance, yet their robustness to semantics-preserving structural variation remains underexplored, particularly for relatively free word-order languages. We… 4 arXiv — NLP / Computation & Language research 2d ago Remember and Reweight: Enhancing Multi-Agent Debate with Experience Memory and Confidence Estimation arXiv:2609.03619v1 Announce Type: new Abstract: Multi-agent debate (MAD) improves the reasoning capabilities of large language models by having multiple agents iteratively refine their responses through discussion. However, MAD suffers from a critical vulnerability known as… 23 arXiv — NLP / Computation & Language research 2d ago </think> Doesn't Stop Reasoning: Analysis of Spurious CoT Termination arXiv:2609.03633v1 Announce Type: new Abstract: Chain-of-thought (CoT) reasoning improves large reasoning models (LRMs) on complex tasks but often produces long, redundant traces. Recent training-free early-exit methods shorten these traces by choosing an intermediate point to… 7 arXiv — NLP / Computation & Language research 2d ago A Circuit for Plural Reference: How LLMs Represent and Retrieve Singular and Plural Entities arXiv:2609.03687v1 Announce Type: new Abstract: Coreference resolution is an important task in contextual reasoning. In this paper, we investigate the mechanism for representing and retrieving singular and plural entities for plural reference. We use a combination of mechanistic… 18 arXiv — NLP / Computation & Language research 2d ago Beyond Shallow Alignment: How Post-Training Methods Determine Refusal Circuits And Steering Robustness arXiv:2609.03887v1 Announce Type: new Abstract: How do the methods used to train language models to refuse harmful requests shape how that refusal actually works inside the model? We compare three post-training methods - supervised fine-tuning, reasoning-augmented fine-tuning… 8 arXiv — NLP / Computation & Language research 2d ago Sequential Beats Joint: On the Interplay between On-Policy Distillation and RLVR arXiv:2609.04108v1 Announce Type: new Abstract: Reinforcement learning with verifiable rewards (RLVR) and on-policy distillation (OPD) have emerged as two dominant methods for post-training reasoning LLMs. Prior work uses OPD's dense token-level supervision to complement the… 38 arXiv — NLP / Computation & Language research 2d ago Legibility is Not Interpretability: Comparing Judged and Actual Importance in Chain-Of-Thought Reasoning arXiv:2609.04194v1 Announce Type: new Abstract: Reasoning traces from chain-of-thought models appear to offer a legible window into how a model arrives at its answer. A growing body of work treats them as such, using LLM judges to diagnose errors, evaluate faithfulness, and… 16 arXiv — NLP / Computation & Language research 2d ago MedQA-MM: Shortcuts Behind Medical Visual Reasoning arXiv:2609.03261v1 Announce Type: cross Abstract: A benchmark score credits final answers, but not the route by which an item can be answered. In medical multimodal multiple-choice questions (MCQs), this distinction matters because a correct answer can be supported by the… 11 Hugging Face Daily Papers research 2d ago Random Attention: Rethinking KV Cache Eviction for Efficient Reasoning Abstract Random eviction of reasoning tokens matches selective KV cache compression because reasoning traces are self-protecting through redundancy, making scoring unnecessary once prompts are preserved. Generated by thinkingmachines/Inkling-Small Large language models achieve… 22 Hugging Face Daily Papers research 2d ago CORE: Improving Compositional Reasoning in MLLM Embedding via Reranker Distillation Abstract CORE distills compositional ranking judgments from a cross-attentive reranker into an embedding model via synthesized multi-level candidates and a Rank-KL objective, improving compositional retrieval without degrading standard performance. Generated by… 28 Hugging Face Daily Papers research 2d ago Why Gated DeltaNet Survives 4-Bit Quantization: NVFP4 W4A4 for the Recurrent Half of a Hybrid 27B LLM Abstract Fully quantizing hybrid LLMs—including recurrent Gated DeltaNet layers—to 4-bit NVFP4 preserves accuracy across long-context and reasoning benchmarks by localizing outliers and exploiting robust delta-rule dynamics. Generated by thinkingmachines/Inkling-Small Hybrid… 30 vLLM releases dev-tools 2d ago v0.29.0rc3 [CI] Remove deleted nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-BF1… 33 r/LocalLLaMA community 2d ago Increasing active parameters per token in MOE (Qwen 35B A4B+) reduce reasoning token by 8.5% - and you don't need to train or finetune! I want to share a short paper just published exploring a simple but surprisingly effective optimization for sparse MoE reasoning models. The idea: Instead of retraining anything, we just tweak the router at runtime . Specifically, we expand the expert selection budget (N≥K N ≥ K… 24 Hugging Face Daily Papers research 2d ago WHALE: A Simple Recipe for Joint Harness-Weight Optimization Abstract WHALE alternates model weight updates and harness search to jointly optimize agent performance across reasoning tasks. Generated by thinkingmachines/Inkling-Small Agent performance depends jointly on the model parameters and the executable harness code that manages… 20 Hugging Face Daily Papers research 3d ago FoldingAgent: Inferring Parametric Origami Procedures from Demonstration Videos Abstract FoldingAgent uses a vision-language model with specialized tools to convert origami videos into executable parametric folding programs via sequential reasoning and physical verification. Generated by thinkingmachines/Inkling-Small We present FoldingAgent, an agentic… 23 Hugging Face Daily Papers research 3d ago Post-Training Language Models for Gold-Medal Performance in Coding Competitions Abstract A specialization pipeline combining curated problems, synthetic reasoning, supervised fine-tuning, and reinforcement learning trains competitive programming models that exceed top human scores on IOI benchmarks using iterative test-time refinement. Generated by… 16 Hugging Face Daily Papers research 3d ago Autoregressive Mosaics: Probing 2D Spatial Reasoning in Text-Only Language Models Abstract Text-only large language models vary in open-ended 2D layout ability despite reliable geometry-to-code translation, with performance shaped by output medium and internal tracking of evolving geometric state rather than fixed plans. Generated by… 18 arXiv — NLP / Computation & Language research 3d ago The Dynamics of Continuous Mixture Collapse in Language Models arXiv:2609.02049v1 Announce Type: cross Abstract: LLMs latent-state reasoning methods replace discrete intermediate tokens with continuous states, such as weighted mixtures of token embeddings, to retain multiple possible reasoning directions rather than committing to one. Yet… 37 arXiv — Machine Learning research 3d ago GeoSPRINT: Geometric Redundancy-Aware Step Pruning for Inference in Diffusion Trajectories arXiv:2609.02160v1 Announce Type: new Abstract: Diffusion models achieve high sample quality but remain expensive at inference time because sampling requires many sequential neural function evaluations (NFEs). Existing acceleration methods either use fixed step-skipping… 20 arXiv — Machine Learning research 3d ago AGI Maze Prediction Datasets: A Compact Benchmark for Learning World Dynamics with Transformers arXiv:2609.02339v1 Announce Type: new Abstract: World modeling requires a predictive model to maintain and update an internal state adequate for reasoning about the consequences of actions. We introduce the AGI Maze Prediction Datasets and Benchmark, a lightweight controlled… 9 arXiv — Machine Learning research 3d ago Cliff: Learning Process Rewards from the First Mistake arXiv:2609.02817v1 Announce Type: new Abstract: Reinforcement learning with verifiable rewards (RLVR) has emerged as a powerful paradigm for large language model (LLM) post-training, but its reliance on coarse outcome rewards leads to limited guidance on intermediate reasoning… 32 arXiv — Machine Learning research 3d ago Post-Training Language Models for Gold-Medal Performance in Coding Competitions arXiv:2609.02849v1 Announce Type: new Abstract: Competitive programming has become a key test of large language model reasoning, with international competitions such as IOI and ICPC representing its most challenging settings. We present an end-to-end specialization pipeline… 34 arXiv — Machine Learning research 3d ago Context Inference Attacks Without Jailbreaks arXiv:2609.01663v1 Announce Type: cross Abstract: Agentic AI systems are increasingly deployed to process sensitive data at inference time, such as healthcare records or financial documents assembled into a hidden \emph{context} before the system answers. Prior work has studied… 20 arXiv — NLP / Computation & Language research 3d ago PRO-Step: Step-level Process Reward Optimization for Retrieval-Augmented Generation arXiv:2609.01658v1 Announce Type: new Abstract: Retrieval-Augmented Generation enhances Large Language Models by grounding responses in external knowledge, but multi-hop reasoning remains vulnerable to error propagation, where early retrieval failures confound subsequent steps.… 32 arXiv — NLP / Computation & Language research 3d ago VakyArth: Evaluating Pragmatic Competence in LLMs across Indic Languages arXiv:2609.01788v1 Announce Type: new Abstract: Real-world communication often requires pragmatic reasoning: interpreting meanings implied through context and cultural convention rather than stated literally. Existing pragmatic evaluation remains largely limited to English and… 18 arXiv — NLP / Computation & Language research 3d ago Thinking effort aligns between humans and reasoning models in abductive reasoning arXiv:2609.01867v1 Announce Type: new Abstract: A major question in cognitive modeling concerns the behavioral alignment between large language models and humans across linguistic and non-linguistic tasks. Unlike standard LLMs, large reasoning models (LRMs) are optimized with… 6 arXiv — NLP / Computation & Language research 3d ago IDEEA: training-free Input-Dependent stEEring via Activation cluster matching arXiv:2609.02089v1 Announce Type: new Abstract: Steering aligns large language models (LLMs) by injecting a bias into selected activations at inference time, offering a far cheaper alternative to weight-update methods such as supervised fine-tuning or reinforcement learning.… 35 arXiv — NLP / Computation & Language research 3d ago C$^{3}$T: Counterfactual Causal Reasoning for Sentiment Shifts in Social-Media Conversation Trees arXiv:2609.02131v1 Announce Type: new Abstract: Sentiment in social-media threads does not only vary across posts; it shifts as users react to claims, corrections, evidence, and hostility within a branching reply tree. We study why sentiment changes in rumor-centric conversation… 15 Page 1 of 10 · 500 articles Older →